

 Repository
Current collected state Current
Observed since 20 Oct, 17:25 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
Autoencoder based iterative modeling and multivariate time-series subsequence clustering algorithm (ABIMCA)

This repository contains the python code for the Autoencoder Based Iterative Modeling and Subsequence Clustering Algorithm (ABIMCA)1 which is a deep learning method to separate multivariate time-series data (MTSD) into subsequences. It is beneficial in a variety of fields, to cluster MTSD into smaller segments or subsequences in an unsupervised manner. The ability to filter measurement data based on specific subsequences can improve downstream development products such as anomaly detection or machine diagnosis in condition based maintenance (CbM) strategies. Our algorithm is specifically useful for MTSD generated by a mechatronic system in a transient environment. It can be used offline as well as online for streaming data. It utilizes recurrent neural network (RNN) based Autoencoders (AE) by iteratively training a Base Autoencoder (BAE), generating a segmentation score and saving the intermediate parameters of the BAE to recognize previously identified subsequences.
Package can be installed with pip
$ pip install abimca
or clone the repository, and cd into the directory. Then recommendation is to create a virtual environment after installing and using python 3.9 with pyenv
python -m venv .venv
activate the environment Linux: $ source .venv/bin/activate
Windows cmd: C:> .venv\Scripts\activate.bat
Then install with poetry
$ poetry install
Finally run the minimal example in main.py
$ python -m main
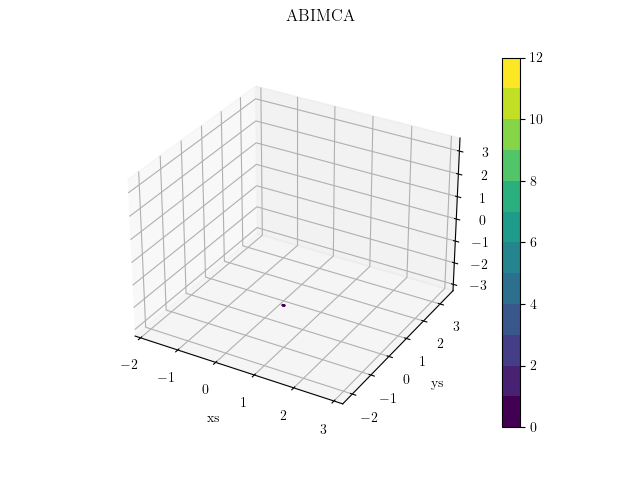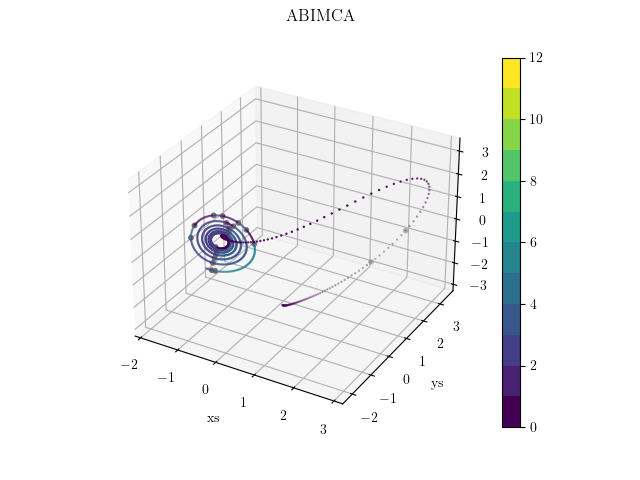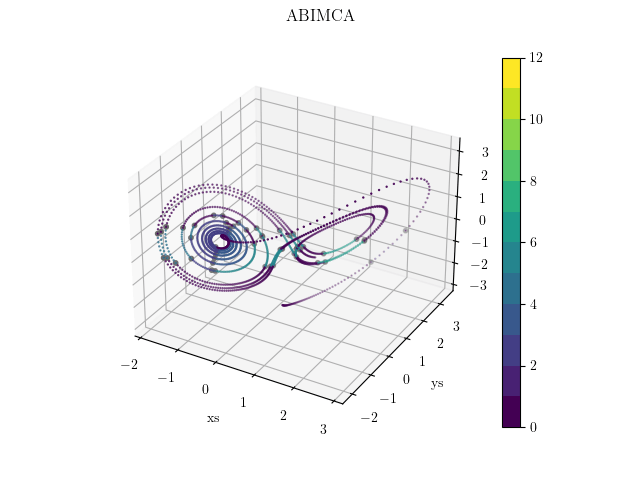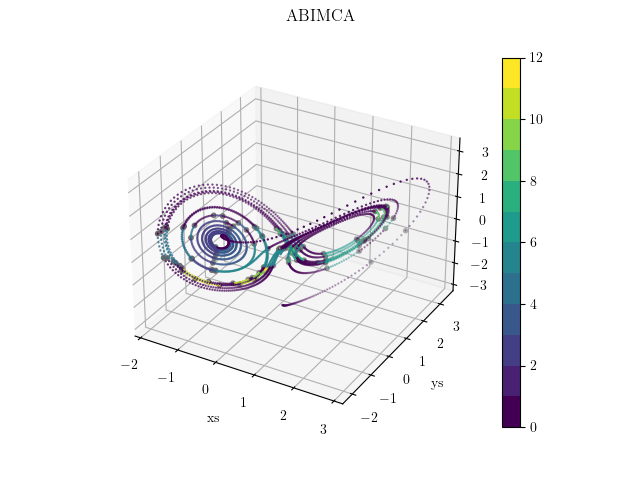
The above graphic example was generated with the run_lorenz.py script. The minimal example is as follows:
from abimca import SubsequenceIdentifier
import numpy as np


def main():
    # Generating random data. This will produce no class predictions or all points have the same class. For more reasonable results replace the data input with your mechatronic measurement data.
    # Number of datapoints (time-steps)
    n_p = 300
    # Number of dimensions or features
    dim = 5
    X = np.random.rand(n_p, dim)
    # Number of clusters
    n_c = 5
    y = np.random.randint(n_c, size=n_p)

    # Compute online clustering
    si = SubsequenceIdentifier(disable_progress_bar=False)
    si.fit(X)
    print(f"Label array from online fitting: \n{si.label_array}")

    # Compute offline clustering
    labels = si.predict(X)
    print(f"Label array from online fitting: \n{labels}")


if __name__ == "__main__":
    main()
Köhne, J. et al. Autoencoder based iterative modeling and multivariate time-series subsequence clustering algorithm ↩
Download counts and popularity will appear here as the collector receives them.
| Version | Published | Direct dependencies | Open version |
|---|---|---|---|
| 0.2.5 | 8 Sept 2022 | 8 |
This describes our collected data; it is not a security assessment.
Observed since 20 Oct, 17:25 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
package:991f08e04ad4daa21c0dbf3683def0ff3d39a39459a0d3b256226bfbae2b4f25