
 Repository
Current collected state Current
Observed since 20 Oct, 18:40 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
Production-grade two-tier persistent memory for AI agents: local-first by default, Redis + Qdrant for scale
Persistent memory for AI agents, so they never forget who you are.



Documentation · Quickstart · Framework integrations · Changelog · Blog
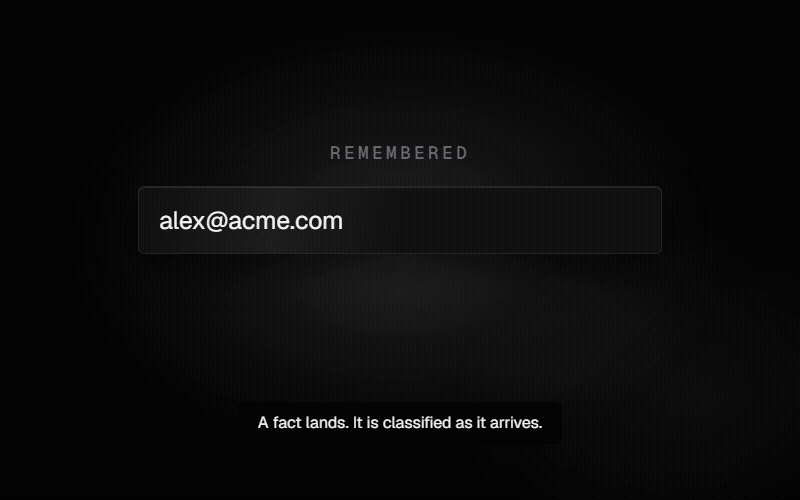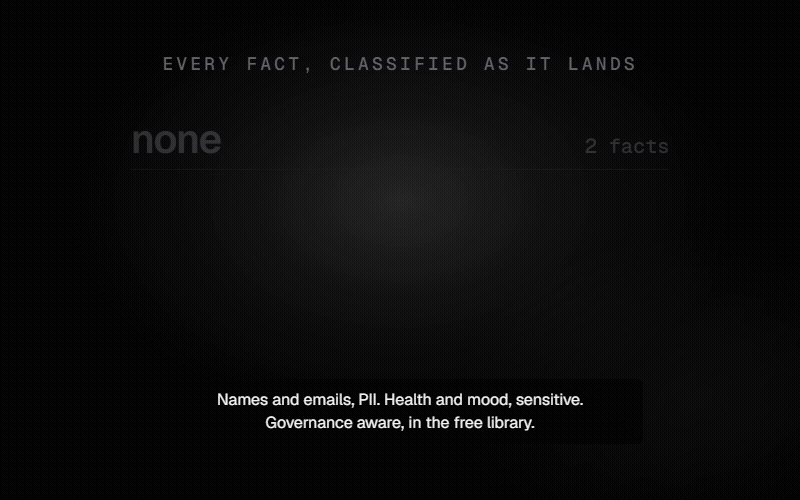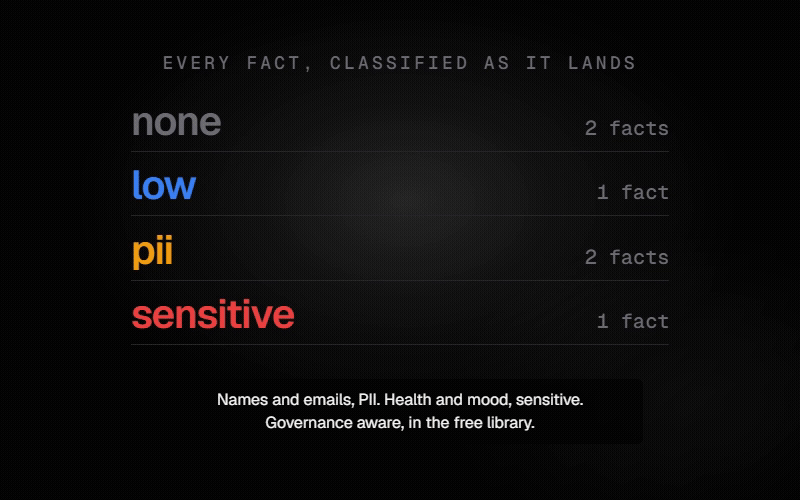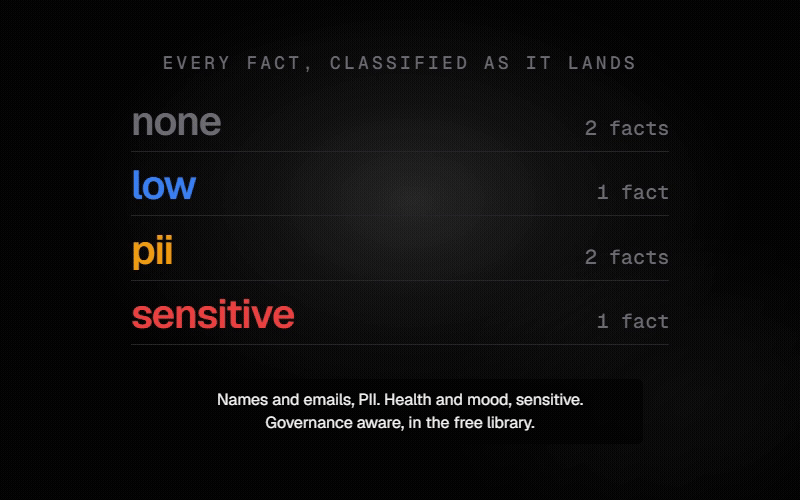
Watch the one-minute walkthrough, narrated (1:1 and 9:16 cuts.)
By default, AI agents are goldfish. They forget everything the moment a conversation ends, and even during a long conversation once the context window fills up.
This library gives your agent a proper memory system: a fast short-term memory for recent messages, and a long-term memory that stores and searches through everything the agent has ever learned.
Without actrone-memory            With actrone-memory
─────────────────────────         ──────────────────────────────
User: "My name is Alex"           User: "My name is Alex"
AI:   "Hello Alex!"               AI:   "Hello Alex!"

[new session]                     [new session]

User: "What's my name?"           User: "What's my name?"
AI:   "I don't know your name."   AI:   "Your name is Alex."
pip install actrone-memory
Recommended for real semantic recall that still runs entirely on your machine:
pip install "actrone-memory[onnx]" # in-process ONNX embeddings, no key, no service
With framework adapters:
pip install "actrone-memory[langchain]"   # for LangChain users
pip install "actrone-memory[langgraph]"   # for LangGraph users
pip install "actrone-memory[crewai]"      # for CrewAI users
pip install "actrone-memory[all]"         # everything
Sixteen framework adapters are available. See the compatibility matrix for the full list and tested version ranges.
You'll need: Python 3.11+. That's it. The default backend is fully local and in-process, so there are no services to run and no API key to get started. Memory that never phones home.
For durable, horizontally-scalable production, opt into the Redis + Qdrant backend (see Going to production). Both start instantly with Docker:
docker run -d -p 6379:6379 redis:7.2-alpine
docker run -d -p 6333:6333 qdrant/qdrant:v1.9.2
import asyncio
from actrone_memory import create_memory_manager

async def main():
    # Local-first by default: in-memory store + a dependency-free embedder.
    # No Redis, no Qdrant, no OpenAI key required.
    # create_memory_manager() closes the manager for you on exit; use
    # `memory = await MemoryManager.create()` if you want to manage that yourself.
    async with create_memory_manager() as memory:
        # Save what the user said
        await memory.store_turn(
            agent_id   = "my-agent",
            session_id = "session-1",
            user_message      = "My name is Alex and I'm building a trading bot.",
            assistant_message = "Nice to meet you, Alex! What asset class are you targeting?",
        )

        # Before the next reply, fetch everything relevant
        context = await memory.retrieve_context(
            agent_id     = "my-agent",
            session_id   = "session-1",
            query        = "What should I watch out for?",
            token_budget = 4096,   # how many tokens you can spare for memory
        )

        print(f"Loaded {len(context.recent_turns)} recent turns")
        print(f"Loaded {len(context.episodic_memories)} long-term memories")

asyncio.run(main())
What you just got. The default embedding provider is local, which picks the best
offline embedder available and degrades gracefully with no configuration and no key:
fastembed (in-process ONNX)   →   sentence-transformers   →   lexical hashing
   [onnx] extra                      [local] extra              always available
   real semantic recall              real semantic recall       keyword-overlap only
With the bare pip install actrone-memory you land on the last rung: deterministic
keyword-overlap recall, which is ideal for tests and local dev but is not semantic, and the
library says so once with a warning on stderr. Add pip install "actrone-memory[onnx]" for
real semantic recall that still never leaves your machine: "food allergies" then finds "The
user is allergic to peanuts." The first run downloads the model (about 130 MB); later runs
load it from the cache offline. Or set ACTRONE_EMBEDDING_PROVIDER=openai if you would
rather use a cloud model (see Privacy and PII first).
Each built-in embedder carries the similarity threshold it was calibrated for, because
scores are not comparable across models: the lexical embedder scores relevant text around
0.24, while bge-small scores unrelated text around 0.48. memory.relevance_threshold shows
the value in use, and ACTRONE_RELEVANCE_THRESHOLD overrides it.
Two independent switches. Flip them when you need durability and/or semantic recall. Both default off so you can start with zero setup.
# Durable, horizontally-scalable backend (Redis L1 + Qdrant L2)
export ACTRONE_BACKEND=redis_qdrant
export ACTRONE_REDIS_URL=redis://localhost:6379
export ACTRONE_QDRANT_URL=http://localhost:6333

# Semantic embeddings (choose ONE)
export ACTRONE_EMBEDDING_PROVIDER=openai        # needs the key below
export ACTRONE_OPENAI_API_KEY=sk-...
# ...or run fully offline with a real model:
#   pip install "actrone-memory[local]"
#   export ACTRONE_EMBEDDING_PROVIDER=local     # sentence-transformers, no key
No code changes. The same MemoryManager.create() reads these at startup.
| Tier | Shipped implementations |
|---|---|
| Hot session (L1) | in-process (default), Redis, Postgres |
| Long-term semantic (L2) | in-process (default), Qdrant, Postgres + pgvector |
ACTRONE_BACKEND selects the two wired-by-env combinations, memory or redis_qdrant.
The Postgres stores are passed to create() directly (see below), because they take a DSN
or a pool you already own.
Redis-compatible servers work with the Redis adapter unmodified. It uses only standard
commands (RPUSH, LTRIM, LRANGE, EXPIRE, SET NX EX, hashes, pipelines), so
Valkey, DragonflyDB, ElastiCache and Upstash need no separate adapter. Valkey is covered
by its own integration suite (tests/integration/test_valkey_compatibility.py), which runs
the full conformance suite against a real Valkey container rather than assuming it.
If you already run Postgres, both tiers can live there and you add no service at all.
Install pip install "actrone-memory[pgvector]", which needs the
pgvector extension for the long-term tier.
import asyncpg
from actrone_memory import MemoryManager
from actrone_memory.l1.postgres_store import PostgresStore
from actrone_memory.l2.pgvector_store import PgVectorStore

# One pool for both tiers, owned by your application.
pool = await asyncpg.create_pool("postgresql://localhost/mydb")

l1 = PostgresStore.from_pool(pool)
l2 = PgVectorStore.from_pool(pool, dimensions=1536)
await l1.ensure_schema()
await l2.ensure_schema()

memory = await MemoryManager.create(l1=l1, l2=l2)
Or let each store own its own pool with await PostgresStore.from_dsn(dsn) and
await PgVectorStore.from_dsn(dsn, dimensions=1536).
Postgres has no TTL or list trimming, so the L1 store implements both explicitly: an
expires_at column filtered on read and cleaned opportunistically on write, and a retention
cap enforced on append. Honest trade-off: Redis is faster for the hot path, and the long-term
tier is the one where replacing a whole extra service matters most.
The built-in adapters have no privileged access: they implement L1Store and L2Store like
anything else would. Any engine that can satisfy those typing.Protocol seams plugs in
without touching the manager, and the store you pass is used as-is, so no built-in backend is
constructed or connected behind it.
from actrone_memory import MemoryManager

class MyWeaviateStore:            # structural, no subclassing required
    async def upsert(self, entry): ...
    async def search(self, agent_id, query_embedding, threshold, limit=20,
                     content_types=None, query_text=None): ...
    async def delete(self, memory_id): ...
    async def delete_agent_memories(self, agent_id): ...
    async def close(self): ...

memory = await MemoryManager.create(l2=MyWeaviateStore())
Two things worth knowing before you write one:
hybrid_rank
helper, which recomputes cosine locally. It raises a clear error rather than returning
silent zeros if none of your candidates carry one. If your database ranks server-side and
does not return vectors (Pinecone needs include_values), use fuse_channels with its own
scores instead, the way QdrantStore does.try_acquire_summary_lock must be a single atomic operation (Redis SET NX EX,
Postgres INSERT ... ON CONFLICT ... WHERE expires_at <= now()), never a read then a
write, or concurrent workers will all summarise the same session.To make that a supported extension point rather than a claim, the package ships the same conformance suite the built-in stores are held to:
import asyncio
from actrone_memory.testing import check_l1_store, check_l2_store

asyncio.run(check_l2_store(lambda: MyWeaviateStore(...), dimensions=1536))
It checks the behaviours the type system cannot: turns come back oldest-first, n windows
from the end, a search never returns another agent's memories, threshold, limit and
content_types are honoured, an upsert replaces rather than duplicates, erasure is scoped,
and a summary lock admits one holder. Each failure raises ConformanceError naming the
requirement. actrone-memory/testing is the TypeScript equivalent, against the same
contract, so an adapter in either language is held to the same bar.
The manager does not depend on those classes directly. It depends on two
typing.Protocol seams, L1Store and L2Store (actrone_memory.protocols), so any
other engine (pgvector, Weaviate, Pinecone, Valkey, Postgres, and so on) works by
implementing the protocol and passing your instance to create():
from actrone_memory import MemoryManager

class MyPgVectorStore:          # structurally satisfies L2Store, no subclassing needed
    async def upsert(self, entry): ...
    async def search(self, agent_id, query_embedding, threshold, limit=20,
                     content_types=None, query_text=None): ...
    async def delete(self, memory_id): ...
    async def delete_agent_memories(self, agent_id): ...
    async def close(self): ...

memory = await MemoryManager.create(l2=MyPgVectorStore())
Anything you inject is used as-is and the matching built-in backend is never built, so injecting a store opens no connection to Redis or Qdrant. Injecting both stores keeps the library entirely free of database drivers.
There is no built-in adapter for those other engines and none is planned as a hard dependency: keeping the base install free of database drivers is the point.
This library is local-first by default: the built-in embedder runs in-process and fact extraction is
opt-in, so with the defaults (ACTRONE_EMBEDDING_PROVIDER=hashing/local, extraction off) nothing leaves
your machine: no API key, no egress. It is also cloud-capable, e.g.
ACTRONE_EMBEDDING_PROVIDER=openai, or any OpenAI-compatible extractor.
Important, and this is exactly where PII protection holds. The sensitivity classification (none/low/pii/sensitive) is
produced by the extraction step, and that step (and any real embedder) sees the raw text. So PII
protection here holds only for local models (in-process / a local Ollama endpoint, so zero-egress). If you
set a cloud provider, the raw text, including PII-classified content, is sent there. This library does
not tokenise it first.
Redaction on read. To keep tagged personal data out of what you send a model, turn on redaction for
every read with ACTRONE_REDACT_SENSITIVITIES='["pii", "sensitive"]' (or
MemoryConfig(redact_sensitivities=[...])), or for one call with redact=:
ctx = await memory.retrieve_context(agent_id, session_id, query, 4096, redact=["pii", "sensitive"])
# A fact tagged pii comes back as "[redacted: pii]", with its embedding dropped.
It covers retrieve_context() and search_memories(), and so every framework adapter built on them.
Stored memories do not change, and redact=[] turns it off for a single call. It acts only on tags: raw
turns are never classified, so they are never masked, and the library does not detect personal data on its
own.
Actrone's hosted platform, when it launches, will add MAL (Memory Abstraction Layer) to tokenise PII before inference, so cloud models never receive the raw values. It has not launched yet. Short form: local-first by default; cloud-capable; PII stays on your machine only with local models.
Think of it like a human brain. There is a working memory for what just happened, and a long-term memory for everything else.
┌─────────────────────────────────────────────────────────────────┐
│                        MemoryManager                            │
│                                                                 │
│  ┌──────────────────────────┐   ┌───────────────────────────┐  │
│  │     SHORT-TERM (Redis)   │   │    LONG-TERM (Qdrant)     │  │
│  │                          │   │                           │  │
│  │  The last 50 messages    │   │  Compressed summaries     │  │
│  │  of this conversation.   │   │  of older conversations.  │  │
│  │                          │   │                           │  │
│  │  Fast, under 1ms         │   │  Searched by meaning,     │  │
│  │  Expires after 24h       │   │  not by keyword.          │  │
│  │                          │   │  ~10ms. Never expires.    │  │
│  └──────────────────────────┘   └───────────────────────────┘  │
│                                                                 │
│  When you call retrieve_context(), both are searched in         │
│  parallel, then the most relevant pieces are selected to fit    │
│  inside your token budget, automatically.                       │
└─────────────────────────────────────────────────────────────────┘
The library prioritises intelligently. It never silently drops important things. It always keeps the most recent messages and the most relevant memories, pruning the least important stuff first.
Your token budget: 4,096 tokens
├── System prompt          ████████░░░░░░░░░░░░  30%  (never pruned)
├── Long-term memories     ██████░░░░░░░░░░░░░░  25%  (lowest relevance dropped first)
├── Recent messages        █████████░░░░░░░░░░░  35%  (oldest dropped first)
└── Current user message   ██░░░░░░░░░░░░░░░░░░  10%  (always kept)
After every 20 messages (configurable), the library quietly compresses the conversation into a summary and saves it to long-term memory. This runs in the background, so your users never wait for it.
Message 1  ──┐
Message 2    │
...          │  After 20 messages →  [Summary written to Qdrant]
Message 20 ──┘                           ↑
                                    Available forever, searchable by meaning
Each adapter is an optional extra (pip install actrone-memory[<framework>]), tested against the
version range below. Tier 1 = a governed system-context string (framework-free); Tier 2 = the
framework's native memory interface. The base install (pip install actrone-memory) is local-first
and pulls none of these, nor Redis/Qdrant/OpenAI (those are the redis/qdrant/openai/
production extras).
| Framework | Extra | Tested version | Tiers |
|---|---|---|---|
| LangChain | langchain | >=0.2,<3 | 1 + 2 (BaseChatMessageHistory; BaseMemory on 0.x) |
| LangGraph | langgraph | >=0.1,<2 | 1 + 2 (checkpointer) |
| CrewAI | crewai | >=0.95,<2 | 1 + 2 |
| AutoGen | autogen | >=0.4.3,<1 | 1 + 2 (Memory) |
| LlamaIndex | llamaindex | >=0.10,<2 | 1 + 2 (Memory) |
| Haystack | haystack | >=2.0,<4 | 1 + 2 (@component) |
| DSPy | dspy | >=2.5,<4 | 1 + 2 (Retrieve) |
| Agno | agno | >=1.0,<4 | 1 (additional_context) |
| smolagents | smolagents | >=1.5.1,<2 | 1 (task context) |
| AWS Strands | strands | >=1.0,<2 | 1 (system prompt) |
| OpenAI Agents SDK | openai_agents | >=0.2,<1 | 1 (instructions) |
| Pydantic AI | pydantic_ai | >=1.32,<3 | 1 (system prompt) |
| Claude Agent SDK | claude_agent_sdk | >=0.1,<1 | 1 (system prompt) |
| Semantic Kernel | semantic_kernel | >=1.16,<2 | 1 + 2 (ChatHistory) |
| Google ADK | google_adk | >=1.2,<3 | 1 + 2 (BaseMemoryService) |
| Microsoft Agent Framework | microsoft_agent_framework | >=1.0,<2 | 1 + 2 (ContextProvider) |
The base install and the redis / qdrant / openai extras carry no known
vulnerabilities, and CI audits both sets on every pull request. The framework extras pull
in third-party dependency trees we do not control, so their posture is worth knowing before
you install:
| Extra | Status |
|---|---|
langchain | Resolves clean on 1.x. This extra spans both majors (>=0.2,<3) precisely so you can take LangChain's security fixes, which only exist in the 1.x line. If you pin langchain-core<1 yourself you stay on 0.3.x, which has published advisories with no 0.3.x fix. |
semantic_kernel | Resolves to semantic-kernel 1.36.x and werkzeug 3.1.1, both with advisories. Upstream, not our cap: semantic-kernel 1.39.4+ requires a pre-release (azure-ai-agents>=1.2.0b3) that a normal pip install will not take, and werkzeug is held down by openapi-core. Neither is in a code path this adapter uses. |
If an advisory affects a framework component your own application uses, you can always install that framework yourself at the version you need and use the Tier-1 framework-free context string, which imports no framework at all.
LangChain 1.x removed the BaseMemory abstraction, so there are two adapters. Reach for
ActroneChatMessageHistory unless you are pinned to 0.x: it targets
BaseChatMessageHistory, which is unchanged across both majors.
# Works on LangChain 0.x and 1.x
from actrone_memory.integrations.langchain import ActroneChatMessageHistory

history = ActroneChatMessageHistory(agent_id="my-agent", session_id="user-123")
chain = RunnableWithMessageHistory(runnable, lambda _: history)

await chain.ainvoke(
    {"input": "hello"},
    config={"configurable": {"session_id": "user-123"}},
)
# LangChain 0.x only: the classic BaseMemory drop-in.
# Raises on 1.x with a pointer to the adapter above.
from actrone_memory.integrations.langchain import ActroneMemory

memory = ActroneMemory(agent_id="my-agent", session_id="user-123")
chain = ConversationChain(llm=llm, memory=memory)  # rest of your code unchanged
The adapter is async-only because the store is, so drive LangChain through ainvoke /
astream and the aget_messages / aadd_messages / aclear methods.
from actrone_memory.integrations.langgraph import ActroneCheckpointer

checkpointer = ActroneCheckpointer(agent_id="my-agent")
graph = graph_builder.compile(checkpointer=checkpointer)
# Your graph now remembers state across restarts and sessions
from actrone_memory.integrations.crewai import ActroneCrewMemory
from crewai import Task

# Each agent in the crew can recall and share findings
memory = ActroneCrewMemory(agent_id="research-crew", session_id="project-alpha")
context = await memory.build_context("competitor pricing")
task = Task(description=f"{context}\n\nSummarise competitor pricing.", agent=researcher)
# ...crew.kickoff(), then store what the crew concluded:
await memory.save(result, {"task_input": "Summarise competitor pricing."})
The adapter feeds memory into the task text rather than replacing CrewAI's own memory storage, so it works the same across CrewAI versions.
Full working scripts in the examples/ folder.
Everything is controlled with environment variables, so there are no config files to write. Every value below has a working default. You can run the quickstart without setting a single one.
| Variable | Default | What it does |
|---|---|---|
ACTRONE_BACKEND | memory | memory runs fully in-process. Set redis_qdrant for the durable backend. |
ACTRONE_EMBEDDING_PROVIDER | local | local (best offline embedder available: ONNX, then sentence-transformers, then hashing), hashing (dependency-free, no model download), or openai. |
ACTRONE_OPENAI_API_KEY | (none) | Required only when ACTRONE_EMBEDDING_PROVIDER=openai. Unused otherwise. |
ACTRONE_REDIS_URL | redis://localhost:6379 | Where your Redis is running. Used only when ACTRONE_BACKEND=redis_qdrant. |
ACTRONE_QDRANT_URL | http://localhost:6333 | Where your Qdrant is running. Used only when ACTRONE_BACKEND=redis_qdrant. |
ACTRONE_SESSION_TTL_HOURS | 24 | How long short-term memory lasts. |
ACTRONE_MAX_SESSION_TURNS | 50 | Max messages kept in short-term memory. |
ACTRONE_RELEVANCE_THRESHOLD | (calibrated) | How similar a memory must be before it is included (0 to 1). Unset, each embedder uses its calibrated value: 0.3 lexical, 0.63 bge-small, 0.4 MiniLM, and 0.72 for OpenAI or a custom embedder. |
ACTRONE_TOKEN_COUNTER | heuristic | heuristic (about 4 characters per token, no network) or tiktoken (exact counts; needs pip install "actrone-memory[tiktoken]", which downloads its encoding once). |
ACTRONE_AUTO_SUMMARISE | true | Automatically compress old conversations into long-term memory. |
ACTRONE_SUMMARISE_AFTER_TURNS | 20 | How many messages before auto-summarisation runs. |
ACTRONE_REDACT_SENSITIVITIES | [] | Sensitivity classes masked whenever memories are read, for example '["pii", "sensitive"]'. Matching memories come back as [redacted: <class>]. |
| Page | What's in it |
|---|---|
| Architecture deep dive | How the two-tier system works under the hood |
| API reference | Every method, every parameter, every error |
| Examples and cookbook | Copy-paste scripts for OpenAI, LangChain, and CrewAI |
| Contributing | How to set up the dev environment and submit a PR |
| Security policy | How to report a vulnerability privately |
actrone-memory is the open-source memory layer behind Actrone, a platform for production AI agents that is in development.
The hosted platform will add durable task execution, multi-model routing, tool supervision, and AI governance on top of your memory layer. It has not launched yet; join the waitlist to hear when it does.
MIT. Free to use in any project, commercial or otherwise.
Download counts and popularity will appear here as the collector receives them.
| Version | Published | Direct dependencies | Open version |
|---|---|---|---|
| 0.3.0 | 17 Oct 2026 | 45 |
This describes our collected data; it is not a security assessment.
Observed since 20 Oct, 18:40 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
package:dd8128e6310b83f135f93e537722e087e98440e9ec75a24ef93c57a61f5f8b57