
 Repository
Current collected state Current
Observed since 20 Oct, 19:07 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
Agentic RAG Framework built with LangGraph and Ollama
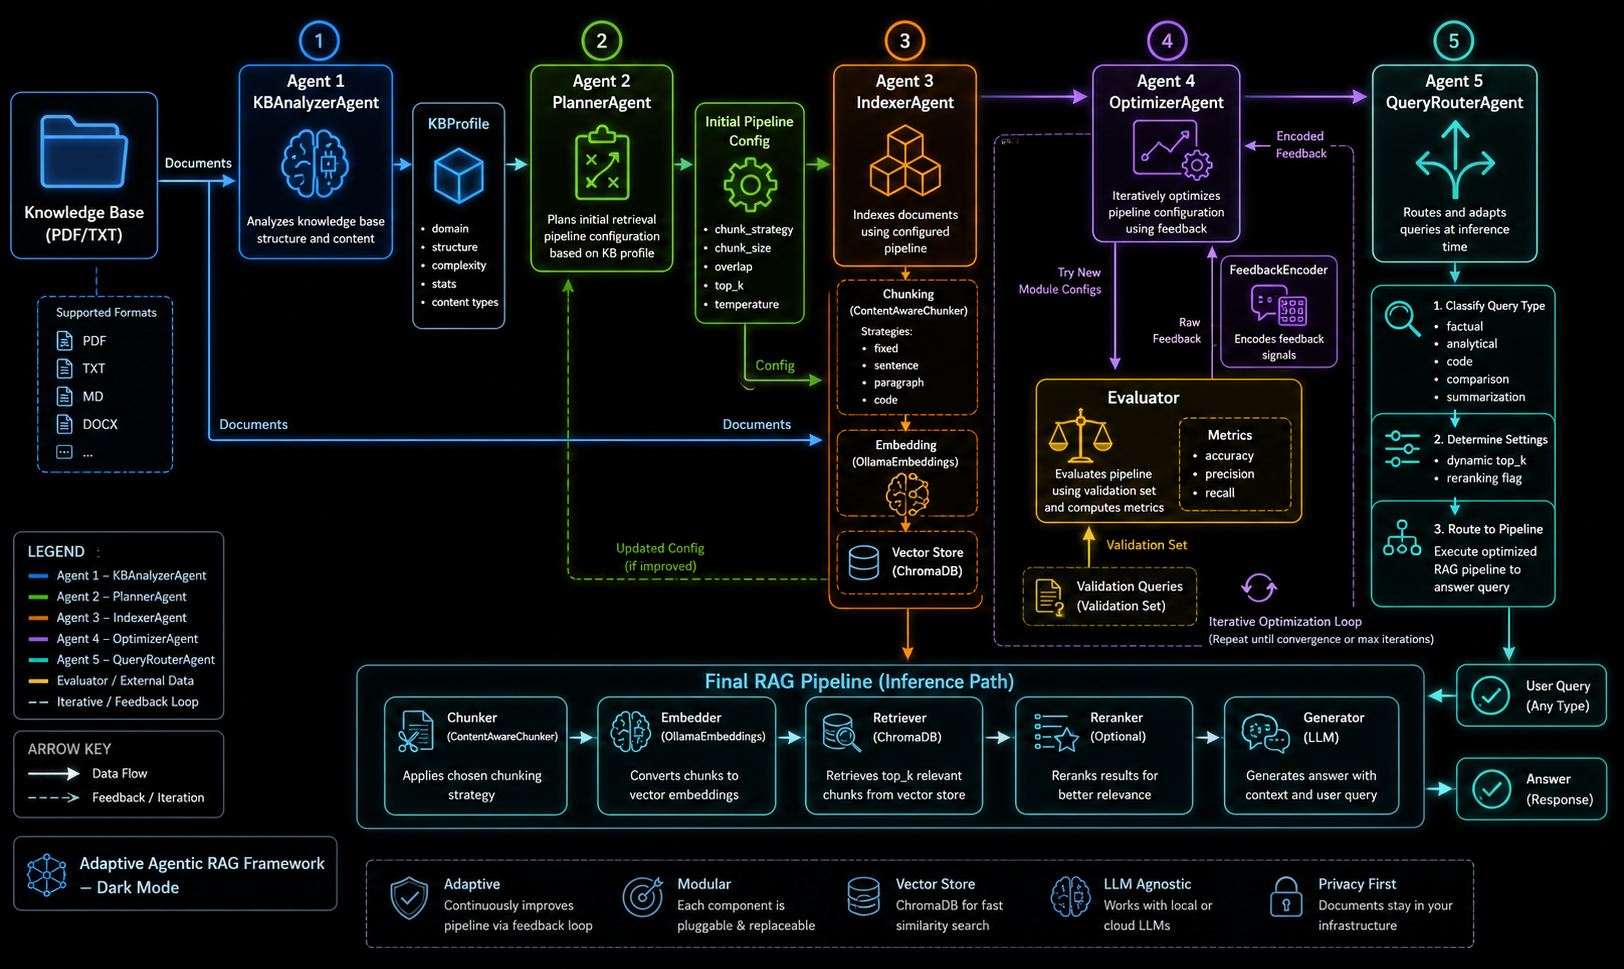


Self-optimising, fully local Retrieval-Augmented Generation built with LangGraph. AdaptiveRAG analyses your knowledge base, auto-tunes the pipeline, and routes every query through the best retrieval strategy — all without sending data to any external API.
Most RAG pipelines execute the same fixed sequence regardless of what you ask. AdaptiveRAG uses LLM-driven decision nodes at every step so the path through the graph changes per query and per knowledge base.
| Capability | Fixed RAG pipeline | AdaptiveRAG |
|---|---|---|
| Chunking strategy | Hard-coded | Chosen per document type (sentence / paragraph / code) |
| Chunk size | Fixed | Auto-tuned against your actual documents |
| Query expansion | None | HyDE (hypothetical document embedding) for vague queries |
| Retrieval passes | Single | Multi-hop follow-up when first pass is insufficient |
| Result reranking | None | Cross-encoder reranking for analytical / comparison queries |
| Answer quality | Not checked | Critic node scores the answer; retries with a new strategy if confidence is low |
| Parameter tuning | Manual | Optimizer agent tunes chunk size, top-k, temperature, and reranking automatically |
| Privacy | Requires external API | 100% local — no data leaves your machine |
AdaptiveRAG is composed of two LangGraph state machines.
load docs ──► profile KB ──► plan config ──► index ──► evaluate ──► orchestrate ──┐
                                                                         ▲          │
                                                                    critique ◄── tune_*
                                                                              (chunk / retrieval /
                                                                               generation / reranking)
classify ──► strategize ──► expand ──► retrieve ──► retrieval critic ──┐
    ▲                                                        │           │
    │                                                    multihop ◄──── ┘
    │                                                        │
    └──── retry ◄──── reflect ◄──── generate ◄──── rerank ◄─┘
pip install adaptiverag
With cross-encoder reranking (recommended for analytical or comparison queries):
pip install "adaptiverag[reranker]"
Prerequisite: Ollama must be running locally. Any missing models are pulled automatically the first time
build_rag()is called — no manualollama pullrequired.
Create a knowledge_base/ folder and drop in your files (.txt, .pdf, .md, .docx):
knowledge_base/
├── report.pdf
├── notes.md
└── spec.txt
from adaptiverag import build_rag

# Indexes knowledge_base/, auto-tunes the pipeline, returns a ready instance
rag = build_rag()

result = rag.ask("What are the main findings?")
print(result)                # the answer (str(result) also works)
print(result.confidence)     # 0.0 – 1.0 self-assessed confidence
print(result.strategy)       # why the agent chose this retrieval path
print(result.trace)          # full step-by-step reasoning log
adaptiverag
Interactive prompt with the same agentic graph — type trace to see the last query's reasoning.
rag = build_rag(
    llm_model        = "gemma4:latest",              # any Ollama chat model (auto-pulled)
    embed_model      = "nomic-embed-text:latest",    # any Ollama embedding model (auto-pulled)
    kb_path          = "./knowledge_base",           # path to your documents
    val_queries_path = "./validation_queries.json",  # optional — auto-generated from KB if omitted
)
# keyword prefix
result = rag.ask("from:report.pdf Summarise the methodology")

# or the parameter
result = rag.ask("Summarise the methodology", source_filter="report.pdf")
Any model available at ollama.com/library works. Recommended:
| Role | Model |
|---|---|
| LLM (routing + answers) | gemma4, llama3.2, mistral, qwen2.5 |
| Embeddings | nomic-embed-text, mxbai-embed-large |
| Format | Extension | Notes |
|---|---|---|
| Plain text | .txt | UTF-8 |
.pdf | Text-based; scanned PDFs not supported | |
| Markdown | .md | Code blocks, headings, and links stripped cleanly |
| Word | .docx | Requires python-docx (included) |
Mixed formats in the same folder are fully supported.
The setup graph tunes pipeline parameters by scoring generated answers against expected answers. Provide your own queries for best results:
[
  {
    "query": "What problem does this research solve?",
    "expected_answer": "The research addresses the challenge of ..."
  },
  {
    "query": "What method is used for data collection?",
    "expected_answer": "Data was collected through ..."
  }
]
Pass the path via val_queries_path. If you omit it:
./validation_queries.jsonbuild_rag(...) → AdaptiveRAG| Parameter | Type | Default | Description |
|---|---|---|---|
llm_model | str | "gemma4:latest" | Ollama model for routing and answer generation |
embed_model | str | "nomic-embed-text:latest" | Ollama model for embeddings |
kb_path | str | None | "./knowledge_base" | Folder containing your documents |
val_queries_path | str | None | "./validation_queries.json" | Validation Q&A file (auto-generated if missing) |
AdaptiveRAG.ask(question, source_filter=None) → QueryResult| Parameter | Type | Description |
|---|---|---|
question | str | Natural-language question. Prefix with from:<file> to filter by source. |
source_filter | str | None | Restrict retrieval to a single filename |
QueryResult fields| Field | Type | Description |
|---|---|---|
answer | str | The generated answer (str(result) also works) |
confidence | float | Self-assessed confidence, 0.0 – 1.0 |
retries | int | Number of reflection retries used |
strategy | str | One-line explanation of the retrieval strategy chosen |
trace | list[str] | Complete step-by-step decision log |
adaptiverag/
├── core/
│   ├── config.py        # constants and defaults
│   ├── models.py        # KBProfile, PipelineConfig dataclasses
│   └── runtime.py       # shared runtime singleton (RT)
├── components/
│   ├── chunker.py       # content-aware chunking strategies
│   ├── embedder.py      # Ollama embedding wrapper
│   ├── retriever.py     # ChromaDB retrieval
│   └── reranker.py      # cross-encoder reranking (optional)
├── pipeline/
│   ├── tools.py         # LangChain tools (retrieve, rerank, HyDE, generate)
│   ├── kb_analysis.py   # KB profiling and heuristic config planning
│   └── file_loader.py   # document loading (.txt, .pdf, .md, .docx)
├── graphs/
│   ├── setup_graph.py   # build-time LangGraph agent
│   └── query_graph.py   # per-query LangGraph agent
├── api.py               # public Python API (build_rag, AdaptiveRAG, QueryResult)
└── main.py              # CLI entry point
http://localhost:11434langgraph, langchain-ollama, chromadb, pypdf, python-docx, numpy, tqdmContributions are welcome. Please open an issue first to discuss what you would like to change.
git clone https://github.com/navid72m/adaptiveRAG.git
cd adaptiveRAG
pip install -e ".[dev]"
MIT © navid72m
Download counts and popularity will appear here as the collector receives them.
| Version | Published | Direct dependencies | Open version |
|---|---|---|---|
| 1.0.2 | 19 May 2026 | 13 |
This describes our collected data; it is not a security assessment.
Observed since 20 Oct, 19:07 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
package:bf0b925190910e23b5f4f7953e9619004f5d83d3a6a98f2fd54abd82e2314782