
 Repository
Current collected state Current
Observed since 20 Oct, 19:37 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
Universal LLM FinOps cost and token tracking plugin for Google Agent Development Kit (ADK) and LLM workflows.




Universal FinOps cost, token usage, and grounding fee tracking for the Google Agent Development Kit (ADK) and LLM workflows.
non_global) & Date-Tiered (2027) Pricing@billable)Building production AI agents with Google ADK involves multi-step tool-calling loops, reasoning models, and external search tools. However, monitoring real financial costs in production presents several challenges:
thoughtsTokenCount from candidatesTokenCount. If thinking tokens are not explicitly extracted, your token usage will not match your Google Cloud bill.search_documents) as paid Vertex AI Grounding queries ($35/1k or $2.50/1k).adk-finops solves all of these problems with a single lightweight, decoupled plugin.
BasePlugin lifecycle (before_run, before_model, after_model, on_event, after_tool, after_run).before_model_callback (< 0.5ms) using deterministic provider token profiles (google, openai, anthropic, deepseek). Block massive 200K+ token dumps (max_prompt_tokens) at $0.00 cloud cost or automatically downgrade models (gemini-2.5-pro ➔ gemini-2.5-flash) in-place before the request leaves the process.< 1ms and calculates concrete $ and % savings across Context Caching Opportunities, Thinking Token Alerts (thinking_budget=0), and Model Right-Sizing (gemini-3.5-flash ➔ gemini-3.5-flash-lite, gemini-2.5-pro ➔ gemini-2.5-flash, gpt-4o ➔ gpt-4o-mini). Easily toggled on/off via enable_optimization_advisor=True/False.status="success") from wasted capital burned on budget halts, failed retry loops, or silent semantic failures (status="failed", "error", "budget_exceeded"). Automatically captures budget circuit-breaker halts and ctx.state["failed"] = True workflow states; pairs with record_task_status() so teams can flag cleanly returning runs that fail business validation and auto-export crashed sessions to BigQuery.thoughts_token_count at the output rate while displaying thinking tokens separately in reports.@billable) & Per-Tool Attribution (breakdown_by_tool): Decorate custom functions/classes with @billable(fee=...) or @billable(fee_fn=...) (with automatic charge_on_error=False protection), register rates via CostTracker.register_tool_rate / tool_rates, and track per-agent tool call counts and fees (Agent -> Tool -> #Calls -> Cost) across the Rich terminal box, BigQuery, local logs, OpenTelemetry, and the web dashboard.event.actions.state_delta["finops_cost"] for live updates in the ADK Web UI, with formatted terminal stdout logging.pip install adk-finops
pip install "adk-finops[rich]"
pip install "adk-finops[bigquery]"
pip install "adk-finops[adk]"
pip install "adk-finops[all]"
pip install git+https://github.com/dmoonat/adk-finops.git
Or in requirements.txt:
adk-finops @ git+https://github.com/dmoonat/adk-finops.git@main
Add FinOpsCostPlugin to your App in agent.py:
from google.adk.agents import Agent
from google.adk.apps import App
from adk_finops import FinOpsCostPlugin

# 1. Define your agent
root_agent = Agent(
    model="gemini-2.5-pro",
    name="my_agent",
    instruction="You are a helpful assistant.",
    tools=[...]
)

# 2. Instantiate the FinOps plugin
finops_plugin = FinOpsCostPlugin(
    name="finops_cost_tracker",
    default_model="gemini-2.5-pro",
)

# 3. Attach plugin to your App
app = App(
    name="my_agent",
    root_agent=root_agent,
    plugins=[finops_plugin],
)
⚠️ Note:
FinOpsCostPluginis a nativeApp/Runner-levelBasePlugin. Register it only viaApp(plugins=[finops_plugin])(orRunner(plugins=[finops_plugin])) — do not also passplugin.after_model_callbacktoAgent(after_model_callback=...), or ADK will invoke the callback twice.
Run your agent with adk web or adk run. Telemetry will log directly to the terminal and appear in the Web UI session state under finops_cost.
adk-finops resolves the mismatch between single-event inspection and session-level totals by reporting both scopes concurrently:
| Scope | Description | Matches in ADK Web UI |
|---|---|---|
turn | Cumulative metrics for the current user interaction (Call 1 + Tool Execution + Call 2) | Full cost of the current turn |
session | Cumulative metrics across all turns in the chat session (Turn 1 + Turn 2 + ...) | ADK "Usage Summary for Session" |
{
  "total_tokens": 18671,
  "prompt_tokens": 16617,
  "completion_tokens": 1110,
  "thoughts_tokens": 944,
  "total_cost_usd": 0.0135785,
  "currency": "USD",

  "turn": {
    "total_calls": 2,
    "total_tool_calls": 0,
    "prompt_tokens": 14222,
    "completion_tokens": 1079,
    "thoughts_tokens": 908,
    "total_tokens": 16209,
    "llm_cost_usd": 0.0092341,
    "tool_cost_usd": 0.0,
    "total_cost_usd": 0.0092341,
    "breakdown_by_model": {
      "gemini-2.5-pro": {
        "calls": 2,
        "prompt_tokens": 14222,
        "completion_tokens": 1079,
        "thoughts_tokens": 908,
        "total_cost_usd": 0.0092341
      }
    }
  },

  "session": {
    "total_calls": 3,
    "total_tool_calls": 0,
    "prompt_tokens": 16617,
    "completion_tokens": 1110,
    "thoughts_tokens": 944,
    "total_tokens": 18671,
    "llm_cost_usd": 0.0135785,
    "tool_cost_usd": 0.0,
    "total_cost_usd": 0.0135785
  }
}
Prevent runaway agent loops and surprise bills with both Pre-Flight (before_model_callback) and Post-Call (after_model_callback) budget enforcement. Set hard USD spending limits per session, per turn, or per sub-agent, plus an optional hard ceiling on input prompt tokens (max_prompt_tokens):
from adk_finops import FinOpsCostPlugin

finops_plugin = FinOpsCostPlugin(
    default_model="gemini-2.5-pro",
    budget_limit_usd=1.00,             # Hard stop at $1.00 per chat session
    turn_budget_limit_usd=0.25,        # Maximum $0.25 on any single turn
    max_prompt_tokens=200_000,         # Pre-flight token cap (e.g. prevent 2x >200K tier charges)
    preflight_budget_guard=True,       # Estimate input tokens & cost BEFORE the network call (default: True)
    on_budget_exceeded="halt",         # Action: "halt", "warn", or "downgrade"
    fallback_model="gemini-2.5-flash", # Target model when using "downgrade"
)
before_model_callback)Before every outgoing LLM request, adk-finops estimates input tokens across system instructions, conversation history, tool schemas, function call/response payloads, and inline multimodal parts in < 0.5ms with zero network overhead (estimate_request_tokens(llm_request, model_name=...)):
google, openai, anthropic, deepseek) from llm_request.model and applies provider-specific tokenization profiles (PROVIDER_TOKEN_PROFILES).projected_cost_usd = current_cost_usd + estimated_call_cost_usd (accounting for >200K context tier pricing and cached tokens).projected_cost_usd would exceed your Agent, Turn, or Session budget (or if estimated_prompt_tokens > max_prompt_tokens), before_model_callback intervenes before the request is sent to the LLM provider — incurring $0.00 in cloud charges.| Component | Google (gemini-*) | OpenAI (gpt-4o, o1, o3) | Anthropic (claude-*) | DeepSeek (deepseek-*) |
|---|---|---|---|---|
| ASCII Chars / Token | 4.0 (SentencePiece 256k) | 4.4 (o200k_base) / 4.0 (cl100k_base) (or exact tiktoken if installed) | 3.6 (Claude 65k BPE vocab) | 3.7 (128k BPE vocab) |
| Turn Framing | +4 tokens / msg | +4 tokens / msg | +5 tokens / msg | +4 tokens / msg |
| Tool Call / Resp Envelope | +8 tokens | +12 tokens | +16 tokens | +10 tokens |
| Hidden Tool System Preamble | 0 tokens | +16 tokens | Dynamic by model & tool_choice:• Opus: 286 (auto/none) / 406 (forced)• Sonnet: 354 (auto/none) / 474 (forced)• Haiku: 264 (auto/none) / 340 (forced) | +12 tokens |
| Per-Tool Schema Overhead | +36 tokens / tool | +42 tokens / tool | +45 tokens / tool | +40 tokens / tool |
Images (image/*) | 258 tokens | 425 tokens (85 + 2×170 tiles) | 1,334 tokens ((1024×1024)/750) | 512 tokens |
PDFs (application/pdf) | 258 tokens / page | 800 tokens / page | 2,250 tokens / page (text + page image) | 512 tokens / page |
[!NOTE] Disclaimer — Deterministic Local Pre-Flight Estimation vs. Exact Post-Call Billing: Pre-flight token checking (
before_model_callback) is a deterministic local estimation derived fromPROVIDER_TOKEN_PROFILES(character/symbol density heuristics, exact PDF/Type /Pagemarker counting, and documented provider multimodal/tool preambles). It is intentionally designed to run in< 0.5msin-process without adding network latency from external/count_tokensAPI round-trips before every LLM call. Because it is a deterministic profile-based heuristic, pre-flight token estimates may vary by ±5–10% from the provider's remote tokenizer. Actual ledger accounting and billing (after_model_callback) always use the exact token counts (usage_metadata) returned by the LLM provider.
Just like pricing rate cards, you can register a new provider/model tokenization profile or override specific fields on existing providers programmatically, via FinOpsCostPlugin(token_profiles=..., token_profiles_path=...), or via ADK_FINOPS_TOKEN_PROFILES_PATH:
from adk_finops import CostTracker, register_token_profile, update_token_profile

# 1. Register a brand-new provider profile (inherits missing defaults from base_provider)
register_token_profile("mistral", {
    "ascii_chars_per_token": 3.8,
    "tool_System_preamble_tokens": 24,
    "image_tokens": 512,
    "pdf_page_tokens": 750,
})

# 2. Partially override an existing provider (merges nested dicts automatically)
update_token_profile("anthropic", {
    "pdf_page_tokens": 2500,
    "tool_System_preamble_tokens": {"opus_5.5_auto_or_none": 300},
    ..
})

# 3. Or via CostTracker / FinOpsCostPlugin
CostTracker.register_token_profile("meta-llama", {"ascii_chars_per_token": 3.9, ..})
| Mode | Pre-Flight (before_model_callback) & Post-Call Behavior | Best Used For |
|---|---|---|
"halt" (default) | Short-circuits before_model_callback by returning a safe LlmResponse before the network request is sent ($0.00 cloud cost), or halts subsequent calls if breached mid-turn. | Production safeguards, blocking massive 200K+ token dumps before they are billed. |
"downgrade" | Mutates llm_request.model = fallback_model (e.g. gemini-2.5-pro ➔ gemini-2.5-flash) in-place before the request leaves the process so the current call immediately executes at the lower rate. | Graceful service degradation with zero user downtime. |
"warn" | Logs a [FinOps Pre-Flight Guard] Warning with projected cost and marks exceeded: True in session state (finops_cost.budget) without interrupting execution. | Soft monitoring and alerting. |
In production AI systems, a failed agent loop (e.g., an agent repeatedly failing schema validation across 3 retries, returning a polite "I couldn't find that" after burning 5 tool calls, or crashing due to a downstream API outage after generating a complex plan) often burns 5x–20x more tokens than a successful task while delivering zero business value.
adk-finops tracks every LLM call in real time and classifies outcomes into Productive Spend vs. Wasted Capital, allowing teams to compare the average spend of a successful task against the wasted spend of failed loops.
[!IMPORTANT] Why "0% Wasted Spend" on Day 1 Doesn't Mean Zero Waste (Team Instrumentation Required)
adk-finopsautomatically captures thrown exceptions (on_run_error_callback,on_agent_error_callback,on_model_error_callback,on_tool_error_callback, andCostTracker.track_run) as well as budget circuit-breaker halts (status="budget_exceeded").However, in production AI systems, the most expensive failure isn't a thrown exception—it's the run that returns cleanly (
200 OK) and lands nothing (e.g., an agent gives up politely, produces an empty/invalid payload, or hallucinates without throwing a Python error).Because
adk-finopsis a zero-LLM observability plugin, any run that finishes normally without throwing an exception or setting a failure flag defaults tostatus="success". Your Wasted Spend metric for semantic failures rides on your team's outcome discipline: if your workflow validators, critics, or post-run checks do not setctx.state["failed"] = Trueor callrecord_task_status(status="failed"), your first dashboard chart will read$0.00 (0%)wasted spend whenever agents fail politely instead of throwing.
| Failure Category | Example | Captured Automatically? | How It Works / How to Instrument |
|---|---|---|---|
| Budget Circuit Breaker | Run exceeds budget_limit_usd or session_budget_usd (action="halt") | ✅ Yes (status="budget_exceeded") | Built-in (FinOpsCostPlugin / CostTracker.check_budget) |
| Unhandled Python / Tool / Model Exception | Downstream DB/API raises ConnectionError, tool crashes, or model call throws an exception | ✅ Yes (status="error") | Built-in via ADK on_run_error_callback, on_agent_error_callback, on_model_error_callback, on_tool_error_callback (auto-exports crashed session to BigQuery/JSONL/CSV) and CostTracker.track_run |
| Workflow Critic / Validator State | Graph node sets ctx.state["failed"] = True | ✅ Yes (status="failed") | Built-in via after_run_callback inspecting session.state |
| Cleanly Returning Run That Lands Nothing (Semantic / Silent Failure) | Agent finishes 200 OK without throwing, but outputs "Sorry, I cannot help", fails business validation, or produces no actionable artifact | ❌ No (defaults to "success") | Requires team discipline: set ctx.state["failed"] = True inside a validator/critic node or call finops_plugin.record_task_status(session_id, status="failed", error="...") after verifying the output |
status vs. is_failure| Field | Type | Values | Purpose |
|---|---|---|---|
status | str | "success", "pending", "failed", "error", "aborted", "budget_exceeded" | Operational Root Cause: Identifies how the task ended (e.g., validation loop exhausted "failed", downstream tool crash "error", or circuit breaker halt "budget_exceeded"). |
is_failure | bool | True or False | Financial Bucket: Binary flag (True when status is failed, error, aborted, or budget_exceeded) used to separate Wasted Spend (True) from Productive Spend (False). |
ctx.state["failed"])If any ADK workflow node, output verifier, or critic sets ctx.state["failed"] = True and ctx.state["error_reason"] = "...", FinOpsCostPlugin automatically detects the failure in after_run_callback, tags the root cause, and reclassifies the run's entire token spend as wasted capital:
def strict_validator(node_input, ctx):
    attempts = ctx.state.get("attempts", 0) + 1
    ctx.state["attempts"] = attempts
    if attempts >= 3:
        ctx.state["failed"] = True
        ctx.state["error_reason"] = "Exhausted 3 retry attempts without passing validation"
        return Event(output="Aborted", actions=EventActions(route="abort"))
record_task_status)When running standalone agents (without a graph critic node) or catching unhandled exceptions (where ADK skips after_run_callback), call finops_plugin.record_task_status() whenever your application-level check determines the run failed to land its objective or threw an exception. Calling record_task_status() also immediately flushes the failed session to BigQuery and configured exporters:
from adk_finops import CostTracker, print_summary, print_task_efficiency_summary

try:
    final_text = ""
    async for event in runner.run_async(user_id="u1", session_id=session_id, new_message=msg):
        if event.content and event.content.parts:
            final_text += "".join(p.text or "" for p in event.content.parts)

    # Catch the "returns cleanly and lands nothing" case:
    if not is_valid_business_outcome(final_text):
        finops_plugin.record_task_status(
            session_id=session_id,
            status="failed",
            error="Agent returned cleanly (200 OK) but did not produce a valid resolution",
        )
except Exception as e:
    # Logs thrown exception outcome AND automatically flushes the crashed session to BigQuery
    finops_plugin.record_task_status(
        session_id=session_id,
        status="error",
        error=f"{type(e).__name__}: {str(e)}",
    )
    print_summary(session_id=session_id)

# Render comparative efficiency report across all tasks
print_task_efficiency_summary()
╭───────────── 📊 FinOps Task Efficiency & Wasted Spend Analysis ──────────────╮
│                                                                              │
│  Metric         Successful Tasks   Failed Loops (Wasted)      Total / Impact │
│  ──────────────────────────────────────────────────────────────────────────  │
│  Task Count                    2                       2 4 (50.0% fail rate) │
│  Total Spend             $0.0021                 $0.0080 $0.0101 (79.6% was) │
│  Avg Spend / Task        $0.0010                 $0.0040 Wasted is 3.9x avg  │
│  Total Tokens                864                   3,383               4,247 │
│                                                                              │
│  ⚠️  Capital Loss: $0.0080 (79.6% of total spend) was burned on uncompleted  │
│ or failed tasks.                                                             │
│  🛡️  Budget Context: Total spend is $0.0101 / $5.0000 (0.2% limit used;      │
│ waste is 0.16% of budget limit).                                             │
╰─────────────── adk-finops • Successful vs. Wasted Agent Loops ───────────────╯
Context caching can reduce prompt token costs by up to 90%. adk-finops automatically calculates Gross Cost (what you would have paid without caching), Actual Net Cost, and Total Savings:
{
  "total_cost_usd": 0.00334,
  "gross_cost_usd": 0.00550,
  "savings_usd": 0.00216,
  "savings_pct": 39.3,
  "cached_tokens": 8000
}
Real-time stdout log highlight:
[FinOps LLM] turn=turn_1 model=gemini-2.5-flash tokens=11000 cost=$0.003340 | 💰 Saved $0.002160 (39.3%) via Context Caching
[FinOps Summary] Turn cost=$0.003340 | Session cost=$0.003340 | 💰 Total Saved: $0.002160 (39.3%) via Caching
In hierarchical multi-agent architectures (e.g., a supervisor delegating subtasks to a researcher and a coder), each agent makes distinct model calls, executes different tools, and consumes different context windows. Without granular attribution, teams cannot identify which sub-agent is driving 80% of costs or entering a costly reasoning loop.
adk-finops automatically attributes every LLM invocation, thinking token, context caching savings, and tool fee to the specific agent executing the task, with optional per-agent budget limits:
from adk_finops import FinOpsCostPlugin

finops_plugin = FinOpsCostPlugin(
    default_model="gemini-2.5-pro",
    budget_limit_usd=2.00,             # Total session cap: $2.00
    agent_budgets={
        "researcher": 0.50,            # Cap researcher at $0.50
        "coder": 1.00,                 # Cap coder at $1.00
    },
    on_budget_exceeded="halt",         # Halt if any agent breaches its limit
)
FinOpsCostPlugin automatically inspects the ADK agent tree (agent.root_agent, agent.parent_agent, and agent.sub_agents) during execution and tags every agent entry with:
root_agent_name: The top-level orchestrator / parent agent for the run (e.g., "supervisor").parent_agent_name: The immediate parent agent (null for the root orchestrator, "supervisor" for delegated sub-agents).agent_role: "root_self" (the root orchestrator's own direct LLM/tool calls), "sub_agent" (a delegated specialist sub-agent), or "root_rollup" (the overall parent-level session rollup combining the root agent + all its sub-agents).Every turn and session summary includes this hierarchy inside breakdown_by_agent:
{
  "root_agent_name": "supervisor",
  "breakdown_by_agent": {
    "supervisor": {
      "calls": 1,
      "prompt_tokens": 1000,
      "completion_tokens": 200,
      "thoughts_tokens": 0,
      "cached_tokens": 0,
      "total_tokens": 1200,
      "llm_cost_usd": 0.00225,
      "tool_cost_usd": 0.0,
      "total_cost_usd": 0.00225,
      "savings_usd": 0.0,
      "root_agent_name": "supervisor",
      "parent_agent_name": null,
      "agent_role": "root_self"
    },
    "researcher": {
      "calls": 2,
      "prompt_tokens": 4000,
      "completion_tokens": 500,
      "thoughts_tokens": 0,
      "cached_tokens": 2000,
      "total_tokens": 4500,
      "llm_cost_usd": 0.00189,
      "tool_cost_usd": 0.028,
      "total_cost_usd": 0.02989,
      "savings_usd": 0.00054,
      "savings_pct": 22.2,
      "root_agent_name": "supervisor",
      "parent_agent_name": "supervisor",
      "agent_role": "sub_agent"
    },
    "coder": {
      "calls": 1,
      "prompt_tokens": 8000,
      "completion_tokens": 1500,
      "thoughts_tokens": 300,
      "cached_tokens": 0,
      "total_tokens": 9800,
      "llm_cost_usd": 0.01275,
      "tool_cost_usd": 0.0,
      "total_cost_usd": 0.01275,
      "savings_usd": 0.0,
      "root_agent_name": "supervisor",
      "parent_agent_name": "supervisor",
      "agent_role": "sub_agent",
      "tools": {
        "patent_search": {
          "calls": 2,
          "total_cost_usd": 0.03
        }
      }
    }
  },
  "breakdown_by_tool": {
    "researcher": {
      "google_search": {
        "calls": 2,
        "total_cost_usd": 0.028
      }
    },
    "coder": {
      "patent_search": {
        "calls": 2,
        "total_cost_usd": 0.03
      }
    }
  }
}
[FinOps LLM] turn=turn_1 session=sess_1 agent=supervisor model=gemini-2.5-pro tokens=1200 cost=$0.002250
[FinOps Grounding] turn=turn_1 session=sess_1 agent=researcher tool=google_search fee=$0.014000
[FinOps Tool] turn=turn_1 session=sess_1 agent=coder tool=patent_search fee=$0.015000
[FinOps LLM] turn=turn_1 session=sess_1 agent=researcher model=gemini-2.5-flash tokens=4500 cost=$0.001890 | 💰 Saved $0.000540 (22.2%) via Context Caching
[FinOps Agents] supervisor: $0.0023 (1200 tok) | researcher: $0.0299 (4500 tok) | coder: $0.0428 (9800 tok)
[FinOps Tools] researcher -> google_search: 2 calls ($0.0280) | coder -> patent_search: 2 calls ($0.0300)
Beyond raw telemetry, adk-finops includes an Automated FinOps Optimization Advisor (src/adk_finops/advisor.py) that analyzes completed sessions in < 1ms with zero LLM calls and $0.00 overhead, computing concrete dollar and percentage savings directly from your active RateCardRegistry:
cached_input_per_1m vs. input_per_1m).thoughts_tokens >= 500 account for $\ge 60%$ of total output token cost, recommending thinking_budget=0 (or a lower ThinkingConfig cap) for routing/classification steps.gemini-3.5-pro $\rightarrow$ gemini-3.5-flash $\rightarrow$ gemini-3.5-flash-lite, gemini-2.5-pro $\rightarrow$ gemini-2.5-flash, gpt-4o $\rightarrow$ gpt-4o-mini, claude-3-5-sonnet $\rightarrow$ claude-3-5-haiku) for short responses (< 200 average output tokens) with 0 tool calls, calculating exact savings from switching to the lighter tier.The advisor is enabled by default and can be toggled on or off in FinOpsCostPlugin:
from adk_finops import FinOpsCostPlugin

# Enabled by default (renders in Terminal Box & attaches to get_summary()['optimization_insights'])
finops_plugin = FinOpsCostPlugin(
    enable_optimization_advisor=True,
)

# Disable the advisor if you only want raw telemetry
finops_plugin = FinOpsCostPlugin(
    enable_optimization_advisor=False,
)
Or toggle globally via environment variable:
export ADK_FINOPS_OPTIMIZATION_ADVISOR="false"
[!IMPORTANT] Disclaimer — Directional Hints Only: Optimization insights are generated using deterministic heuristics and token-level rules (with zero LLM evaluation of prompt semantics). They should be treated as directional hints rather than fully dependable or prescriptive actions. Before changing models, enabling caching, or lowering
thinking_budgetin production, always perform a deep analysis of your specific use-case, offline/online evaluation datasets (evaldata), accuracy benchmarks, latency SLAs, and business requirements.
adk-finops includes an out-of-the-box, color-coded, border-styled terminal summary box. When running in a terminal, it provides instant financial visibility after every turn, displaying turn vs. session costs, context caching ROI, model breakdowns, sub-agent attributions, and per-tool cost breakdowns (Agent -> Tool -> Calls -> Tool Cost):
╭───────────────────────── 💸 ADK FinOps Cost Summary ─────────────────────────╮
│                                                                              │
│  Scope           Calls   Tokens   LLM Cost   Tool Fees   Total Cost          │
│  ──────────────────────────────────────────────────────────────────          │
│  Current Turn        2   10,100    $0.0053     $0.0290      $0.0343          │
│  Session Total       2   10,100    $0.0053     $0.0290      $0.0343          │
│                                                                              │
│  💰 Context Caching Savings: $0.0016 saved (4.5% reduction from $0.0359 gross)│
│                                                                              │
│  Model              Calls   Tokens (In/Out)   Cost (USD)           Savings   │
│  ─────────────────────────────────────────────────────────────────────────   │
│  gemini-2.5-pro         1       1,200 / 300      $0.0030                 —   │
│  gemini-2.5-flash       1       8,000 / 600      $0.0023   $0.0016 (41.5%)   │
│                                                                              │
│  Agent             Calls   Tokens   LLM Cost   Tool Fees   Total Cost        │
│  ────────────────────────────────────────────────────────────────────        │
│  🤖 researcher         4   14,400    $0.0078     $0.0290      $0.0368        │
│  🤖 router_agent       1    5,900    $0.0130       $0.00      $0.0130        │
│  🤖 formatter          1    1,610    $0.0024       $0.00      $0.0024        │
│                                                                              │
│  Agent             Tool                             Calls   Tool Cost        │
│  ────────────────────────────────────────────────────────────────────        │
│  🤖 researcher     🔧 patent_search                     1     $0.0150        │
│  🤖 researcher     🔧 google_search                     1     $0.0140        │
│                                                                              │
│  🛡️  Budget Guard: $0.0343 / $1.0000 (3.4% utilized)                         │
│                                                                              │
│  💡 Optimization Insights (Est. Savings: $0.0148 | 63.6% cut available)      │
│   ⚡ Context Caching Opportunity: Agent 'researcher' sent >12k uncached      │
│ prompt tokens across 4 turns. Enabling Context Caching would save $0.0026    │
│ (90%).                                                                       │
│   🧠 Thinking Token Alert: Thinking tokens (4,200) were 82% of               │
│ 'router_agent' output cost ($0.0105); consider setting thinking_budget=0.    │
│   🎯 Model Right-Sizing: Agent 'formatter' used gemini-2.5-pro for <150      │
│ output tokens with 0 tool calls; switching to gemini-2.5-flash saves 70%     │
│ ($0.0017).                                                                   │
│   ℹ️  Disclaimer: Insights are deterministic hints; validate against your    │
│ use-case, eval data & business requirements.                                 │
╰───────────────── adk-finops • Universal Token & Cost Engine ─────────────────╯
rich is installed (pip install "adk-finops[rich]"), it renders full color highlights, styled headers, and rounded boxes.rich is not installed, it falls back seamlessly to an aligned pure-Python Unicode box drawing (╭─╮│╰─╯) with zero external dependencies.adk-finops supports both hands-off automated terminal reporting in Google ADK and explicit on-demand rendering for any Python workflow:
When using FinOpsCostPlugin, the summary box is rendered automatically to stdout at the conclusion of every turn (after_run_callback):
from google.adk.agents import Agent
from google.adk.apps import App
from adk_finops import FinOpsCostPlugin

# Automatically renders the Rich box and Optimization Advisor at the end of each turn
finops_plugin = FinOpsCostPlugin(
    default_model="gemini-2.5-pro",
    render_terminal_box=True,          # Enabled by default
    enable_optimization_advisor=True,  # Enabled by default
)

app = App(
    name="support_agent",
    root_agent=Agent(name="support_agent", model="gemini-2.5-pro"),
    plugins=[finops_plugin],
)
[!TIP] To disable the box and retain only standard single-line log output (e.g. in headless CI/CD environments), pass
render_terminal_box=False.
You can trigger terminal rendering programmatically at any time across your batch scripts, agent loops, or background tasks:
from adk_finops import CostTracker, format_summary_box, print_summary

# 1. Print current turn/session summary box directly to terminal stdout
print_summary()

# Or specify an explicit turn and session ID:
print_summary(run_id="turn_123", session_id="session_abc")

# 2. Or call directly from CostTracker
CostTracker.print_summary()

# 3. Export formatted box string (ANSI or plain text) for custom loggers or webhooks (Slack/Discord)
summary_data = CostTracker.get_summary()
box_text = format_summary_box(summary_data)
logger.info("\n" + box_text)
Pricing is completely decoupled from the tracking engine. You can configure rates via:
Create a my_rates.json file:
{
  "models": {
    "custom-fine-tuned-model": {
      "provider": "google",
      "input_per_1m": 0.50,
      "output_per_1m": 2.00,
      "cached_input_per_1m": 0.05
    }
  },
  "tools": {
    "paid_external_api": 0.01
  }
}
Pass the file path when initializing the plugin:
finops_plugin = FinOpsCostPlugin(rate_card_path="my_rates.json")
Set the rate card path globally without touching any code:
export ADK_FINOPS_RATE_CARD_PATH="/etc/finops/rates.json"
Fetch central rate cards from an internal endpoint or cloud storage bucket (GCS/S3):
from adk_finops import CostTracker

CostTracker.load_rate_card_url("https://internal.corp.com/finops/rates.json")
Apply your organization's contracted cloud discounts:
# Apply a 15% discount across all models and tools
finops_plugin = FinOpsCostPlugin(discount_percent=15.0)

# Or configure dynamically via CostTracker:
CostTracker.set_discount(15.0)                      # Global 15% discount
CostTracker.set_discount(20.0, provider="google")   # 20% discount on Google Cloud models
Or set via environment variable:
export ADK_FINOPS_DISCOUNT_PERCENT="15.0"
If a model is not present in the bundled default_rates.json, adk-finops applies the default fallback rate ($0.30 / $2.50 / $0.03 per 1M tokens), sets "is_fallback_rate": True on the recorded usage/summary, and logs a one-time warning prompting you to register the model's exact pricing via CostTracker.register_rate_card:
from adk_finops import CostTracker

CostTracker.register_rate_card("claude-opus-5", {
    "provider": "anthropic",
    "input_per_1m": 5.00,
    "output_per_1m": 25.00,
    "cached_input_per_1m": 0.50,
})

CostTracker.register_tool_rate("internal_vector_db", 0.0005)
non_global) & Date-Tiered (2027) Pricingadk-finops automatically detects your Google Cloud region and applies non_global regional rates (e.g., us-central1, europe-west1) as well as promotional-to-standard pricing transitions (standard_pricing_2027 starting Jan 1, 2027):
region passed to FinOpsCostPlugin(region="us-central1") or CostTracker.set_region("us-central1")GOOGLE_CLOUD_LOCATION environment variable (standard Google ADK .env configuration)ADK_FINOPS_REGION environment variable"global"from adk_finops import CostTracker, FinOpsCostPlugin
# Automatically uses GOOGLE_CLOUD_LOCATION from .env if set, or specify explicitly:
finops_plugin = FinOpsCostPlugin(
region="us-central1", # Applies non_global rates (+10% regional pricing where applicable)
effective_date="2027-01-01", # Optional: simulate or enforce 2027 standard pricing
)
To ensure your agents always calculate costs against the newest model pricing without waiting for a package upgrade, adk-finops provides opt-in Dynamic Remote Rate Card Syncing (with a 24-hour local disk cache at ~/.cache/adk-finops/remote_rates.json and graceful offline fallback) as well as a Google Cloud & Multi-Provider Pricing Extraction Framework (src/adk_finops/pricing_extractor.py).
source_urls & sources in default_rates.json)Every rate card generated by adk-finops records all upstream sources queried in its top-level "source_urls" and "sources" metadata:
| Source Name | Canonical URL | Scope & Coverage |
|---|---|---|
gemini_enterprise_pricing | https://cloud.google.com/gemini-enterprise-agent-platform/generative-ai/pricing | Google Cloud Gemini Enterprise Agent Platform (global, non_global regional +10%, standard_pricing_2027, >200K context tiers, and Grounding Tools) |
litellm_registry | https://raw.githubusercontent.com/BerriAI/litellm/main/model_prices_and_context_window.json | Multi-Provider (openai, anthropic, deepseek, and cross-validation) |
gcp_cloud_billing_catalog_api (optional) | https://cloudbilling.googleapis.com/v1/services/C7E2-9256-1C43/skus | Official Google Cloud Billing Catalog REST API (when GOOGLE_CLOUD_BILLING_API_KEY or --gcp-api-key is supplied; sent via X-Goog-Api-Key header) |
adk-finops uses two optional keys for different purposes — neither is required for standard local cost tracking:
| Key / Environment Variable | CLI Flag / Python Arg | Where to Get It | Purpose & How It Works |
|---|---|---|---|
GOOGLE_CLOUD_BILLING_API_KEY (optional) | --gcp-api-key / gcp_billing_api_key | Issued by Google Cloud: Google Cloud Console $\rightarrow$ APIs & Services $\rightarrow$ Credentials $\rightarrow$ Create Credentials $\rightarrow$ API key (enable Cloud Billing API). | Used only by adk-finops extract-pricing to query Google's cloudbilling.googleapis.com REST API. Sent via the X-Goog-Api-Key HTTP header. |
ADK_FINOPS_DASHBOARD_API_KEY (optional) | --api-key / dashboard_api_key | Pre-Shared Secret (PSK) you create: Because you run the adk-finops dashboard FastAPI server, you create any random token yourself (e.g. python3 -c "import secrets; print(secrets.token_urlsafe(24))"). | You set the same secret string in the environment (.env, Cloud Run env var, or Secret Manager) of both the Dashboard Server (which verifies it) and your Agents (HTTPExporter, which sends it in the X-FinOps-Key header). |
Note:
pricing_extractor.pyseeds Google Cloud model definitions directly fromdefault_rates.jsonvia_load_google_baseline_rates()so curatednon_global,standard_pricing_2027, and_gt_200kfields are never overwritten or duplicated.
FinOpsCostPlugin & CostTracker)from adk_finops import CostTracker, FinOpsCostPlugin
# Option A: Enable via FinOpsCostPlugin (or set ADK_FINOPS_SYNC_REMOTE_RATES=1 in .env)
finops_plugin = FinOpsCostPlugin(
sync_remote_rates=True, # Syncs latest default_rates.json (cached locally for 24h)
remote_cache_ttl_seconds=86400, # Optional custom cache TTL
)
# Option B: Programmatic sync on demand
status = CostTracker.sync_remote_rate_card(force=True)
Via the adk-finops CLI (extract-pricing & sync-rates):
# 1. Sync local rate card cache (~/.cache/adk-finops/remote_rates.json) from canonical remote repo
adk-finops sync-rates --force

# 2. Dry-run pricing extraction report (prints Rich table comparing live sources vs default_rates.json)
adk-finops extract-pricing

# 3. Export merged rate card (including newly discovered models like gpt-4.1, o3, claude-4) to a custom file
adk-finops extract-pricing --include-new-models --output ./custom_rates.json

# 4. Update bundled src/adk_finops/rates/default_rates.json in-place
adk-finops extract-pricing --update-default --include-new-models
Via the Python Module (python -m adk_finops.pricing_extractor):
python -m adk_finops.pricing_extractor --include-new-models --output ./custom_rates.json
Programmatically in Python (extract_and_sync_pricing):
from adk_finops import extract_and_sync_pricing

report = extract_and_sync_pricing(
    update_default_rates=False,
    output_path="./custom_rates.json",
    include_new_models=True,
    quiet=False,
)
print("Sources synced:", report.sources_succeeded)
print("Added models:", list(report.added_models.keys()))
Automated Weekly GitHub Actions Workflow (.github/workflows/sync_pricing.yml):
Runs every Monday at 06:00 UTC (or manually via workflow_dispatch with include_new_models enabled by default) to extract live rates and commit any changes to src/adk_finops/rates/default_rates.json.
@billable)adk-finops distinguishes between paid cloud grounding services ([FinOps Grounding]), explicitly billed custom/MCP tools ([FinOps Tool]), and free tools:
@billable Decorator (from adk_finops import billable) & Tool Rate Registration: Attach fixed per-call fees or dynamic per-result fees (fee_fn) directly to Python tool functions or custom ADK BaseTool classes, with built-in error protection (charge_on_error=False by default so failed API calls return $0.00 fee), or register tool pricing via FinOpsCostPlugin(tool_rates=...) and CostTracker.register_tool_rate(...):
from adk_finops import CostTracker, FinOpsCostPlugin, billable

# 1. Fixed per-call fee ($0.015 per invocation)
@billable(fee=0.015, provider="serpapi")
def patent_search(query: str) -> dict:
    """Searches external patent database."""
    return {"hits": 10}

# 2. Dynamic per-unit fee ($0.002 per page OCR'd; $0.00 if result has {"status": "error"})
@billable(
    fee_fn=lambda args, res: 0.002 * len(res.get("pages", [])),
    charge_on_error=False,
)
def ocr_document(gcs_uri: str) -> dict:
    """Extracts text from PDF pages via paid OCR service."""
    return {"pages": ["page1", "page2", "page3"]}

# 3. Global programmatic tool rate registration
CostTracker.register_tool_rate("enterprise_risk_score_api", 0.025)

# 4. Plugin-level tool_rates (ideal for paid third-party MCP tools)
finops_plugin = FinOpsCostPlugin(
    default_model="gemini-2.5-pro",
    tool_rates={"bloomberg_mcp_terminal": 0.05},
)
breakdown_by_tool): Every turn and session tracks {agent_name: {tool_name: {"calls": count, "total_cost_usd": fee}}}, rendering a dedicated Agent | Tool | Calls | Tool Cost table in the Rich Terminal Summary Box, logging [FinOps Tools] at turn end, and exporting breakdown_by_tool to JSONL, CSV, HTTP, BigQuery, OpenTelemetry, and the Web Dashboard.google_search, GoogleSearchTool, EnterpriseWebSearchTool, or carrying google_search config attributes incur $0.014 / query ($14.00 per 1,000 queries; first 5,000 queries/month free) and log as [FinOps Grounding].vertex_search, vertex_ai_search, GroundingTool, or carrying vertex_ai_search / data_store_id config attributes incur $0.0025 / prompt ($2.50 per 1,000 prompts) and log as [FinOps Grounding].McpToolset / MCPTool endpoints, BigQuery toolsets, and local Python functions incur $0.00 tool fee.Gemini 2.5 and Gemini 3.x models separate reasoning/thinking tokens into thoughtsTokenCount.
Per Google Cloud pricing rules:
Total Billable Output Tokens =
candidates_token_count+thoughts_token_count
adk-finops automatically incorporates thinking tokens into the output token rate while reporting them as a separate field in breakdown_by_model so you can monitor your reasoning overhead.
adk-finops tracks high-resolution monotonic wall-clock latency (time.perf_counter_ns()), streaming Time-To-First-Token (TTFT), tool execution latency, and token throughput across turn, session, model, agent, and tool scopes:
| Metric Key | Scope | Description |
|---|---|---|
latency_ms | Turn / Session / Agent | Overall wall-clock duration in milliseconds (turn_latency_ms when available, otherwise llm_latency_ms + tool_latency_ms). |
llm_latency_ms | All Scopes | Cumulative time spent waiting on LLM API calls in milliseconds. |
avg_llm_latency_ms | All Scopes | Average LLM latency per model invocation in milliseconds. |
p95_llm_latency_ms | All Scopes | 95th percentile LLM latency across calls in milliseconds. |
ttft_ms / avg_ttft_ms | All Scopes | Streaming Time-To-First-Token (before_model_callback $\rightarrow$ first partial=True streaming chunk). |
tool_latency_ms | All Scopes | Cumulative tool / grounding execution time (before_tool_callback $\rightarrow$ after_tool_callback). |
output_tokens_per_sec | All Scopes | Output generation speed: (completion_tokens + thoughts_tokens) / (llm_latency_ms / 1000). |
total_tokens_per_sec | All Scopes | Total processing throughput: total_tokens / (llm_latency_ms / 1000). |
When using FinOpsCostPlugin, latency and throughput are captured automatically with zero configuration:
[FinOps LLM] turn=e-6a9efc session=multi_ag agent=coordinator_agent model=gemini-3.1-pro-preview tokens=926 (prompt=428, completion=22, thoughts=476, cached=0) cost=$0.006832 | latency=6726.9ms throughput=74.0tok/s
[FinOps Tool] turn=e-6a9efc session=multi_ag agent=research_agent tool=fetch_cloud_benchmarks fee=$0.015000 latency=0.2ms
[FinOps Summary] Turn tokens=5042 cost=$0.049734 | Session tokens=5042 cost=$0.049734 | ⚡ turn_latency=26452.4ms throughput=93.5tok/s
And rendered in the Rich / Unicode terminal summary box and the Near-Live Web Dashboard (adk-finops dashboard):
⚡ Latency & Throughput: Wall: 26.45s | LLM: 26.38s (avg 8.79s, p95 12.16s) | Tools: 0.4ms | Out: 93.5 tok/s | Total: 191.2 tok/s
adk-finops is designed to be used in any Python application — FastAPI/Flask backends, Celery/Ray background pipelines, LangChain/LlamaIndex workflows, or raw Google GenAI / OpenAI / Anthropic SDK scripts — without requiring Google ADK.
from adk_finops import CostTracker, BigQueryExporter

# 1. track_run() automatically measures end-to-end turn_latency_ms
with CostTracker.track_run("request_123"):
    # 2. Option A: Context manager automatically times LLM latency (and streaming TTFT)
    with CostTracker.track_llm_call("request_123", model_name="gemini-3.7-flash", agent_name="researcher") as call:
        # Execute your SDK call (sync or async `async with CostTracker.track_llm_call(...)`)
        # Optional for streaming: call.mark_first_token() on first chunk
        call.record_usage(
            prompt_tokens=1500,
            completion_tokens=250,
            thoughts_tokens=100,
            cached_tokens=0,
        )

    # 3. Option B: Time tool execution with track_tool_call() (or pass latency_ms=... directly)
    with CostTracker.track_tool_call("request_123", tool_name="google_search", agent_name="researcher"):
        pass  # Execute external tool / search API

    # 4. Option C: If check_preflight_budget() is called before record_usage(),
    #    CostTracker automatically computes the elapsed latency delta!

# Print color-coded terminal summary box (includes Latency & Throughput columns)
CostTracker.print_summary("request_123")

# Get structured metrics dictionary
summary = CostTracker.get_summary("request_123")
print(f"Total Cost:  ${summary['total_cost_usd']:.6f}")
print(f"Latency:     {summary['latency_ms']:.1f}ms (Out: {summary['output_tokens_per_sec']:.1f} tok/s)")

# (Optional) Export to BigQuery in 1 line
# exporter = BigQueryExporter("my-project.finops.agent_costs")
# exporter.export_summary(summary)
| Variable | Type | Description |
|---|---|---|
GOOGLE_CLOUD_LOCATION | str | Primary ADK environment variable for region detection (e.g., "global", "us-central1"). Non-global regions automatically apply non_global rates. |
ADK_FINOPS_REGION | str | Fallback pricing region if GOOGLE_CLOUD_LOCATION is not set (defaults to "global"). |
ADK_FINOPS_EFFECTIVE_DATE | str | ISO date (YYYY-MM-DD) to evaluate date-tiered pricing such as standard_pricing_2027 (defaults to today's date). |
ADK_FINOPS_RATE_CARD_PATH | str | Absolute or relative path to a custom JSON rate card file. |
ADK_FINOPS_DISCOUNT_PERCENT | float | Global enterprise discount percentage (e.g., 15.0 for 15%). |
ADK_FINOPS_MAX_PROMPT_TOKENS | int | Hard pre-flight ceiling on estimated input prompt tokens per LLM call (e.g., 200000). |
ADK_FINOPS_PREFLIGHT_GUARD | bool | Enable or disable pre-flight token & budget estimation in before_model_callback ("true" or "false", default "true"). |
ADK_FINOPS_OPTIMIZATION_ADVISOR | bool | Toggle the Automated FinOps Optimization Advisor ("true" or "false"). |
FinOpsCostPlugin(
    name: str = "finops_cost_tracker",
    default_model: str = "gemini-2.5-flash",
    rate_card_path: str | Path | None = None,
    rate_card: dict[str, Any] | None = None,
    tool_rates: dict[str, float] | None = None,
    discount_percent: float | None = None,
    region: str | None = None,
    effective_date: str | date | None = None,
    budget_limit_usd: float | None = None,
    turn_budget_limit_usd: float | None = None,
    agent_budgets: dict[str, float] | None = None,
    max_prompt_tokens: int | None = None,
    preflight_budget_guard: bool = True,
    on_budget_exceeded: str = "halt",  # "halt", "warn", or "downgrade"
    fallback_model: str = "gemini-2.5-flash",
    render_terminal_box: bool = True,
    enable_optimization_advisor: bool = True,
)
| Parameter | Type | Default | Description |
|---|---|---|---|
default_model | str | "gemini-2.5-flash" | Fallback model name if not reported by the LLM response. |
rate_card_path | str | Path | None | Path to custom rate card JSON file. |
tool_rates | dict[str, float] | None | Custom per-call tool fees in USD (e.g. {"bloomberg_mcp": 0.05}). |
discount_percent | float | None | Enterprise volume discount percentage (e.g. 15.0 for 15%). |
region | str | None | None | Pricing region override. When None, auto-detects from GOOGLE_CLOUD_LOCATION $\rightarrow$ ADK_FINOPS_REGION $\rightarrow$ "global". |
effective_date | str | date | None | Optional ISO date ("YYYY-MM-DD") for date-tiered pricing (e.g. "2027-01-01" for 2027 standard rates). |
budget_limit_usd | float | None | Maximum cumulative spending limit in USD for the entire chat session. |
turn_budget_limit_usd | float | None | Maximum spending limit in USD for any single user turn. |
agent_budgets | dict[str, float] | None | Per-agent spending caps in USD (e.g. {"researcher": 0.50, "coder": 1.00}). |
max_prompt_tokens | int | None | Optional hard cap on estimated input prompt tokens per LLM call (e.g. 200_000 to block >200K tier charges). |
preflight_budget_guard | bool | True | Estimates input tokens and projected cost in before_model_callback before sending the LLM request. |
on_budget_exceeded | str | "halt" | Action on budget breach: "halt" (short-circuit/block), "warn", or "downgrade" (in-place model switch). |
fallback_model | str | "gemini-2.5-flash" | Target model when using "downgrade" mode. |
render_terminal_box | bool | True | Renders a beautiful color-coded summary box to stdout at the end of each turn. |
enable_optimization_advisor | bool | True | Enables deterministic FinOps Optimization Insights in the summary box and get_summary(). |
The bundled default_rates.json contains official public pricing (USD per 1M tokens, sourced from Google Cloud Generative AI Pricing):
| Model | Provider | Input / 1M (<=200k) | Output / 1M (<=200k) | Cached / 1M (<=200k) | Context >200k (_gt_200k) / Regional (non_global) / 2027 Notes |
|---|---|---|---|---|---|
gemini-3.1-pro-preview | $2.00 | $12.00 | $0.20 | >200k: In $4.00, Out $18.00, Cached $0.40 | |
gemini-3.8-flash-cyber | $1.50 | $7.50 | $0.15 | Non-global: In $1.65, Out $8.25, Cached $0.165 | |
gemini-3.8-flash | $0.75 | $3.75 | $0.075 | Non-global: $0.825 / $4.125 • 2027 Standard: $1.50 / $7.50 (Non-global: $1.65 / $8.25) | |
gemini-3.7-flash | $0.75 | $3.75 | $0.075 | Non-global: $0.825 / $4.125 • 2027 Standard: $1.50 / $7.50 (Non-global: $1.65 / $8.25) | |
gemini-3.6-flash | $0.75 | $3.75 | $0.075 | Non-global: $0.825 / $4.125 • 2027 Standard: $1.50 / $7.50 (Non-global: $1.65 / $8.25) | |
gemini-3.5-flash | $1.50 | $9.00 | $0.15 | Non-global: In $1.65, Out $9.90, Cached $0.165 | |
gemini-3.5-flash-lite | $0.30 | $2.50 | $0.03 | Non-global: In $0.33, Out $2.75, Cached $0.033 | |
gemini-3.1-flash-lite | $0.25 | $1.50 | $0.025 | Non-global: In $0.275, Out $1.65, Cached $0.0275 | |
gemini-3-flash-preview | $0.50 | $3.00 | $0.05 | — | |
gemini-3-pro-image | $2.00 | $12.00 | $0.20 | >200k: In $4.00, Out $18.00, Cached $0.40 | |
gemini-3.1-flash-image | $0.50 | $3.00 | $0.05 | Nano Banana 2 image generation | |
gemini-3.1-flash-lite-image | $0.25 | $1.50 | $0.025 | Nano Banana Lite image generation | |
gemini-2.5-pro | $1.25 | $10.00 | $0.125 | >200k: In $2.50, Out $15.00, Cached $0.25 | |
gemini-2.5-pro-computer-use-preview | $1.25 | $10.00 | $0.125 | >200k: In $2.50, Out $15.00, Cached $0.25 | |
gemini-2.5-flash | $0.30 | $2.50 | $0.03 | >200k: In $0.30, Out $2.50, Cached $0.03 | |
gemini-2.5-flash-lite | $0.10 | $0.40 | $0.01 | >200k: In $0.10, Out $0.40, Cached $0.01 | |
gemini-2.5-flash-image | $0.30 | $2.50 | $0.03 | — | |
gemini-2.5-flash-live | $0.50 | $2.00 | $0.05 | Live API text rates | |
gemini-2.0-flash | $0.15 | $0.60 | $0.0375 | — | |
codemender | $0.75 | $3.75 | $0.075 | 2027 Standard: In $1.50, Out $7.50, Cached $0.15 | |
gpt-4o | OpenAI | $2.50 | $10.00 | $1.25 | — |
gpt-4o-mini | OpenAI | $0.15 | $0.60 | $0.075 | — |
o1 | OpenAI | $15.00 | $60.00 | $7.50 | — |
o3-mini | OpenAI | $1.10 | $4.40 | $0.55 | — |
claude-3-7-sonnet | Anthropic | $3.00 | $15.00 | $0.30 | — |
claude-3-5-sonnet | Anthropic | $3.00 | $15.00 | $0.30 | — |
claude-3-5-haiku | Anthropic | $0.80 | $4.00 | $0.08 | — |
deepseek-v3 | DeepSeek | $0.14 | $0.28 | $0.014 | — |
deepseek-r1 | DeepSeek | $0.55 | $2.19 | $0.14 | — |
Stream turn, session, model, and sub-agent FinOps telemetry directly into a Google BigQuery dataset with a single configuration parameter:
from adk_finops import FinOpsCostPlugin

finops_plugin = FinOpsCostPlugin(
    default_model="gemini-2.5-flash",
    bigquery_table="my-gcp-project.finops.agent_costs",
    bigquery_export_scope="both",  # "session" (default), "turn", or "both"
    bigquery_tags={"env": "production", "service": "support-agent"},
)
[!TIP] Environment Variable Auto-Discovery: You can also set
ADK_FINOPS_BIGQUERY_TABLE="my-gcp-project.finops.agent_costs"in your environment or.envfile to enable BigQuery streaming without changing a single line of application code!
When bigquery_table is specified, adk-finops automatically inspects and provisions the dataset and table with enterprise best practices:
timestamp to optimize query performance and reduce scan costs.[session_id, agent_name, model_name] for sub-second filtering in Looker Studio and BI tools.adk-finops, ensure_table_exists() automatically adds any newly introduced NULLABLE columns (such as breakdown_by_tool) in-place with zero downtime.| Field Name | Type | Description |
|---|---|---|
timestamp | TIMESTAMP | Event timestamp in UTC (Partition Key) |
session_id | STRING | ADK Session ID (Clustering Key #1) |
turn_id | STRING | ADK Turn / Invocation ID |
scope | STRING | Record scope: "turn" or "session" |
agent_name | STRING | Attributed Agent name (Clustering Key #2) |
model_name | STRING | Model name / version (Clustering Key #3) |
prompt_tokens | INTEGER | Input prompt token count |
completion_tokens | INTEGER | Output candidate token count |
thoughts_tokens | INTEGER | Gemini 2.5 thinking token count |
cached_tokens | INTEGER | Context cached token count |
total_tokens | INTEGER | Total billable tokens |
llm_cost_usd | FLOAT | Net LLM API cost in USD |
tool_cost_usd | FLOAT | Search, Grounding & @billable tool fees in USD |
total_cost_usd | FLOAT | Total net cost in USD |
gross_cost_usd | FLOAT | Gross cost before caching discount |
savings_usd | FLOAT | Dollars saved via context caching |
savings_pct | FLOAT | Percentage saved via context caching |
tool_calls_count | INTEGER | Number of billable grounding/tool calls |
latency_ms | FLOAT | Overall wall-clock latency in milliseconds |
llm_latency_ms | FLOAT | Cumulative LLM call latency in milliseconds |
tool_latency_ms | FLOAT | Cumulative tool execution latency in milliseconds |
ttft_ms | FLOAT | Streaming Time-To-First-Token (TTFT) in milliseconds |
output_tokens_per_sec | FLOAT | Output token generation speed (tok/s) |
total_tokens_per_sec | FLOAT | Total token processing throughput (tok/s) |
budget_limit_usd | FLOAT | Configured budget threshold |
budget_utilization_pct | FLOAT | Budget utilization percentage |
budget_exceeded | BOOLEAN | Whether budget guard was tripped |
breakdown_by_agent | JSON | Multi-agent attribution snapshot |
breakdown_by_model | JSON | Model distribution snapshot |
breakdown_by_tool | JSON | Per-agent tool call counts & fee attribution ({agent: {tool: {calls, total_cost_usd}}}) |
tags | JSON | User-provided tags (e.g. env, tenant_id) |
When streaming telemetry to BigQuery, adk-finops records both overall aggregates (for high-level session/turn reporting) and attributed breakdown rows (for granular drill-downs by agent or model).
agent_name or model_name NULL in some rows?In data warehousing and BI rollup patterns, NULL is assigned to dimension columns in summary/rollup rows to distinguish between overall totals and specific entity breakdowns:
agent_name IS NULL):
agent_name is NULL (can be displayed as 'OVERALL' or 'TOTAL' via COALESCE(agent_name, 'OVERALL')).model_name is NULL (the complete distribution is preserved in the breakdown_by_model JSON column). If only a single model was used, model_name is set to that model.agent_name IS NOT NULL):
agent_name = 'research_agent', etc.).model_name contains the primary model invoked by that agent (e.g. gemini-2.5-pro, gemini-2.5-flash).Because both aggregate rows and attributed breakdown rows coexist in the same table, write your SQL queries according to the level of granularity you need:
To query overall totals (e.g. total spend per session):
SELECT session_id, total_cost_usd, total_tokens
FROM `my-gcp-project.finops.agent_costs`
WHERE scope = 'session' AND agent_name IS NULL;
To query per-agent breakdown (without double-counting with the aggregate):
SELECT agent_name, SUM(total_cost_usd) AS agent_spend
FROM `my-gcp-project.finops.agent_costs`
WHERE scope = 'session' AND agent_name IS NOT NULL
GROUP BY 1;
To query by model:
SELECT model_name, SUM(total_cost_usd) AS model_spend
FROM `my-gcp-project.finops.agent_costs`
WHERE scope = 'session' AND model_name IS NOT NULL
GROUP BY 1;
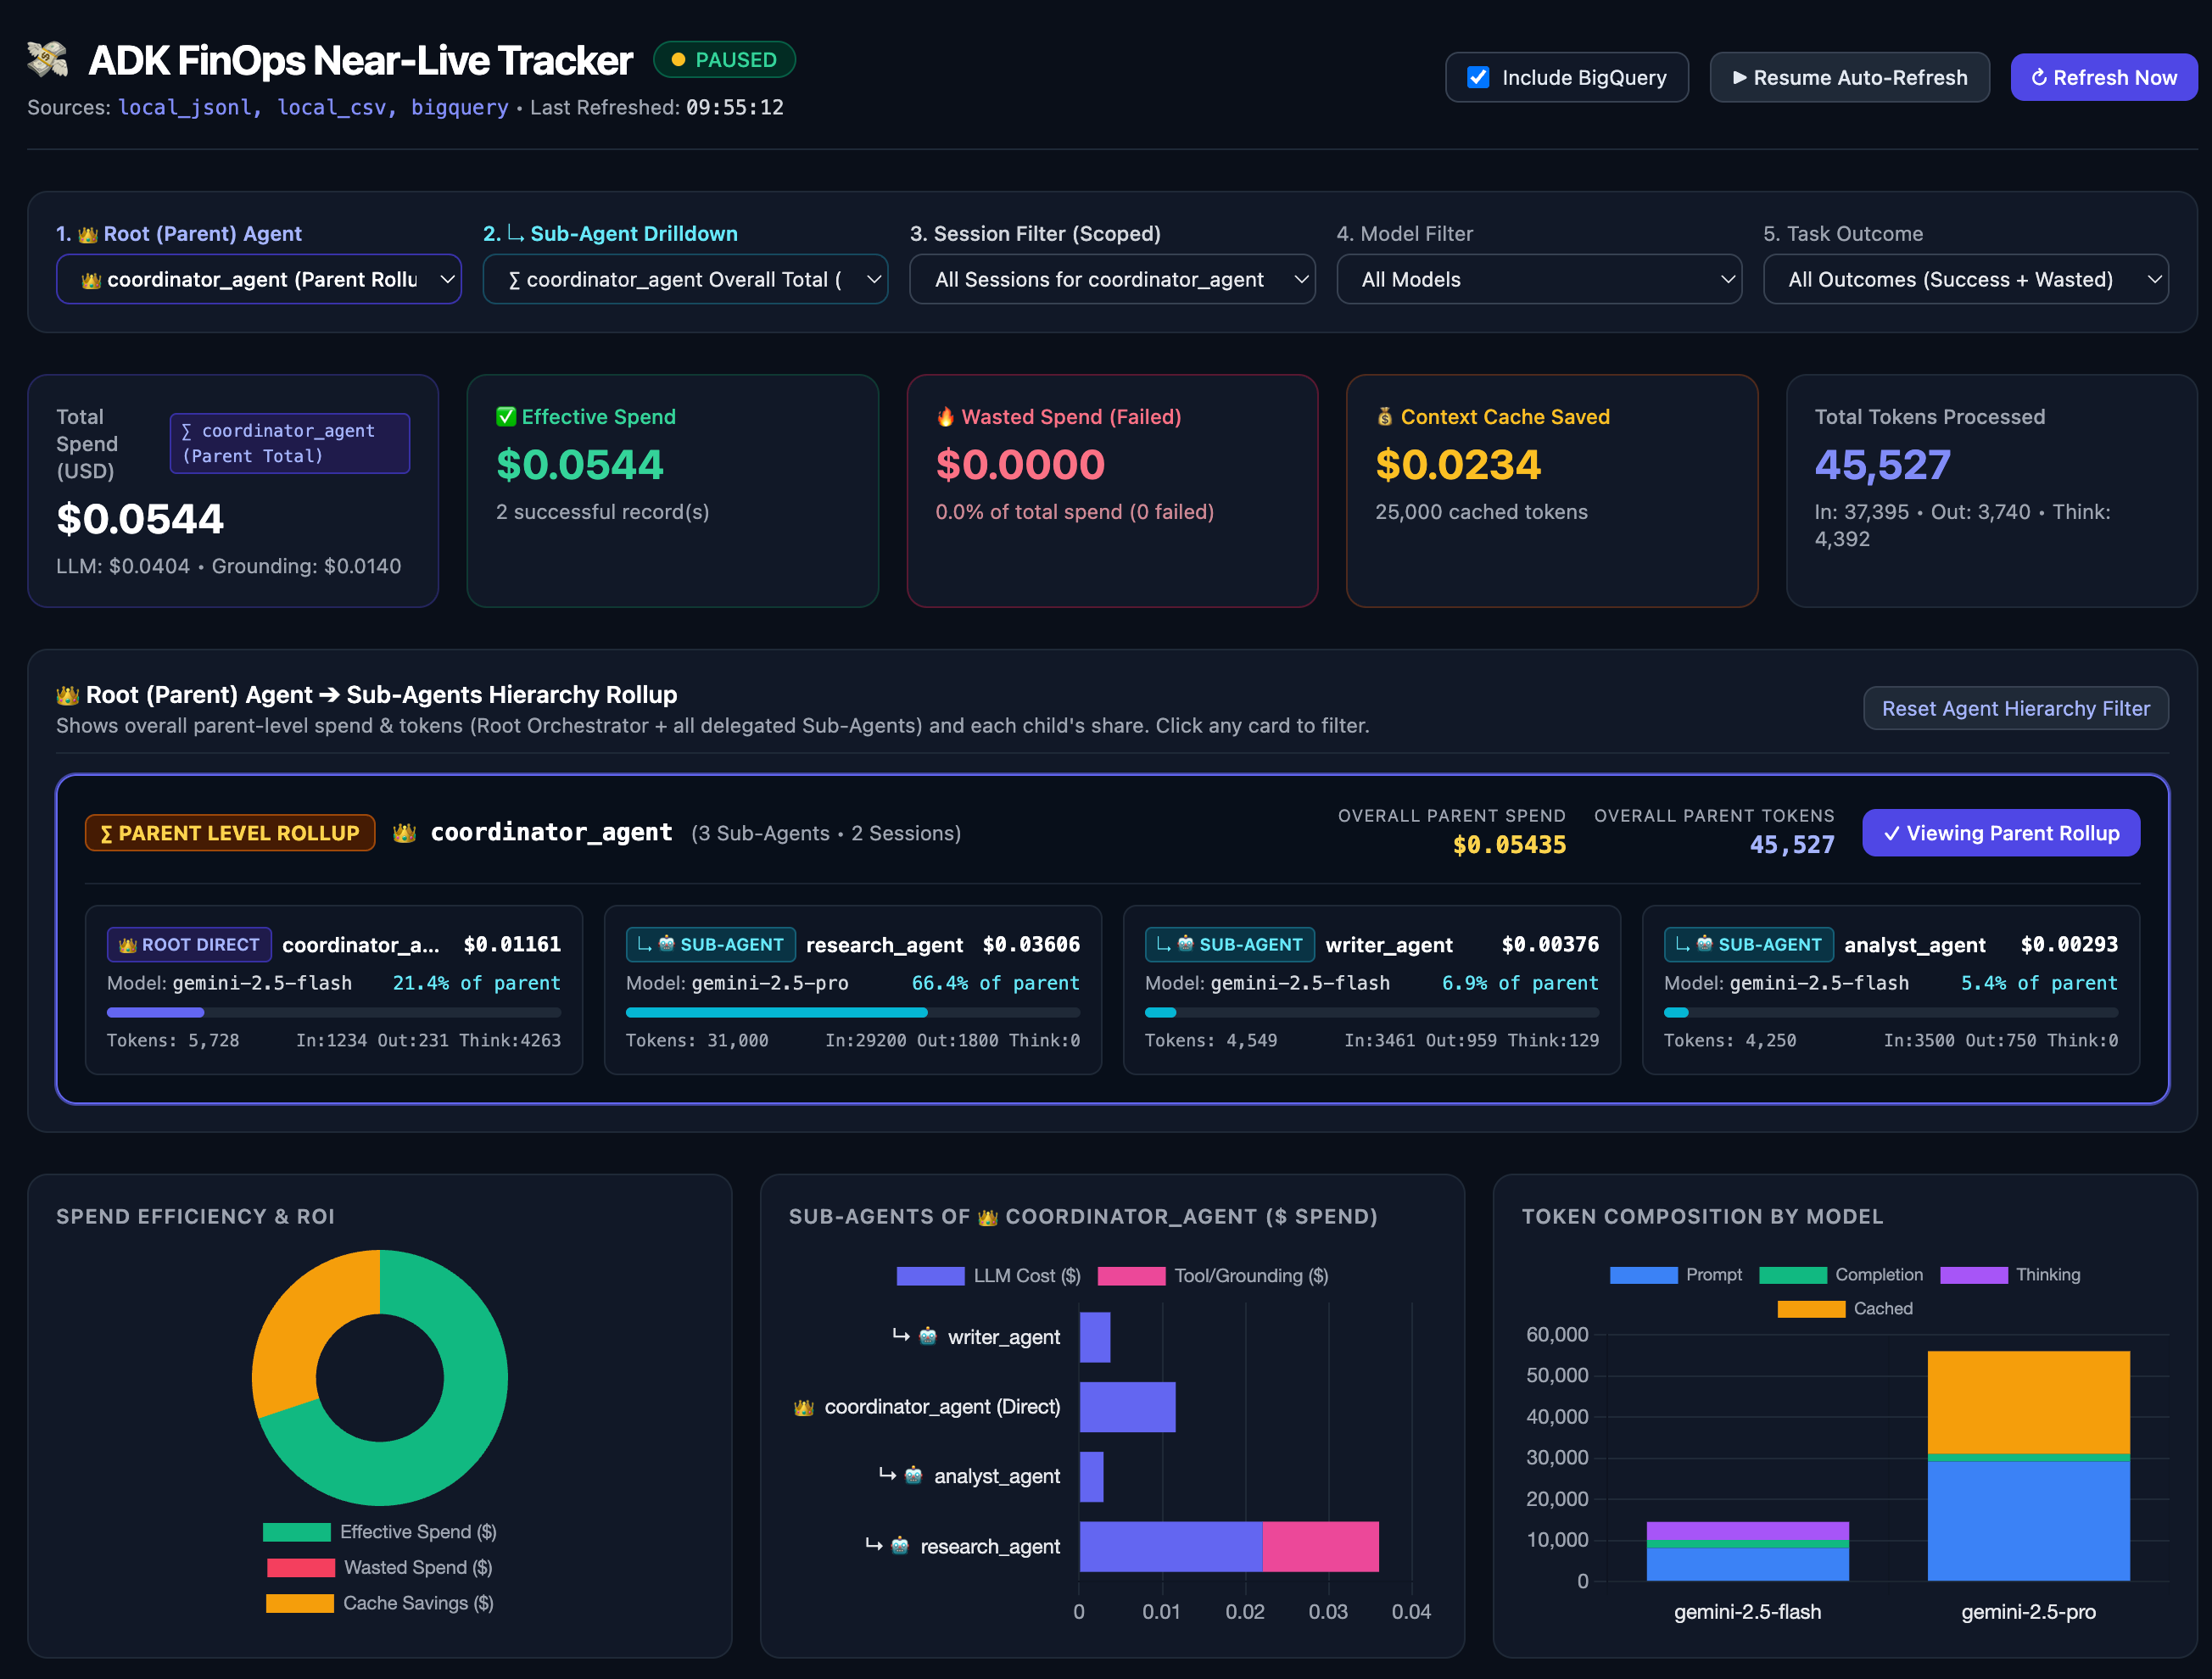
adk-finops dashboard)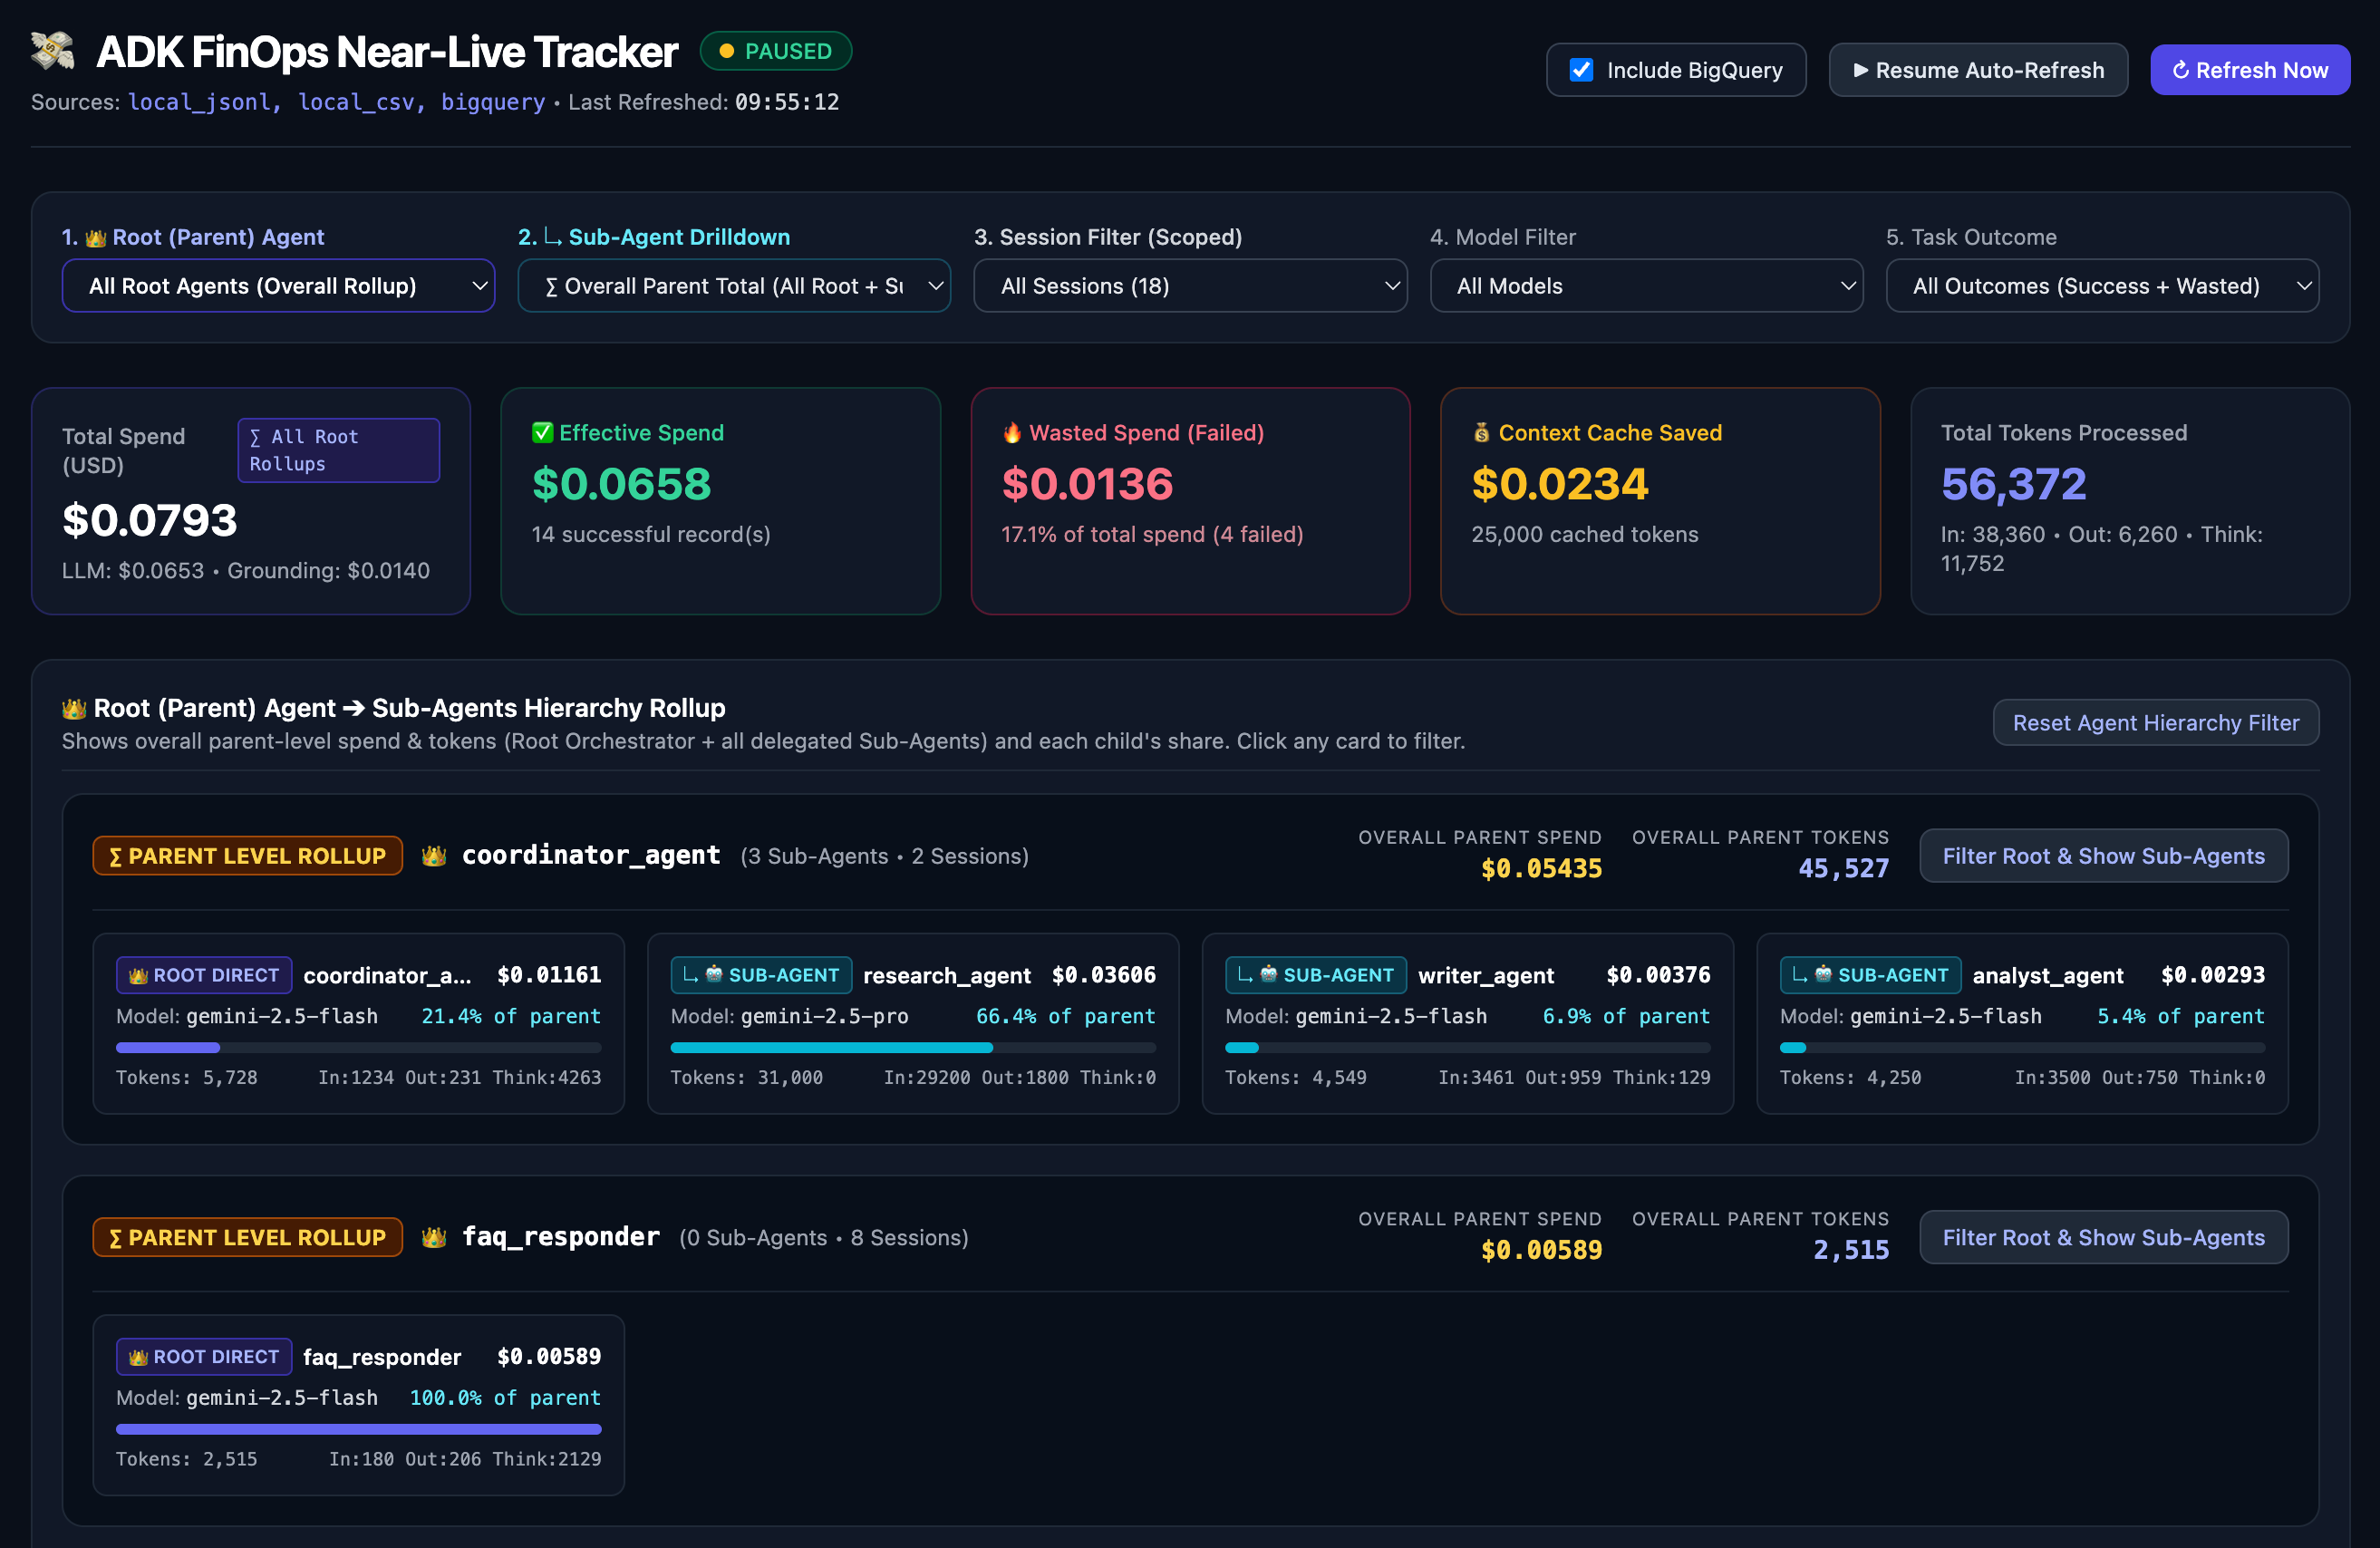
adk-finops includes a built-in, zero-extra-dependency FastAPI + Chart.js Near-Live Web Dashboard that auto-refreshes every 2 seconds, aggregating:
CostTracker State: Watch tokens and spend accumulate in real time while an agent is mid-execution..jsonl & .csv Logs: Automatically scans logs/<YYYYMMDD_HHMMSS>/*.jsonl and *.csv.POST /api/ingest): Receives telemetry pushed over HTTP from remote agent containers (HTTPExporter / dashboard_endpoint) and persists it to <log_dir>/ingested_costs.jsonl.15s cache TTL) to merge cloud warehouse records (ADK_FINOPS_BIGQUERY_TABLE).
1. 👑 Root (Parent) Agent: Filter by a top-level orchestrator/parent agent (e.g., 👑 coordinator_agent). Selecting a Root Agent automatically computes the Overall Parent-Level Spend & Tokens (∑ Parent + All Sub-Agents) in the KPI cards while displaying all of its sub-agents in the breakdown charts and hierarchy tree.2. ↳ Sub-Agent Drilldown: Dynamically cascades to list only the children belonging to the selected Root Agent (∑ Overall Parent Total, 👑 Root Orchestrator Direct Only, or individual ↳ 🤖 Sub-Agents).3. Session Filter (Scoped): Automatically scopes the session dropdown so it only lists sessions belonging to the selected Root Agent (and Sub-Agent).4. Model Filter: Scoped to the models invoked by the selected Root / Sub-Agent.5. Task Outcome: Filter between ✅ Effective Spend Only (Success) and 🔥 Wasted Spend Only (Failed / Error / Budget).👑 Root (Parent) Agent ➔ Sub-Agents Hierarchy Rollup Explorer: Interactive parent-to-child cards showing each Root Agent's overall parent rollup (∑ Overall Parent Spend and Overall Parent Tokens) alongside each child's spend, token breakdown (In / Out / Think), model, tool badges (🔧 <tool> ×N ($cost)), and percentage share of parent spend with click-to-filter support.🔧 Tool Cost Attribution (Agent ➔ Tool ➔ #Calls ➔ Cost) Panel & Live Telemetry Table: Dedicated tool cost breakdown table showing Agent | Tool | # Calls | Avg Cost / Call | Total Tool Cost plus a Tools (Calls / Fee) column in the Live Telemetry Table.In / Out / Think), Spend Efficiency Doughnut, Sub-Agent Stacked Cost Bar (LLM vs Tool/Grounding), and Per-Model Token Composition.FinOpsCostPluginStart the live dashboard automatically in a background daemon thread inside your agent process:
from adk_finops import FinOpsCostPlugin

finops_plugin = FinOpsCostPlugin(
    enable_dashboard=True,                  # or set ADK_FINOPS_ENABLE_DASHBOARD=true
    dashboard_port=8088,                    # default: 8088 (auto-selects next free port if busy)
    jsonl_path="logs/finops_costs.jsonl",   # saves into logs/<YYYYMMDD_HHMMSS>/finops_costs.jsonl
)
3 Patterns)An organization admin can run adk-finops dashboard as a single centralized FinOps control plane (with zero agents running inside the dashboard process) to monitor dozens of independent root agents and sub-agent teams across an organization:
All agents across the org stream to a shared BigQuery table (ADK_FINOPS_BIGQUERY_TABLE="org-project.finops.agent_costs"). The admin runs the standalone dashboard pointing strictly to BigQuery:
adk-finops dashboard \
  --bigquery-table org-project.finops.agent_costs \
  --log-dir "" \
  --host 0.0.0.0 \
  --port 8088
--log-dir)Pass comma-separated directories to watch timestamped .jsonl / .csv files across multiple agent repositories or shared volumes simultaneously:
adk-finops dashboard \
  --log-dir "/srv/agents/retail_bot/logs,/srv/agents/finance_bot/logs" \
  --port 8088
dashboard_endpoint $\rightarrow$ POST /api/ingest)When an organization does not use BigQuery and agents run in isolated containers/VMs without a shared disk, agents push telemetry over HTTP via HTTPExporter to the central dashboard's POST /api/ingest endpoint.
If neither --api-key nor ADK_FINOPS_DASHBOARD_API_KEY is configured on the dashboard server, /api/ingest accepts local telemetry pushes without requiring a token:
adk-finops dashboard --host 127.0.0.1 --port 8088 --log-dir central_logs
dashboard_endpoint on your agent:
from adk_finops import FinOpsCostPlugin

finops_plugin = FinOpsCostPlugin(
    dashboard_endpoint="http://127.0.0.1:8088",  # Pushes via HTTPExporter -> POST /api/ingest
    export_tags={"team": "payments", "service": "refund_agent"},
)
ADK_FINOPS_DASHBOARD_API_KEY)Because adk-finops dashboard is a self-hosted FastAPI server (not a third-party SaaS), you control the password/token that protects its POST /api/ingest endpoint. It works like a standard Pre-Shared Key (PSK) or webhook secret in 3 steps:
python3 -c "import secrets; print(secrets.token_urlsafe(24))"
# Example output: finops_live_9xK2mP7vQ4wL8nR1zT5yB3cF
.env file locally, or via GCP Secret Manager / Kubernetes Secrets / Cloud Run env vars in production):
# On the Dashboard Server VM / Container:
export ADK_FINOPS_DASHBOARD_API_KEY="finops_live_9xK2mP7vQ4wL8nR1zT5yB3cF"
adk-finops dashboard --host 0.0.0.0 --port 8088 --log-dir central_logs
X-FinOps-Key header:
import os
from adk_finops import FinOpsCostPlugin, HTTPExporter

# If ADK_FINOPS_DASHBOARD_API_KEY is in your agent's .env or environment,
# FinOpsCostPlugin and HTTPExporter pick it up automatically!
finops_plugin = FinOpsCostPlugin(
    dashboard_endpoint="http://finops-dash.internal:8088",
    dashboard_api_key=os.getenv("ADK_FINOPS_DASHBOARD_API_KEY"),
    export_tags={"team": "payments", "service": "refund_agent"},
)
HTTPExporter sends X-FinOps-Key: finops_live_9xK2mP7vQ4wL8nR1zT5yB3cF on POST /api/ingest. The dashboard server compares that header against its own ADK_FINOPS_DASHBOARD_API_KEY using constant-time hmac.compare_digest — accepting matching requests (200 OK) and rejecting anyone else (401 Unauthorized).
<log_dir>/ingested_costs.jsonl): Every HTTP-pushed batch is immediately served from bounded in-memory LRU cache (MAX_INGESTED_ROWS = 5,000, source="http_ingest") and appended to central_logs/ingested_costs.jsonl on the dashboard server. If the dashboard server is restarted later with --log-dir central_logs, all previously pushed sessions and agent hierarchies are automatically restored from ingested_costs.jsonl without any data loss or double-counting.When both local logs (jsonl_path / csv_path) and bigquery_table are enabled, the dashboard deduplicates every record by (session_id, scope, agent_name):
0ms from memory/disk; if the same session_id also exists in BigQuery, the duplicate cloud row is ignored.adk-finops report — Local Files + BigQuery)You can generate a unified, deduplicated FinOps report directly from the terminal (or export it as a GitHub PR Markdown table or JSON file) across local .jsonl/.csv logs, BigQuery, or both combined:
adk-finops report)# 1. Unified Rich Terminal Report (merges & deduplicates local ./logs + BigQuery if ADK_FINOPS_BIGQUERY_TABLE is set)
adk-finops report --log-dir ./logs --bigquery-table my-project.finops.agent_costs
# 2. Local Files Only (skip BigQuery)
adk-finops report --log-dir ./logs --no-bigquery
# 3. BigQuery Only (skip local files) and export as a GitHub PR Markdown report
adk-finops report --log-dir none --bigquery-table my-project.finops.agent_costs --format markdown --output finops_report.md
# 4. Filter by Root Agent, Sub-Agent, or Session Outcome (--status success|failed) and export as JSON
adk-finops report --log-dir ./logs --root-agent coordinator_agent --status failed --format json --output failed_runs.json
generate_finops_report)from adk_finops import generate_finops_report
report = generate_finops_report(
log_dir="logs",
bigquery_table="my-project.finops.agent_costs",
include_bigquery=True,
output_format="markdown", # "table" (Rich CLI), "markdown", or "json"
output_path="finops_summary.md",
print_report=True,
)
print("Total Net Spend:", report["kpis"]["total_cost_usd"])
JSONL, CSV, OpenTelemetry)You don't need a cloud warehouse to persist FinOps telemetry. adk-finops includes built-in local file exporters (JSONLExporter, CSVExporter) and an OpenTelemetryExporter that work completely offline or with any observability backend (DuckDB, Pandas, Jaeger, Datadog, Arize Phoenix, Honeycomb).
FinOpsCostPluginfrom adk_finops import FinOpsCostPlugin
finops_plugin = FinOpsCostPlugin(
jsonl_path="logs/finops_costs.jsonl", # or set ADK_FINOPS_JSONL_PATH
csv_path="logs/finops_costs.csv", # or set ADK_FINOPS_CSV_PATH
enable_otel=True, # or set ADK_FINOPS_ENABLE_OTEL=true
export_scope="session", # "session", "turn", or "both"
export_tags={"env": "local_dev"},
)
Each exported row in .jsonl and .csv automatically includes first-class task outcome columns (status, is_failure, error) alongside token counts, USD costs, context caching savings, and agent/model/tool breakdowns (breakdown_by_agent, breakdown_by_model, breakdown_by_tool).
.jsonl / .csv Logs Instantly with DuckDB or Pandas-- Query local JSONL file directly using DuckDB CLI
SELECT
status AS task_outcome,
is_failure AS is_wasted_spend,
COUNT(*) AS total_runs,
ROUND(SUM(total_cost_usd), 4) AS total_spend_usd
FROM read_json_auto('logs/finops_costs.jsonl')
WHERE scope = 'session' AND agent_name IS NULL
GROUP BY 1, 2;
OpenTelemetryExporter)When enable_otel=True (or OpenTelemetryExporter is used), adk-finops enriches the active span and emits gen_ai.finops.<scope> spans with standard attributes:
gen_ai.usage.input_tokens, gen_ai.usage.output_tokens, gen_ai.usage.thoughts_tokens, gen_ai.usage.cached_tokens, gen_ai.usage.total_tokensgen_ai.usage.cost_usd, gen_ai.usage.llm_cost_usd, gen_ai.usage.tool_cost_usd, gen_ai.usage.savings_usd, gen_ai.usage.tool_calls_countgen_ai.finops.breakdown_by_tool (JSON-serialized Agent -> Tool -> Calls & Cost map)gen_ai.finops.task_outcome (success, failed, error, budget_exceeded)gen_ai.finops.is_wasted_spend (true / false)gen_ai.finops.latency_ms, gen_ai.finops.llm_latency_ms, gen_ai.finops.tool_latency_ms, gen_ai.finops.ttft_msgen_ai.finops.output_tokens_per_sec, gen_ai.finops.total_tokens_per_secBigQueryExporter, JSONLExporter, CSVExporter, OpenTelemetryExporter)You can also use any exporter directly in standalone Python scripts or custom agent frameworks:
from adk_finops import CostTracker
from adk_finops.exporters import (
    BigQueryExporter,
    CSVExporter,
    JSONLExporter,
    OpenTelemetryExporter,
)

exporters = [
    JSONLExporter("finops_costs.jsonl"),
    CSVExporter("finops_costs.csv"),
    OpenTelemetryExporter(),
    # BigQueryExporter(table_id="my-gcp-project.finops.agent_costs"),
]

with CostTracker.track_run("batch_job_42"):
    CostTracker.record_usage(
        run_id="batch_job_42",
        model_name="gemini-2.5-pro",
        prompt_tokens=15000,
        completion_tokens=800,
        cached_tokens=12000,
        agent_name="data_extractor",
    )
    CostTracker.record_task_status(session_id="batch_job_42", status="success")

summary = CostTracker.get_summary("batch_job_42")
for exporter in exporters:
    exporter.export_summary(summary, scope="session", tags={"env": "prod", "pipeline": "etl"})
Once data streams into BigQuery, power executive dashboards and chargeback reports with standard SQL:
SELECT
  agent_name,
  COUNT(DISTINCT session_id) AS total_sessions,
  SUM(total_tokens) AS total_tokens,
  ROUND(SUM(llm_cost_usd), 4) AS llm_cost,
  ROUND(SUM(tool_cost_usd), 4) AS grounding_fees,
  ROUND(SUM(total_cost_usd), 4) AS total_spend,
  ROUND(SUM(savings_usd), 4) AS caching_dollars_saved
FROM `my-gcp-project.finops.agent_costs`
WHERE timestamp >= TIMESTAMP_SUB(CURRENT_TIMESTAMP(), INTERVAL 30 DAY)
  AND agent_name IS NOT NULL
GROUP BY 1
ORDER BY total_spend DESC
LIMIT 5;
SELECT
  model_name,
  SUM(cached_tokens) AS total_cached_tokens,
  ROUND(SUM(gross_cost_usd), 4) AS gross_spend_without_cache,
  ROUND(SUM(total_cost_usd), 4) AS actual_net_spend,
  ROUND(SUM(savings_usd), 4) AS net_dollars_saved,
  ROUND(SAFE_DIVIDE(SUM(savings_usd), SUM(gross_cost_usd)) * 100, 1) AS overall_savings_pct
FROM `my-gcp-project.finops.agent_costs`
WHERE timestamp >= TIMESTAMP_SUB(CURRENT_TIMESTAMP(), INTERVAL 7 DAY)
  AND scope = 'session'
  AND agent_name IS NULL
GROUP BY 1
ORDER BY net_dollars_saved DESC;
SELECT
  COALESCE(JSON_VALUE(tags, '$.status'), 'success') AS task_outcome,
  COALESCE(JSON_VALUE(tags, '$.is_failure'), 'false') AS is_wasted_spend,
  COUNT(*) AS total_runs,
  ROUND(SUM(total_cost_usd), 4) AS total_spend_usd,
  ROUND(AVG(total_cost_usd), 4) AS avg_cost_per_task,
  ROUND(AVG(total_tokens), 0) AS avg_tokens_per_task
FROM `my-gcp-project.finops.agent_costs`
WHERE scope = 'session'
  AND agent_name IS NULL
GROUP BY 1, 2
ORDER BY total_spend_usd DESC;
Distributed under the Apache License 2.0. See LICENSE for details.
Download counts and popularity will appear here as the collector receives them.
| Version | Published | Direct dependencies | Open version |
|---|---|---|---|
| 1.0.3 | 3 Oct 2026 | 5 |
This describes our collected data; it is not a security assessment.
Observed since 20 Oct, 19:37 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
package:1148b7181571f5c195543255364ac10291d52e54e1fdb1467a08171589d1ef98