

 Repository
Current collected state Current
Observed since 20 Oct, 20:03 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
A tiny framework to perform adversarial validation of your training and test data.



A tiny framework to perform adversarial validation of your training and test data.
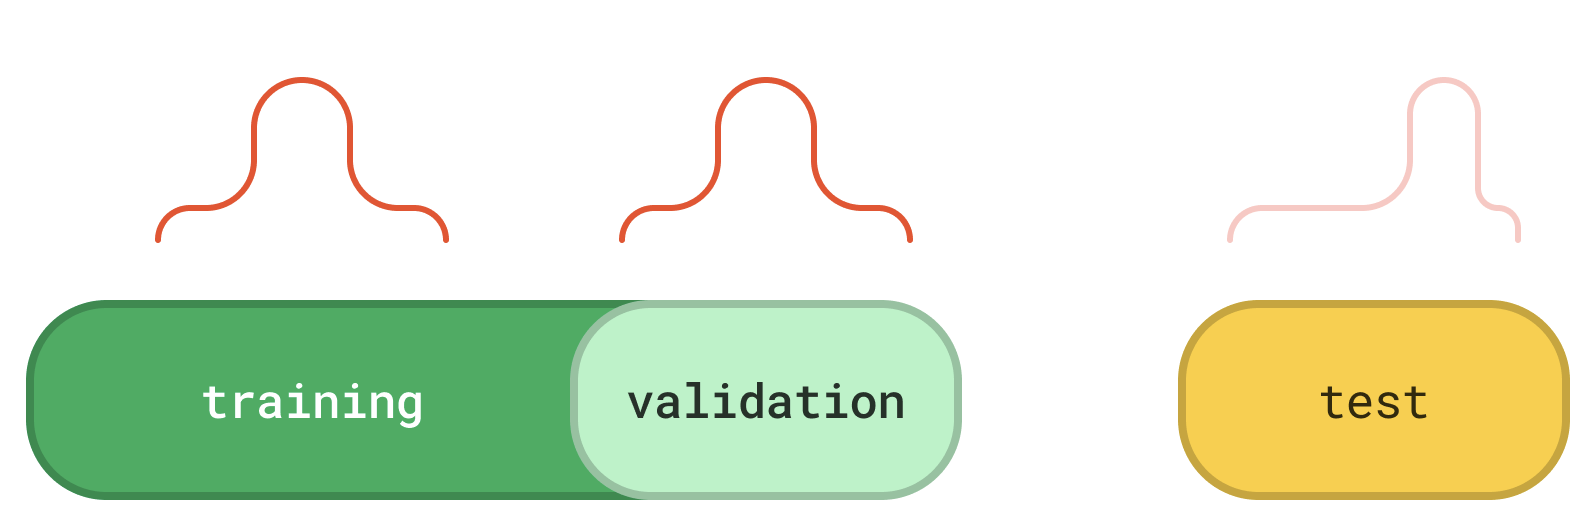
What is adversarial validation? A common workflow in machine learning projects (especially in Kaggle competitions) is:
This strategy is widely accepted, but it heavily relies on the assumption that the training and test datasets are drawn from the same underlying distribution. This is often referred to as the “identically distributed” property in the literature.
This package helps you easily assert whether the "identically distributed" property holds true for your training and test datasets or equivalently whether your validation dataset is a good proxy for your model's performance on the unseen test instances.
If you are a person of details, feel free to take a deep dive to the following companion article:
adversarial validation: can i trust my validation dataset?
The recommended installation is via pip:
pip install advertion
(advertion stands for adversarial validation)
from advertion import validate

train = pd.read_csv("...")
test = pd.read_csv("...")

validate(
    trainset=train,
    testset=test,
    target="label",
)

# // {
# //     "datasets_follow_same_distribution": True,
# //     'mean_roc_auc': 0.5021320833333334,
# //     "adversarial_features': ['id'],
# // }
If you wish to contribute, this is a great place to start!
Distributed under the Apache License 2.0.
Download counts and popularity will appear here as the collector receives them.
| Version | Published | Direct dependencies | Open version |
|---|---|---|---|
| 1.0.1 | 12 Dec 2024 | 5 |
This describes our collected data; it is not a security assessment.
Shared repository data · GitHub
Observed since 20 Oct, 20:03 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
package:76b388cc36bafa6b921c090e4b43c6962d44f99f27ee6d806351b86a33b0d64a