
 Repository
Current collected state Current
Observed since 20 Oct, 21:00 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
Cluster Multiple-Sequence Alignments (MSA) using DBSCAN
A Python-API version of AF_Cluster by Wayment-Steele et al. (2023) In their original GitHub repository
they include scripts to perform MSA clustering but do not have a functional API interface that easily allows integrating their workflow into custom settings. This project adapts and refactors their original ClusterMSA.py script into a API format.
The AFCluster-api version can be install via pip using
pip install afcluster
The core of the API is the AFCluster object which unifies the complete functionality of the package under one hood, including:
The AFCluster class accepts sequence inputs as either
For example:
>>> from afcluster import AFCluster, read_a3m

# load an MSA into a pandas dataframe
>>> msa = read_a3m("tests/test.a3m")
>>> print(msa.head())
                                              header                                           sequence
0                                               >101  MQIFVKTLTGKTITLEVEPSDTIENVKAKIQDKEGIPPDQQRLIFA...
1  >UniRef100_A0A964YKG2\t118\t0.907\t2.876E-28\t...  MQIFVKTLTGKTITLEVEPSDTIENVKAKIQDKEGIPPDQQRLIFA...
2  >UniRef100_A0A177EKP9\t117\t0.894\t3.948E-28\t...  MQIFVKTLTGKTITLEVEPSDTIENVKAKIQDKEGIPPDQQRLIFA...
3  >UniRef100_UPI002231809B\t117\t0.907\t3.948E-2...  MQIFVKTLTGKTITLEVEPSDTIENVKAKIQDKEGIPPDQQRLIFA...
4  >UniRef100_A0A6C0JTL4\t117\t0.894\t5.421E-28\t...  MQIFVKTLTGKTITLEVEPSDTIENVKAKIQDKEGIPPDQQRLIFA...


# now determine an epsilon value for clustering
# (using multiprocessing for spped)
>>> clusterer = AFCluster()
>>> eps = clusterer.gridsearch_eps(msa)
>>> print(f"determined {eps=}")
determined eps=8.0

# now we can cluster (the clusterer remembers the determined epsilon value)
# we also determine the consensus sequence for each cluster and compute
# levenshtein distances (as 1-d !!!) to the query and consensus sequences
>>> out_df = clusterer.cluster(msa, consensus_sequence=True, levenshtein=True)
>>> print(out_df.head())
                                            sequence  cluster_id  ... levenshtein_query levenshtein_consensus
0  MQIFVKTLTGKTITLEVEPSDTIENVKAKIQDKEGIPPDQQRLIFA...          -1  ...          1.000000              0.697368
1  MQVFIKTLTGKTITLDVEPSDTIESVKQKIQDKEGIPPDQQRLIFA...           0  ...          0.907895              0.907895
2  MQIFVKTLTGKTITLDVENSDTVDTVKTKIQDKEGIPPDQQRLIFA...           0  ...          0.894737              0.894737
3  MQIFVKTLTGKTVTLDVDPSDTIENVKAMIQDKEGIPPDQQRLIFA...           0  ...          0.907895              0.907895
4  MQIFVKTLTGKTITLEVDPSNTIETVKQMIQDKEGIPPDQQRLIYA...           0  ...          0.894737              0.894737

# now generate a PCA plot
>>> ax = clusterer.pca() # ax is a matplotlib.Axes object

# and write a3m output files for each cluster to an output directory
>>> clusterer.write_a3m("clustered_results")
>>> clusterer.write_cluster_table("clustered_results/clusters.csv")
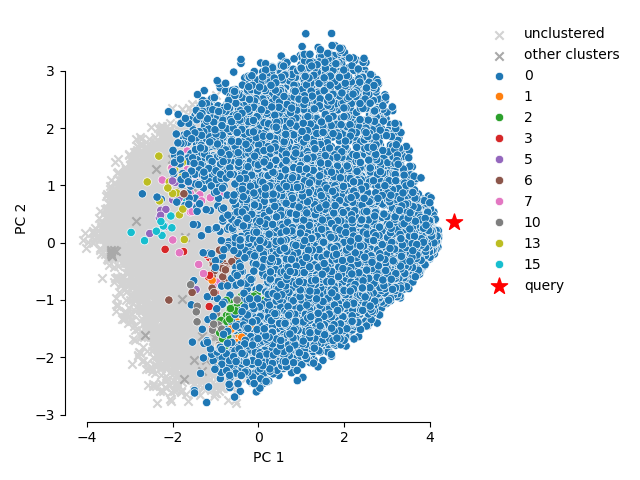
The PCA plot generated with
clusterer.pca(). A difference to the original implementation is that we do not simply highlight the first 10 (default) clusters but the 10 biggest clusters instead.
Since we did some code refactoring, we also benchmarked the performance of our implementation versus Wayment-Steele et al.'s original version. We found that our refactored code base runs in roughly half the time that the original implementation required. A workflow invloving a gridsearch for a suitable epsilon value even ran three times faster compared to the original ClusterMSA.py script.
| method | task | time (s) |
|---|---|---|
| ours | cluster + pca | 9.7 |
| original | cluster + pca | 17.26 |
| ours | search eps + cluster + pca | 29.65 |
| original | search eps + cluster + pca | 102.37 |
| ours | cluster + pca + tsne | 56.44 |
| original | cluster + pca + tsne | 129.55 |
| ours | search eps + cluster + pca + tsne | 98.22 |
| original | search eps + cluster + pca + tsne | 153.63 |
Computation times are averages. Performance measures were computed using the scripts in the
support/performancedirectory, on an M4 Macbook Pro (2024) using 5 repeats each and an MSA with 19K sequences.
Download counts and popularity will appear here as the collector receives them.
| Version | Published | Direct dependencies | Open version |
|---|---|---|---|
| 0.1.2 | 2 May 2025 | 7 |
This describes our collected data; it is not a security assessment.
Shared repository data · GitHub
Observed since 20 Oct, 21:00 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
package:b9bc8073a0b762581b86bba539bc6a71ff04598df24ceb9d92765296ee7525c3