
 Repository
Current collected state Current
Observed since 20 Oct, 21:21 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
Easy to use optimizers with adaptive gradient clipping. Written in PyTorch.
A small lib for using adaptive gradient clipping in your optimizer. Currently PyTorch only.
Brock et al. introduced 2021 a new clipping technique in order to increase stability of large batch training and high learning rates in their Normalizer-Free Networks (NFNet), the adaptive gradient clipping. This clipping method is not implemented in leading frameworks, thus I provide optimizers which are capable of AGC.
pip install agc_optims
To be consistent with PyTorch all arguments of the optimizer remain the same as in the standard. Only two parameters are added for the AGC:
clipping : Hyperparameter for the clipping of the parameter. Default value 1e-2, smaller batch sizes demand a higher clipping parameteragc_eps : Term used in AGC to prevent grads clipped to zero, default value 1e-3from torch.optim import Adam
from agc_optims.clipper import AGC
net = Net() # your model
optimizer = Adam(net.parameters(), lr=0.001)
optimizer = AGC(optimizer=optimizer, clipping=0.16)
from agc_optims.optim import SGD_AGC

net = Net() # your model

optimizer = SGD_AGC(net.parameters(), lr=0.01, momentum=0.9, clipping=0.16)
from agc_optims.optim import Adam_AGC

net = Net() # your model

optimizer = Adam_AGC(net.parameters(), lr=0.001, weight_decay=1e-4, clipping=0.16)
from agc_optims.optim import AdamW_AGC

net = Net() # your model

optimizer = AdamW_AGC(net.parameters(), lr=0.001, weight_decay=1e-4, clipping=0.16)
from agc_optims.optim import RMSprop_AGC

net = Net() # your model

optimizer = RMSprop_AGC(net.parameters(), lr=0.001, clipping=0.16)
Now you can use the optimizer just like their non-AGC counterparts.
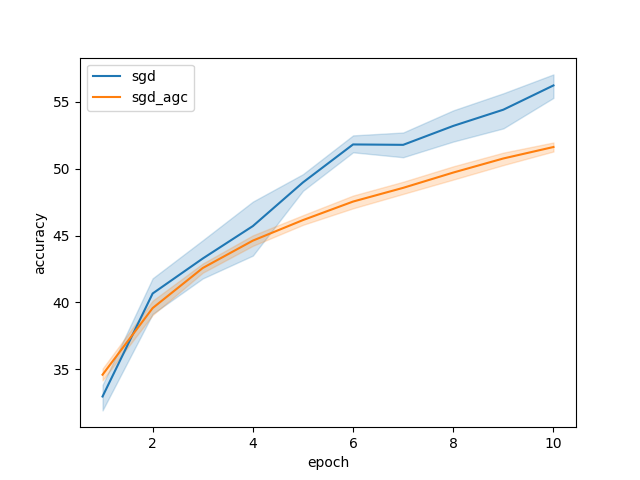
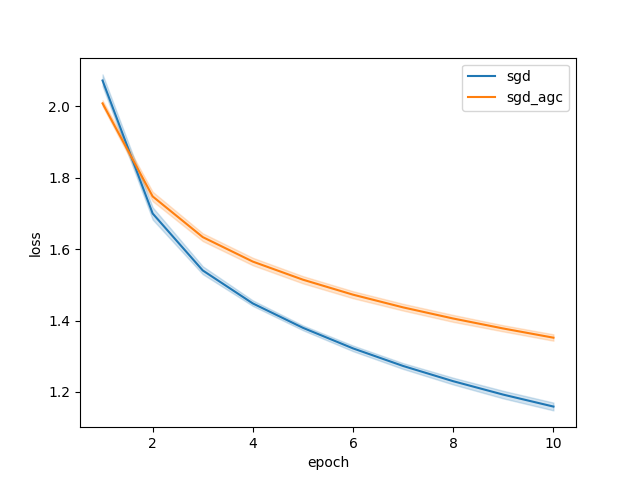
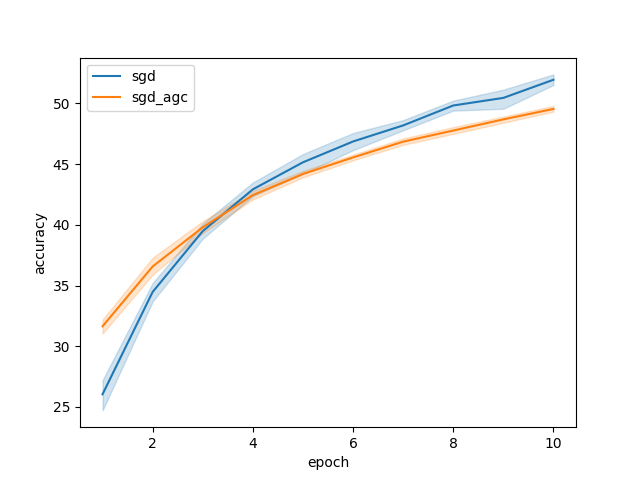
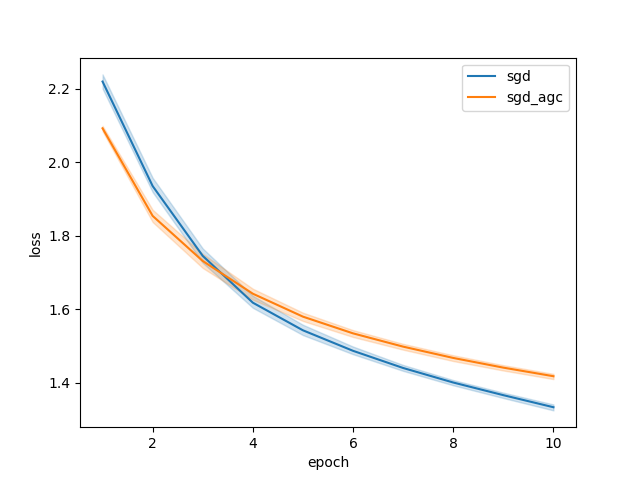
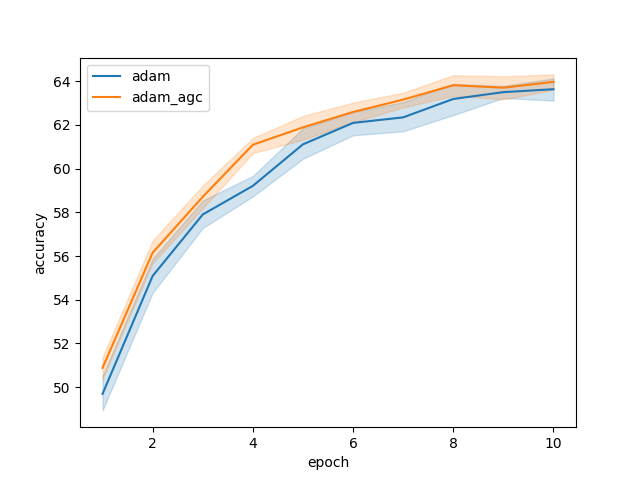
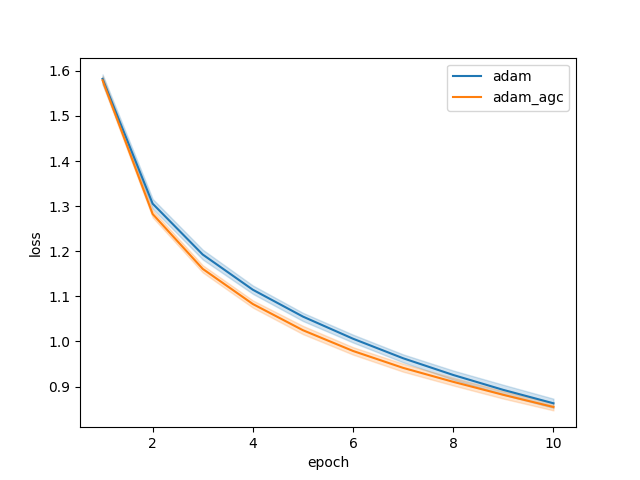
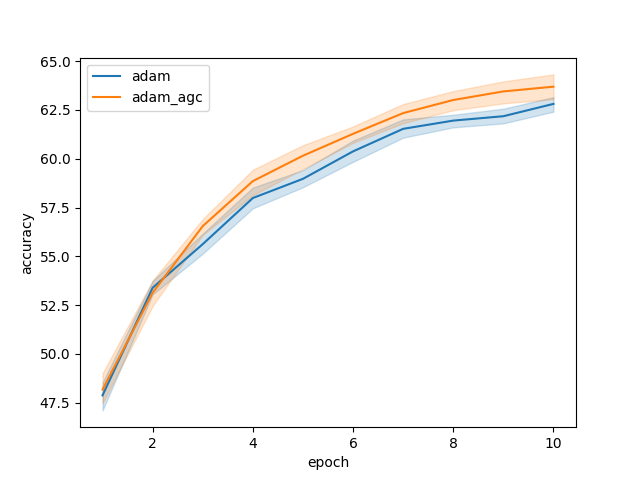
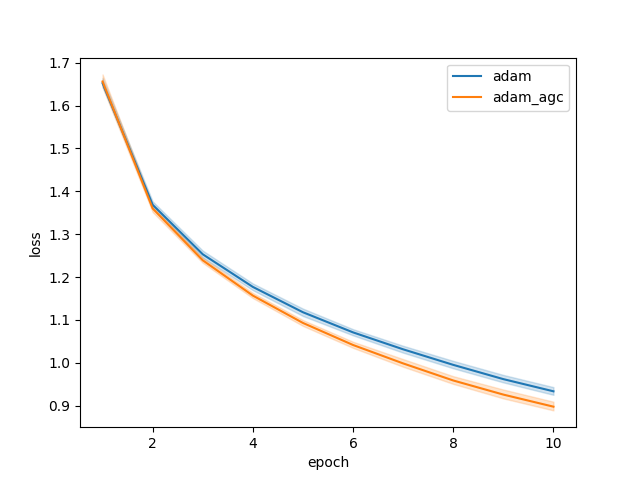
The following comparison shows that for batch sizes 64 and 128 Adam with AGC performs better than the normal Adam. SGD is unfortunately worse with AGC, but the batch size is also very small compared to the NFNet paper. This requires more comparisons with higher batch sizes and also on other data sets. RMSprop is also better at both batch sizes with AGC than without. The learning rate was left at the default value for all optimizers and the scripts in the performance_tests folder were used as the test environment.
| Batch Size 64 - SGD Accuracy on Cifar10 | Batch Size 64 - SGD Loss on Cifar10 |
|---|---|
 |  |
| Batch Size 128 - SGD Accuracy on Cifar10 | Batch Size 128 - SGD Loss on Cifar10 |
|---|---|
 |  |
| Batch Size 64 - Adam Accuracy on Cifar10 | Batch Size 64 - Adam Loss on Cifar10 |
|---|---|
 |  |
| Batch Size 128 - Adam Accuracy on Cifar10 | Batch Size 128 - Adam Loss on Cifar10 |
|---|---|
 |  |
| Batch Size 64 - RMSProp Accuracy on Cifar10 | Batch Size 64 - RMSProp Loss on Cifar10 |
|---|---|
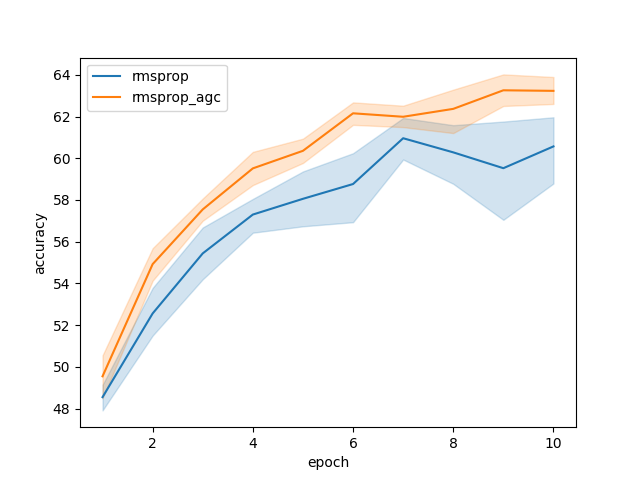 | 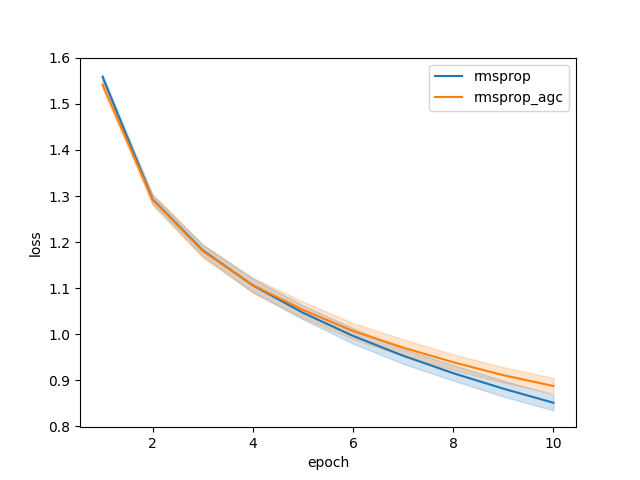 |
| Batch Size 128 - RMSProp Accuracy on Cifar10 | Batch Size 128 - RMSProp Loss on Cifar10 |
|---|---|
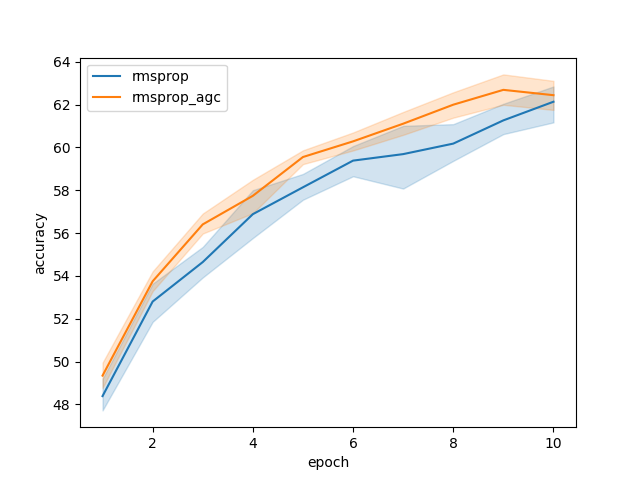 | 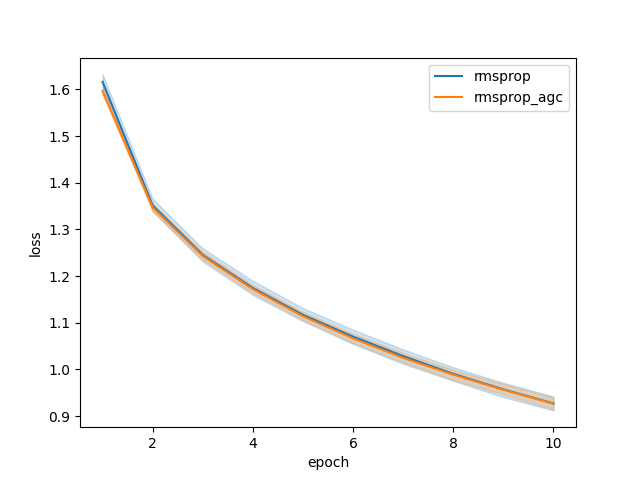 |
As a little treat, I have also compared the speed of the optimizer with and without AGC to see whether this greatly increases training times.
| Batch Size 128 - RMSProp Accuracy on Cifar10 | Batch Size 128 - RMSProp Loss on Cifar10 |
|---|---|
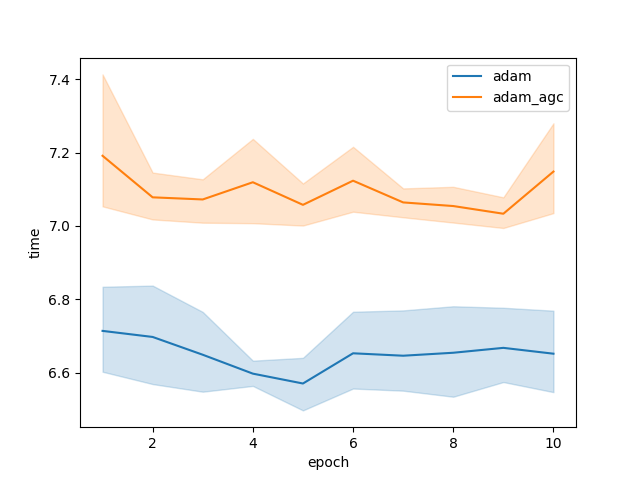 | 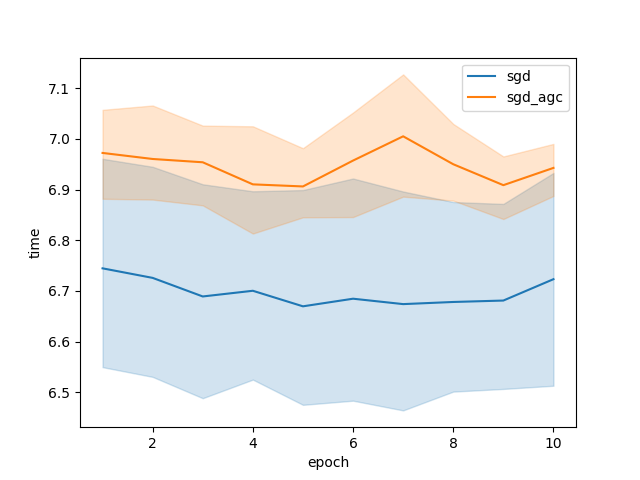 |
Download counts and popularity will appear here as the collector receives them.
| Version | Published | Direct dependencies | Open version |
|---|---|---|---|
| 0.0.2 | 15 Sept 2021 | 1 |
This describes our collected data; it is not a security assessment.
Observed since 20 Oct, 21:21 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
package:62ba93be0a55f6cc95394d3e28890cf1c917a79cbc5528475bc5e02780c09d98