

 Repository
Current collected state Current
Observed since 20 Oct, 21:33 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
Static, pre-deployment analysis of what an agentic system can reach in an AWS account from untrusted model input.


Static, pre-deployment analysis of what an agentic system can actually do to your AWS account.
uvx agent-blast-radius scan ./fixtures/overprivileged-agent
This agent's four tools look scoped. Three hops of IAM later, a prompt injection is an account takeover.
That sentence is the whole project. Everything in this repo exists to make it provable against a real fixture, in CI, before deployment — not in production telemetry after the fact.
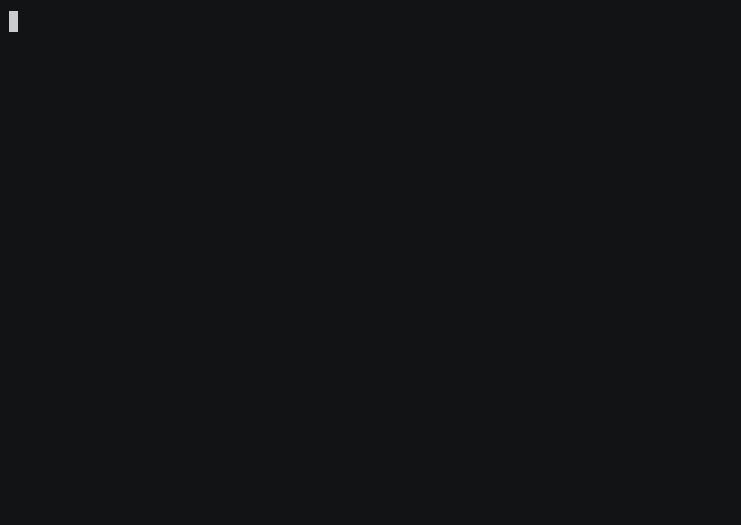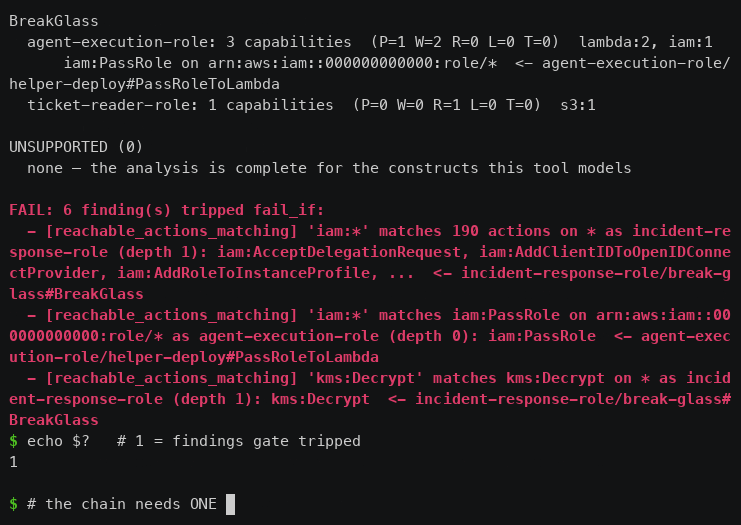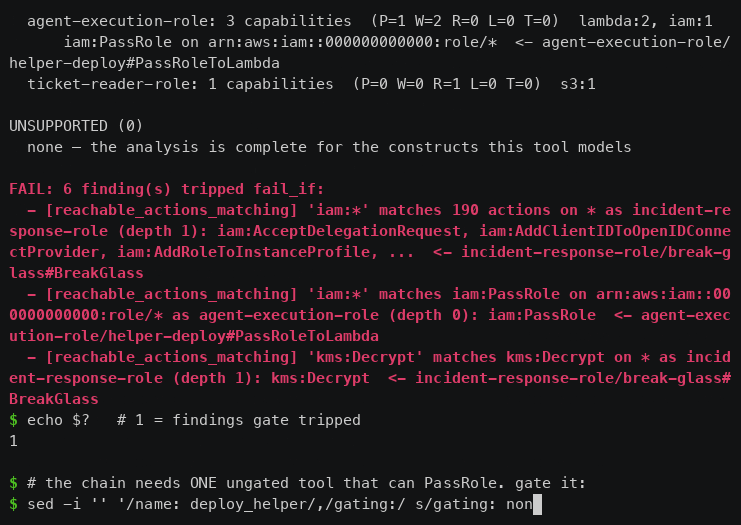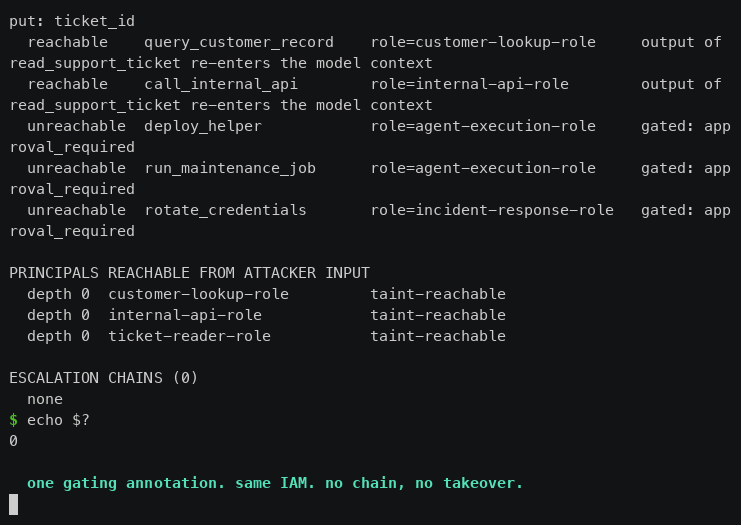
The chain is real and so is the fix: one gating: approval_required annotation on the one ungated
tool that can PassRole, and the same IAM resolves to no chain at all.
$ agent-blast-radius scan ./fixtures/overprivileged-agent
agent-blast-radius  deployment=overprivileged-agent  account=000000000000
  report schema 1.0.0  dataset 8e8e0df0ce50  rules v1

TOOLS
  reachable    read_support_ticket      role=ticket-reader-role       tainted input: ticket_id
  reachable    query_customer_record    role=customer-lookup-role     output of read_support_ticket re-enters the model context
  reachable    call_internal_api        role=internal-api-role        output of read_support_ticket re-enters the model context
  reachable    deploy_helper            role=agent-execution-role     output of read_support_ticket re-enters the model context
  unreachable  run_maintenance_job      role=agent-execution-role     gated: approval_required
  unreachable  rotate_credentials       role=incident-response-role   gated: approval_required

PRINCIPALS REACHABLE FROM ATTACKER INPUT
  depth 0  agent-execution-role         taint-reachable
  depth 0  customer-lookup-role         taint-reachable
  depth 0  internal-api-role            taint-reachable
  depth 0  ticket-reader-role           taint-reachable
  depth 1  incident-response-role       via 1 escalation hop

ACCOUNT TAKEOVER
  Attach AdministratorAccess to a reachable role  [iam-attachrolepolicy-self, rhino-2018]  depth 2
    iam:AttachRolePolicy on *  <- incident-response-role/break-glass#BreakGlass

ESCALATION CHAINS (1)
  -> incident-response-role  via PassRole into a new Lambda function  [passrole-lambda-createfunction, rhino-2018]  depth 1
       iam:PassRole on arn:aws:iam::000000000000:role/*  <- agent-execution-role/helper-deploy#PassRoleToLambda
       lambda:CreateFunction on *  <- agent-execution-role/helper-deploy#ManageHelpers
       lambda:InvokeFunction on *  <- agent-execution-role/helper-deploy#ManageHelpers
       fact: role_trusts_service(role=incident-response-role, service=lambda.amazonaws.com)

REACHABLE CAPABILITIES (199)
  ... (full output in docs/post.md)


UNSUPPORTED (0)
  none — the analysis is complete for the constructs this tool models

Reachability is not exploitability: this is what the tool graph permits if the model
can be induced to make the calls, not a prediction that it will.

FAIL: 9 finding(s) tripped fail_if:
  - 'iam:*' matches 190 actions on * as incident-response-role (depth 1): iam:AcceptDelegationRequest, iam:AddClientIDToOpenIDConnectProvider, iam:AddRoleToInstanceProfile, ...  <- incident-response-role/break-glass#BreakGlass
  - 'iam:*' matches iam:PassRole on arn:aws:iam::000000000000:role/* as agent-execution-role (depth 0): iam:PassRole  <- agent-execution-role/helper-deploy#PassRoleToLambda
  - 'kms:Decrypt' matches kms:Decrypt on * as incident-response-role (depth 1): kms:Decrypt  <- incident-response-role/break-glass#BreakGlass
  - escalation chain passrole-lambda-createfunction -> incident-response-role (depth 1)
  - escalation chain iam-attachrolepolicy-self -> all_actions (depth 2)
  - escalation chain iam-putrolepolicy-self -> all_actions (depth 2)
  - chain passrole-lambda-createfunction -> incident-response-role at depth 1 <= max_chain_depth 2
  - chain iam-attachrolepolicy-self -> all_actions at depth 2 <= max_chain_depth 2
  - chain iam-putrolepolicy-self -> all_actions at depth 2 <= max_chain_depth 2
$ echo $?
1
An attacker controls text that reaches the model: a support ticket, a scraped page, a document in a bucket the agent reads. They cannot call AWS directly. They can only induce the model to call the tools it already has.
The question this tool answers: given that starting position, what set of AWS actions becomes reachable?
It answers it by:
iam:PassRole + lambda:CreateFunction surface as single findings with a provenance path.This tool computes what the tool graph permits if the model can be induced to make the calls. It does not predict whether a given model will. It is a map of unlocked doors, not a prediction of which door someone walks through. Every finding should be read that way.
This re-implements policy resolution that Cloudsplaining and PMapper already do well. I built it to understand IAM evaluation from the inside, and extended it with taint propagation from untrusted model input, which those tools don't model.
| Prior art | What it covers |
|---|---|
| Cloudsplaining (Salesforce) | Least-privilege violations, wildcard detection, roles assumable by compute services |
| PMapper (NCC) | Principal-to-principal privilege escalation graphs |
| Parliament (Duo) | Policy linting |
| Rhino Security Labs | The canonical AWS privilege-escalation method list |
| Obsidian, Grafyn, Entrust | Commercial "agent blast radius" — runtime, SaaS-identity focused |
| AgentWard | Published cross-server MCP escalation chains against awslabs/mcp |
| AWS Agent Toolkit | IAM condition keys distinguishing agent actions from human ones |
The open gap is not detection quality. Everything commercial here is runtime observability. Nobody is doing static, pre-deployment, CI-gating analysis over Terraform plus tool manifests. That is the pitch: shift-left for agent permissions — catch the chain in the PR.
In scope (v1)
iam:PassRole + lambda:CreateFunction cannot be resolved without it —
PassRole only succeeds if the target role's trust policy admits lambda.amazonaws.com.Deny, evaluated after the allow set is assembled.Out of scope, deliberately — ordered by impact on this threat model
That ordering is not the conventional one. It follows from the threat model: this tool is about what untrusted input reaches, and the largest unmodeled reach is cross-account via resource policies.
Single-account assumption. Stated in the IR and enforced in the analyzer. Cross-account reach lives in the gap above.
Gating is the load-bearing axis. A survey of real deployments
(docs/q2-shared-roles.md) found that locally-run MCP servers and
framework-on-Lambda agents put every tool behind one credential, while Bedrock action groups and
Lambda-backed tools get per-tool roles — but every platform exposes per-tool gating (MCP client
autoApprove, Bedrock requireConfirmation, AgentCore policy engine). So reachability is computed
over gating first and the role graph second, and a single-role deployment with no gating annotations
is told plainly that taint propagation adds nothing, rather than being handed a re-skinned
Cloudsplaining report.
Set inversion is done where it is exact and refused where it is not. Allow + NotAction is
inverted — the granted set is every known action minus the exclusions — because the action universe
is finite and enumerable. The one exposure is snapshot staleness, recorded per statement in the
report's assumptions section. Deny + NotAction is refused: inverting it on a stale snapshot
would shrink the denied set and hand back capabilities AWS blocks, a false negative. NotResource
is refused outright, because ARNs are not enumerable. A refused statement is skipped and recorded in
the report's unsupported section with its policy and statement ID; the scan continues, and CI
fails closed on a non-empty unsupported list by default. That section also carries attached
managed policies the vendored snapshot doesn't know and actions it doesn't recognise.
Conditions. StringEquals, StringLike, ArnLike, and Bool are modeled and carried on the
capability. Every other operator is recorded as residue and the capability is reported as
unconstrained but flagged — the conservative direction. A Deny only removes a capability when
it is unconditional and its resource pattern fully subsumes the capability's; a conditional or
partial Deny is flagged, never trusted.
Action dataset. Wildcards expand against a pinned snapshot of the AWS Service Authorization
Reference (via iam-dataset), not botocore. botocore lists
API operations, and IAM actions are not API operations: iam:PassRole and s3:ListBucket do not
exist there, and expanding iam:* from it would silently drop the action the headline finding
depends on. The snapshot commit is in src/agent_blast_radius/data/VERSION and printed in every
report.
No 0–100 score. It invites "how is that computed" and there is no good answer.
examples/awslabs-iam-mcp-server runs the analyzer
against a published AWS Labs MCP server — 29 IAM tools under one credential — rather than against
this repo's own fixture. It found a non-existent action (iam:GetGroupsForUser) in the server's
documented permission policy, a documented CLI flag that no longer exists, and a credential that is
not scoped to the server's own read-only default. It also names one place where this analyzer
over-reports. Not a vulnerability report: everything there is public, documented, intentional
behaviour, and their secure-by-default design is credited first.
The resolver is only worth trusting if it agrees with AWS, and the interesting question is where it disagrees.
Differential harness. A fixed corpus of 44 managed policies chosen for construct diversity, plus
the fixture's roles, tested against iam:SimulateCustomPolicy. Draws are seeded and stratified —
half allow-expected, half deny-expected — and the deny half is weighted toward near-misses (right
action / wrong resource, failing condition, actions just outside a wildcard boundary, explicit
Deny, NotAction exclusions), because uniform draws are trivially denied and would inflate the
numbers. The output is a confusion matrix, not an agreement rate; the cell that matters is
resolver says deny, AWS says allowed. Needs one permission (iam:SimulateCustomPolicy), creates
nothing, costs nothing.
Result (2026-09-02, 1,148 draws, 232 calls): zero silent under-reports, and every remaining
over-report is one documented decision. The deny / allowed cell — the resolver calling
something unreachable that AWS would permit — is empty across every draw, including the half
deliberately built as near-misses. So is allow / implicitDeny. The 13 that remain are all the
same refusal (D1b), measured in docs/divergences.md. The run also found a
real resolver gap (D7: action-to-resource-type compatibility), which is now fixed — over-reports
fell 48 → 13 with the under-report cell still empty. Replay the whole run offline from the
committed cassette; no credentials needed.
Live authorization probe (done). A smaller independent check that needs no special permission:
call read-only APIs under a known policy and compare the authorization outcome to the resolver's
prediction, classifying AccessDenied as denied, success as allowed, and any other service error as
allowed-but-service-refused. That third case is the discriminator — it proves authorization passed.
10/10 agreement across PowerUserAccess, including iam:SimulateCustomPolicy itself:
full write-up.
Offline pre-flight (runs in CI). validate --preflight checks the resolver against each
draw's own expectation with no AWS account at all. This is a lint pass, not validation: it
shares the resolver's assumptions about IAM and so cannot catch a misread of the semantics, which is
exactly what the differential run is for. Passing it is not evidence of correctness. It is still
worth running — the boundary strata build their expectations in code that never consults the
resolver's answer path, and it caught three real defects the day it was written.
--record and --replay turn one live run into a permanent, credential-free regression corpus.
Intentional divergences are numbered in docs/divergences.md.
uvx agent-blast-radius scan ./fixtures/overprivileged-agent
No manual setup, no deployed AWS resources, no credentials. The action dataset and the managed policy documents are vendored and pinned; a scan never touches the network.
agent.yaml describes the deployment either as inline IR or as sources + annotations:
sources:
  terraform_plan: plan.json                 # roles, trust policies, Lambda -> role links
  mcp_tools: mcp-tools.json                 # tool names + argument schemas
  bedrock_action_groups: [action-group.json]  # functions, requireConfirmation, shared Lambda
annotations:                                # per tool: what no document can say
  read_support_ticket:
    gating: none
    tainted_inputs: [ticket_id]             # validated against the tool's declared arguments
    returns_external_data: true             # its output re-enters the model context
  run_maintenance_job: {}                   # gating declared by Bedrock; still needs an entry
Every tool needs an annotation entry. Gating is never assumed to be none.
fail_if:
  reachable_actions_matching: ["iam:*", "sts:AssumeRole", "kms:Decrypt"]
  escalation_chains_found: true
  max_chain_depth: 2               # fail on any chain reachable in <= 2 hops
  unsupported_statements: true     # default: fail closed when the analysis skipped something
| exit | meaning |
|---|---|
| 0 | clean |
| 1 | a findings gate tripped |
| 2 | incomplete: unsupported is non-empty |
| 3 | both |
| 4 | input error |
Findings and incompleteness are gated independently and never collapse into one code, so a run
that skipped a NotAction statement cannot pass as clean, and a real finding cannot hide behind
an incompleteness failure. The repo's own CI asserts the fixture exits with exactly 1.
--json report.json writes the versioned report (schema 1.0.0); the terminal output is rendered
from that same model. There is no score.
v0.1.0 on PyPI. Feature-complete against the project plan; see docs/roadmap.md for the build order.
| Component | State |
|---|---|
| IR (tools, roles, policies, taint, gating) | done |
IAM resolver — identity + managed + trust, Deny, wildcards, conditions, NotAction inversion | done |
| MCP / Bedrock / Terraform parsers + annotation overlay | done |
| Reachability fixpoint + rule pack (13 cited rules, bound hyperedges) | done |
| Reporting (schema 1.0.0) + CI mode with independent exit codes | done |
| Offline pre-flight + cassette record/replay | done, in CI |
| Live authorization probe (10/10) | done |
| Test suite | 202 tests, 96% line coverage |
Differential run vs iam:SimulateCustomPolicy | done — 1,148 draws, 0 silent under-reports, replayable offline |
Beyond the documented scope gaps:
${aws:PrincipalAccount}) are not
exercised by the validation harness — a draw cannot supply a value AWS will resolve the same way,
so those go untested (D8).Null is the third most common in the managed-policy
corpus (509 uses) and everything else lands in residue as unconstrained but flagged.MIT. See LICENSE.
Download counts and popularity will appear here as the collector receives them.
| Version | Published | Direct dependencies | Open version |
|---|---|---|---|
| 0.2.0 | 2 Sept 2026 | 6 |
This describes our collected data; it is not a security assessment.
Shared repository data · GitHub
Observed since 20 Oct, 21:33 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
package:6e3bdaca0fdf643b43bef8e95fcb84ce01dfc754dca16b1bb0532a3d50dbdb5e