
 Repository
Current collected state Current
Observed since 20 Oct, 22:50 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
Turn Langfuse/LangSmith agent traces into human-readable Agent Activity Reports (Markdown + HTML).

Turn raw LLM agent traces into a report a manager can actually read - what your agents did, whether it was worth it, and what it cost. Point it at a Langfuse (or LangSmith) export (or add a one-line live callback) and get clean Markdown + a self-contained HTML report - and a local dashboard - in plain business language.
It's one line to switch on. An engineer drops a single callback into your existing agents - no rebuild, no new infrastructure, no traces to wire up - and the live dashboard starts filling in. Works in any LangChain or LangGraph app today (more frameworks on the roadmap).
Three questions about any agent in production. Your existing tools answer the first two:
| Question | Answered by | |
|---|---|---|
| Does it run? | observability - traces, tokens, latency | |
| Is it correct? | evals - scores on a test set | |
| → | Is it worth it? | agent-panorama |
It answers the third - the one your CEO, client, or PM actually asks - across three rungs over the same conversations:
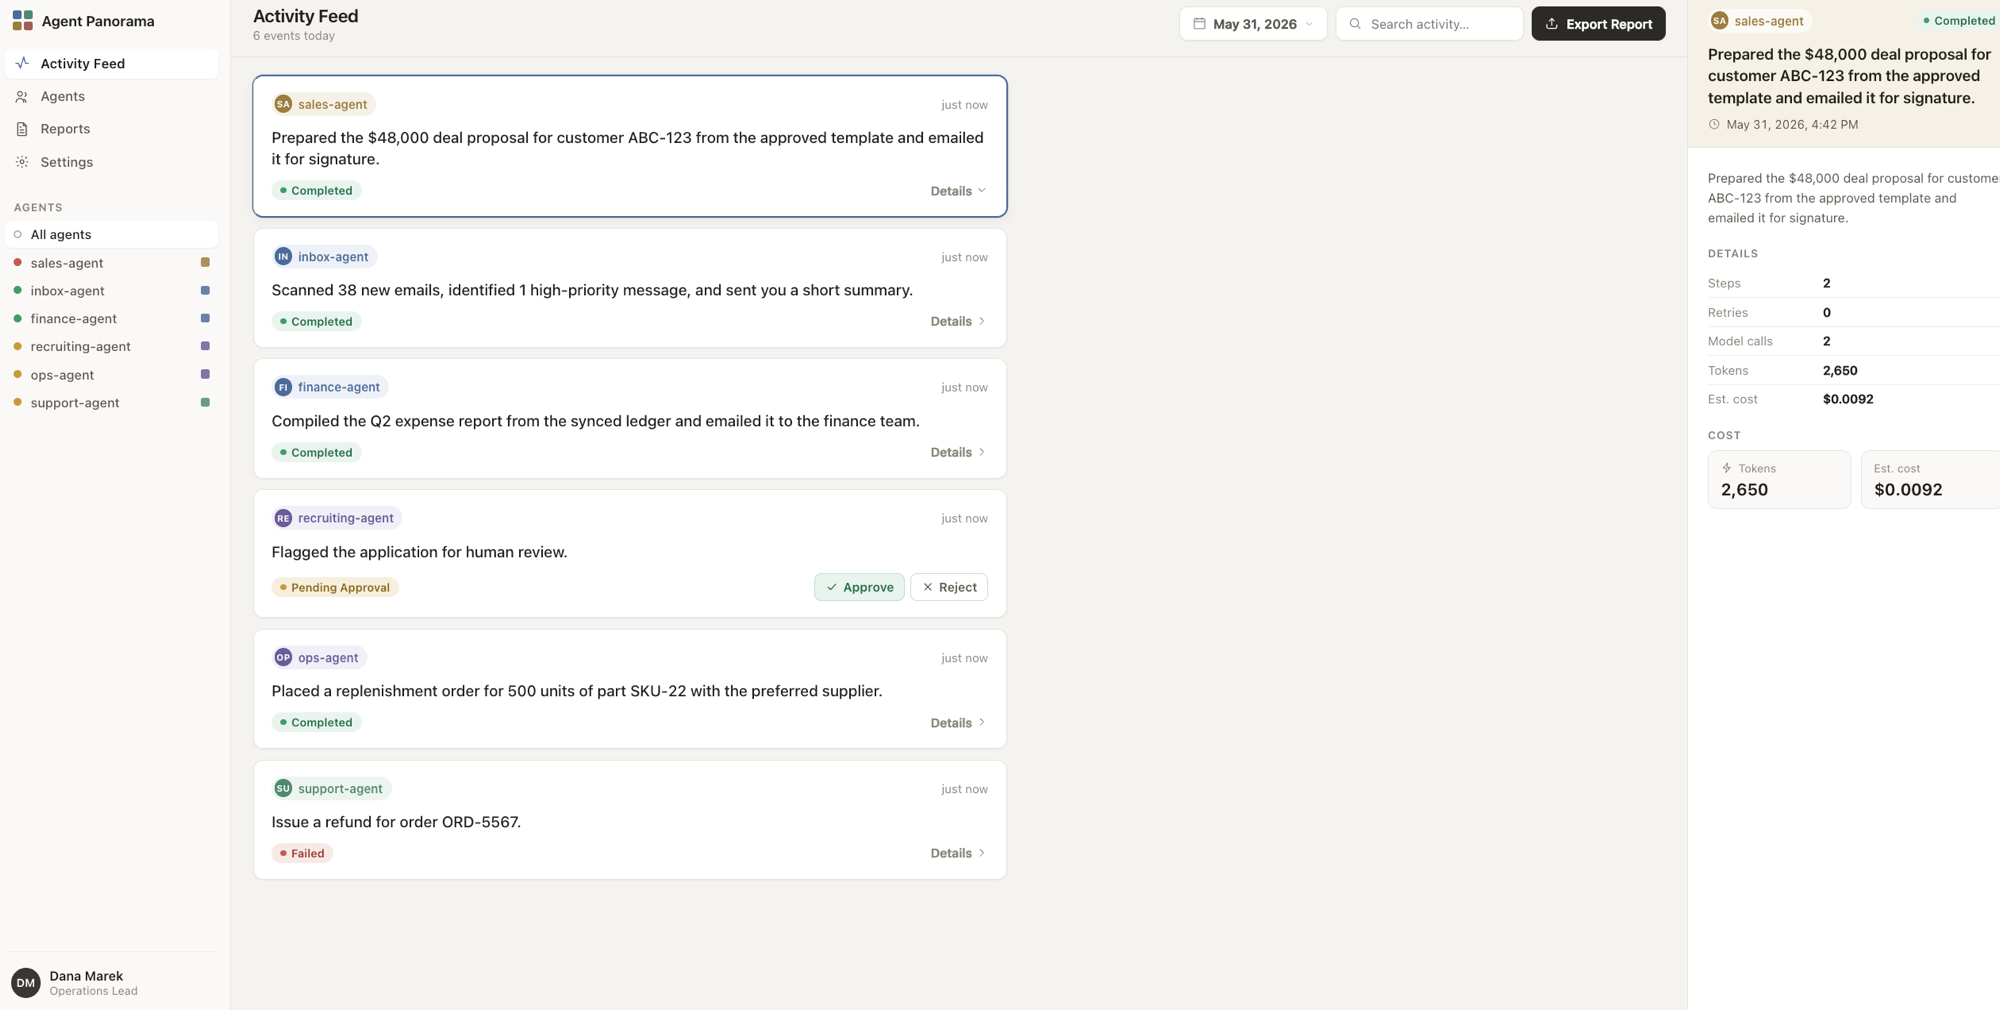
The fleet view - one plain-English activity feed across every agent, with per-run details, outcomes, and cost.
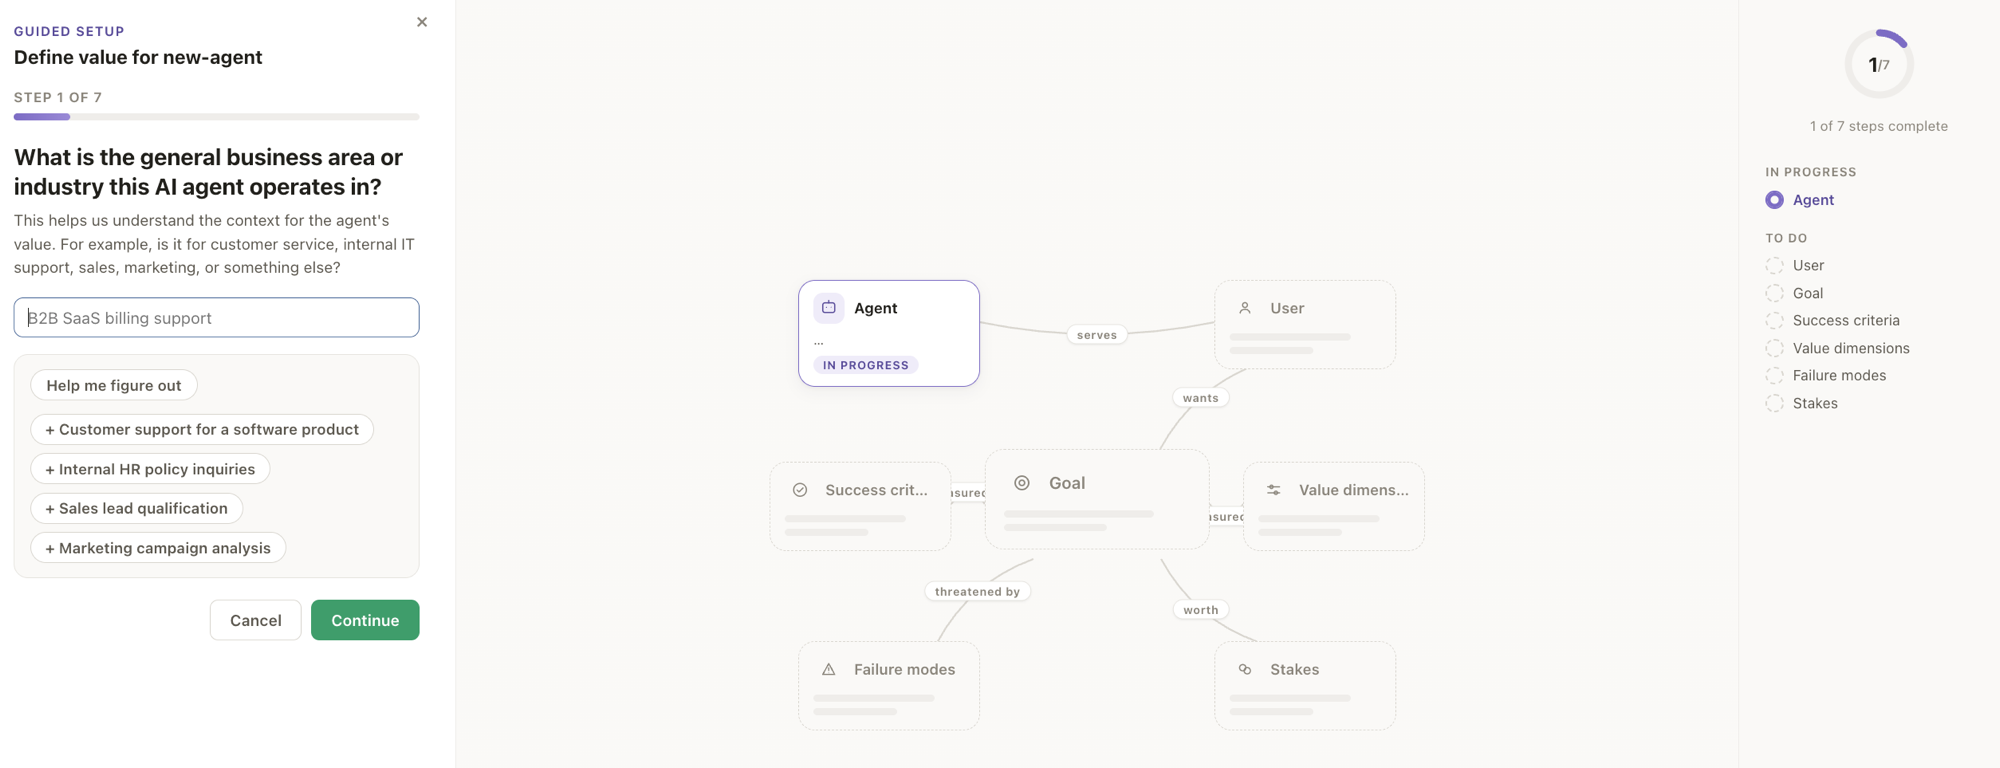
Define value without YAML - a guided wizard fills in each agent's value ontology as a live constellation map, then a Value Blueprint summarizes it.
Traces are great for engineers and terrible for everyone else. agent-panorama
translates tool calls, retries, token usage, and errors into plain English. It
also pulls the real user request and final answer out of LangGraph/LangChain
messages payloads, so the report reads like a story, not a JSON dump:
get_weather({"city": "Paris"}) → "Looked up the weather"human_handoff(...) → run outcome human-escalatedTokens are the primary metric. USD cost is opt-in (since v0.2): supply a
model_prices table in your config and the report adds dollar estimates
alongside tokens (no prices ⇒ cost stays hidden).
pip install agent-panorama
# or, for local development:
uv pip install -e ".[dev]"
Requires Python 3.10+. Dependencies are intentionally minimal: click,
jinja2, pyyaml, python-dotenv.
The fastest way in: drop one callback into your existing LangChain / LangGraph app and watch every completed run land on a local dashboard. No rebuild, no new infrastructure, no traces to export.
1. Install with the live extra:
pip install 'agent-panorama[live]'
2. Add the callback to your agent - one line, wherever you invoke:
from agent_panorama.live import PanoramaCallbackHandler

agent.invoke(inputs, config={"callbacks": [PanoramaCallbackHandler()]})
That's the whole integration. The handler ships with the base package and posts runs over the standard library, so your agent app never needs the server dependencies - and delivery never raises or blocks beyond a 2 s timeout (if the dashboard is down, the app logs one warning and keeps working).
3. Run the dashboard and watch runs stream in:
agent-panorama serve --open # dashboard at http://localhost:8321
Each run appears in the activity feed within seconds of finishing - outcome,
tool calls, tokens, anomalies, and per-agent rollups all update live (the
dashboard polls /api/report every 3 s).
Multi-turn chat agent? Pass
metadata={"session_id": ..., "user_id": ...}in the invoke config so a whole conversation collapses into one feed entry - see Sessions. Prefer working from exported Langfuse / LangSmith traces instead of live? See CLI usage below. More on the live server (flags, safety, demos) is in Live mode.
Already have exported Langfuse or LangSmith traces? Generate a one-shot
Markdown + HTML report (and report.json for the dashboard) straight from them -
no callback, no live server:
agent-panorama generate --input traces.json --output ./report --format html
Options:
| Option | Description |
|---|---|
--input | Path, glob, or directory of JSON exports. Repeatable; globs/dirs are expanded (required). |
--output | Output directory (default ./report). |
--format | md, html, json, or both (= md+html; default both). |
--input-type | langfuse or langsmith (default langfuse). |
--config | Optional YAML config (tool naming, thresholds, model_prices). |
--detail | Step narrative detail: minimal, standard (default), or richer. |
--session | Keep only runs matching this session id. |
--since / --until | Keep only runs whose start time is within this ISO date/datetime window (UTC). |
--summarize | Phrase each minimal result via a cheap LLM (opt-in, off by default). See below. |
--summarize-model | LLM id for --summarize (default google_genai:gemini-2.5-flash-lite). |
Try it on the bundled example, or aggregate a whole fleet:
agent-panorama generate --input examples/langfuse_traces.json --output ./report

# many traces → one fleet report + a feed.json for the dashboard
agent-panorama generate --input 'traces/*.json' --input more/ \
  --since 2026-05-01 --until 2026-05-31 --format json --output ./report
Multiple --input flags, glob patterns, and directories are all expanded and
aggregated into one report. The report then carries a cross-agent activity
feed and per-agent rollups (runs, actions, success/escalation/retry rates,
tokens, and cost when model_prices is set). --format json writes a
report.json with a stable contract (generated_at, time_range, totals,
feed, rollups, decision_log) consumed by the frontend dashboard.
Add a model_prices table to your config to get dollar estimates next to tokens
(prices are USD per 1M tokens; keys match model names by substring, longest
match wins):
model_prices:
  gpt-4o-mini: { input: 0.15, output: 0.60 }
  gpt-4o:      { input: 2.50, output: 10.00 }
  claude-3-5-sonnet: { input: 3.00, output: 15.00 }
With no model_prices block, cost is omitted entirely and tokens remain the
only metric.
report.json contract--format json writes a report.json with a stable shape (also the input the
dashboard consumes). Every timestamp is ISO-8601 UTC or
null; every *cost_usd is a number or null (null when no model_prices
matched). outcome is one of success, human-escalated, failure, unknown.
{
  "generated_at": "2026-05-31T09:42:00+00:00",
  "time_range": { "start": "…", "end": "…" },
  "totals":     { "runs": 4, "steps": 7, "tokens": 3990, "cost_usd": 0.0134,
                  "value": null },           // value summary when the value layer is on
  "feed": [                                  // one entry per run, newest first
    {
      "run_id": "…", "agent_name": "research-assistant",
      "agent_key": "research-assistant",     // slug, for stable UI grouping/colour
      "action": "Searched the web and summarized 3 papers.",
      "outcome": "success", "timestamp": "…",
      "retry_count": 0, "anomaly_count": 0,
      "tokens": 1234, "cost_usd": 0.006,
      "summary": "…", "facts": [["Steps", "5"], ["Retries", "0"]],
      "anomalies": [],
      "value": null                          // ValueJudgment when judged (see value layer)
    }
  ],
  "rollups": [                               // one per agent
    {
      "agent_name": "research-assistant", "agent_key": "research-assistant",
      "runs": 1, "actions": 5,
      "success_rate": 1.0, "escalation_rate": 0.0,
      "failure_rate": 0.0, "retry_rate": 0.0,
      "total_tokens": 1234, "total_cost_usd": 0.006,
      "judged": 0, "avg_value_score": null,  // value layer metrics (null when off)
      "valuable_rate": null, "cost_per_valuable_usd": null
    }
  ],
  "decision_log": [                          // consequential actions across agents
    { "timestamp": "…", "agent_name": "…", "action": "…",
      "parameters": "…", "outcome": "succeeded" }
  ]
}
from agent_panorama import generate_report

report = generate_report(
    "traces.json",
    output_dir="./report",
    formats=["md", "html"],
    input_type="langfuse",
    config="config.yaml",  # optional
)

print(report.total_runs, report.total_tokens)
generate_report returns the in-memory Report, so you can also inspect runs,
the decision log, and anomalies programmatically without touching disk (use
build_report_from_file if you want the report without writing files).
generate_report (and the lower-level build_report_from_inputs) accept a glob,
a directory, or a list of paths via inputs=, plus session / since / until
filters. The returned Report exposes the cross-agent feed and per-agent
rollups; serialize_report gives you the report.json dict directly.
from agent_panorama import (
    generate_report, build_report_from_inputs, load_runs,
    load_config, serialize_report,
)

report = generate_report(
    inputs=["traces/*.json", "more/"],   # globs, dirs, or a single path
    formats=["json"],                    # writes report.json
    since="2026-05-01", until="2026-05-31",
    config="config.yaml",                # model_prices here ⇒ cost is populated
)

for item in report.feed:                 # newest-first activity feed
    print(item.agent_name, item.action, item.outcome.value, item.tokens, item.cost_usd)

for r in report.rollups:                 # per-agent success/escalation/retry rates
    print(r.agent_name, r.runs, r.success_rate, r.escalation_rate, r.retry_rate)

# No files? Build in memory and serialize the JSON contract yourself:
runs = load_runs("traces/*.json", session="abc123")
mem = build_report_from_inputs("traces/*.json", "langfuse", load_config("config.yaml"))
payload = serialize_report(mem, load_config("config.yaml"))  # -> dict
model_prices is set).--detail level), final
outcome, and a confidence signal (retries / fallback).All configuration is optional. See config.example.yaml
for the full set. Highlights:
tool_descriptions:
  get_weather: "Looked up the weather"

consequential_tools: [send_email, human_handoff]
escalation_tools: [human_handoff, handoff_to_agent]

anomaly_thresholds:
  max_retries: 2
  max_latency_seconds: 30
  max_tool_calls: 15
By default the report uses no LLM - it just reformats trace data. But in
--detail minimal, a long final answer (e.g. a big Markdown table) is condensed
with a simple heuristic, which keeps the agent's own wording ("Here are all the
open support tickets"). If you'd rather get a crisp past-tense action
line that keeps the identifying details and the bottom-line takeaway
("Resolved Acme Corp's billing question - refund issued, ticket closed."),
enable the opt-in --summarize flag, which rewrites just the
result via a cheap model.
It is intentionally tiny: a ~40-token fixed system prompt, at most ~250 input tokens (the result is hard-capped at 1,000 characters), and a ~25-token reply
Install a provider extra (pick the one matching your model):
pip install "agent-panorama[gemini]"     # Google Gemini (recommended, free tier)
pip install "agent-panorama[openai]"     # OpenAI
pip install "agent-panorama[anthropic]"  # Anthropic
Get your own API key from the provider and either export it or put it in a
.env file in the working directory (auto-loaded; real env vars win):
export GOOGLE_API_KEY=...      # Gemini
# or OPENAI_API_KEY / ANTHROPIC_API_KEY
# …or a .env file:  GOOGLE_API_KEY=...
Run with --summarize:
agent-panorama generate --input traces.json --output ./report \
  --detail minimal --summarize
# pick a different model:
agent-panorama generate --input traces.json --output ./report \
  --detail minimal --summarize --summarize-model openai:gpt-5-nano
If the provider package or key is missing, summarization is skipped gracefully (you just get the heuristic line) - it never breaks report generation.
Every call is logged to <output>/llm_calls.log - the exact system prompt,
the input sent (with its character count), and the output (or error) for each
run - so you can audit precisely what went to the model.
For this tiny one-shot call any of these is more than capable, so free-tier access and price dominate. Only Gemini Flash / Flash-Lite have a genuine no-credit-card free tier; OpenAI/Anthropic require a positive balance.
Model (--summarize-model) | Price /1M (in → out) | Free tier | Provider extra | API key env var |
|---|---|---|---|---|
google_genai:gemini-2.5-flash-lite (default) | $0.10 → $0.40 | ✅ free, no card (~1,500 req/day) | gemini | GOOGLE_API_KEY |
google_genai:gemini-2.5-flash | $0.30 → $2.50 | ✅ free tier (lower quota) | gemini | GOOGLE_API_KEY |
openai:gpt-5-nano | $0.05 → $0.40 | ⚠️ no free tier (prepaid) | openai | OPENAI_API_KEY |
openai:gpt-4.1-nano | $0.10 → $0.40 | ⚠️ no free tier | openai | OPENAI_API_KEY |
openai:gpt-4o-mini | $0.15 → $0.60 | ⚠️ no free tier | openai | OPENAI_API_KEY |
anthropic:claude-haiku-4-5 | $1.00 → $5.00 | ⚠️ trial credits only | anthropic | ANTHROPIC_API_KEY |
Pick google_genai:gemini-2.5-flash-lite (the default) to run this for free.
gpt-5-nano has the lowest paid input price if you already use OpenAI.
Prices verified May 2026 against providers' official pricing pages; check them for current rates.
{"trace": {...}, "observations": [...]} shape, a list of traces, or the
{"data": [...]} list-API shape. Tool calls are read from TOOL
observations (falling back to tool spans), and from toolCalls / OpenAI-style
tool_calls declared on generations.{"runs": [...]}) of run nodes;
each root run is flattened into one agent run.Token usage is read from the trace (inputUsage/outputUsage or
usage/usage_metadata). Dollar cost is opt-in via a model_prices config
table (see USD cost).
A manager-facing Agent Panorama dashboard lives in frontend/
(Vite + React + TypeScript, outside the Python package). It renders the
report.json produced by --format json, falling back to bundled demo data
when no JSON is present.
See frontend/README.md for setup; in short:
agent-panorama generate --input 'traces/*.json' --format json --output ./report
cp report/report.json frontend/public/feed.json
cd frontend && npm install && npm run dev
Watch your agents live instead of from after-the-fact exports. One line in any LangChain / LangGraph app streams every completed run to a local dashboard:
from agent_panorama.live import PanoramaCallbackHandler

agent.invoke(inputs, config={"callbacks": [PanoramaCallbackHandler()]})
Then run the dashboard server (one-time install of the live extra):
pip install 'agent-panorama[live]'
agent-panorama serve --open        # dashboard at http://localhost:8321
Each run appears in the activity feed within seconds of finishing - outcome,
tool calls, tokens, anomalies, and per-agent rollups all update live (the
dashboard polls /api/report every 3 s).
Designed to be safe in the instrumented app:
--max-runs caps retention) and applies the
same analysis as batch reports, so outcomes/anomalies match generate.Useful flags: --port, --host, --config your.yaml (same YAML as
generate - tool descriptions, escalation tools, model prices), --max-runs.
Point the handler elsewhere with PanoramaCallbackHandler(endpoint=...) or the
AGENT_PANORAMA_ENDPOINT env var.
A chat agent answering 4 questions is still doing one thing for one user -
so the feed aggregates by (session, actor). Pass them in the invoke config
(LangGraph's thread_id works automatically):
agent.invoke(inputs, config={
    "callbacks": [PanoramaCallbackHandler()],
    "metadata": {"session_id": "support-42", "user_id": "user-7"},
})
All turns of that pair collapse into a single feed entry with an
Interactions: 4 · 3 ok · 1 failed breakdown, the worst turn's outcome as the
status, and summed tokens/cost. An LLM layer then phrases the whole session in
one line - keeping the identifying details and the outcome, e.g. "Worked
through Acme Corp's onboarding - integration is live, handed back to their
team." - using the same cheap model as --summarize (install a provider extra such as
agent-panorama[gemini] and set its API key; without one, a deterministic
summary line is shown instead). Override the model with
serve --summarize-model .... Batch reports (generate) aggregate the same
way - Langfuse's native sessionId/userId are picked up automatically.
Runs without a session id stay one-entry-per-run.
Try it without LangChain: start agent-panorama serve --open, then run
python examples/live_demo.py to stream three synthetic runs into the
dashboard. More demos live in examples/, organized by
complexity (one_step/, two_step/, multi_step/) - including a real
LangChain example in examples/one_step/langchain_agent.py.
The activity feed tells you what your agents did. The value layer tells you
whether it mattered - judged against your definition of value, not a
generic rubric. An LLM judge reads each conversation (batch exports and live
mode alike) and produces a ValueJudgment: scores 0-10, the outcome in your
domain language, the concrete moments value was delivered or lost, actionable
fixes, and a pass/fail verdict per success criterion.
Enable it by adding a value: block to your YAML config (no new install - it
uses the same provider extra and API key as --summarize):
value:
  judge_model: google_genai:gemini-2.5-flash   # default; any init_chat_model id
  max_judgments: 50            # hard cap per report - the cost guard
  include_single_runs: true    # false = judge only multi-turn sessions
  default:                     # your definition of value (the generic fallback)
    domain: customer support
    user_goal: resolve the user's issue without human escalation
    success_criteria:
      - issue resolved in the conversation
    custom_dimensions:
      self_service: Did the user finish without needing a human?
  contexts:                    # per-agent overrides, keyed by agent_key
    kb-assistant:
      domain: customer support
      user_goal: the user resolves their issue
A fleet rarely has one goal, so contexts are per agent: each agent's entry
merges field-wise over default. With model_prices also configured, every
agent gets the number managers actually want - cost per valuable
conversation (total spend ÷ conversations scoring ≥ 6).
In the dashboard this appears as a second Value view (it shows up in the sidebar only when something was judged): fleet averages, a per-agent value table, and conversations sorted lowest-value first - because the manager's job is finding lost value. Judged feed cards carry a score pill, and the detail panel shows the full verdict.
Cost notes: each judgment is one capped LLM call (transcript hard-capped at
~8k chars); max_judgments bounds batch reports, and live mode caches one
judgment per conversation, re-judging only when a new turn arrives. Every call
is audited to llm_calls.log. Without a provider/key, judging degrades
silently - the report still generates, just unjudged.
Managers don't have to hand-write the value: block. The live dashboard has a
Value Ontology section that builds it with them:
Definitions are saved by agent-panorama serve to a sidecar in --data-dir and
override the YAML value: block, so the judge re-maps and re-judges with the
manager's own words.
agent-panorama starts as a report generator and is growing into an oversight
layer for fleets of agents - a single pane of glass for everything your agents
did, decided, and got wrong. More than logs, across more than one agent.
✅ v0.1 - Read one run clearly (today)
✅ v0.2 - See the whole fleet (the panorama view)
A unified cross-agent activity feed - one scannable timeline of what every agent did, in plain English:
Agent Activity - May 28, 14:30-15:00

research-assistant    → searched the web, summarized 3 papers            ✓ success
scheduling-assistant  → checked the calendar, handed the task to a human ⤴ escalated
weather-assistant     → looked up the weather (retried once), emailed it ✓ success
billing-agent         → issued 2 refunds, flagged 1 for review           ⚠ anomaly
Aggregate many traces into one report (by session, time window, or file glob)
Per-agent rollups: runs, actions, success / escalation / retry rates
Cross-agent decision log spanning every agent in the window
✅ v0.3 - Continuous oversight: the live dashboard
PanoramaCallbackHandler)agent-panorama serve - a local server with the dashboard bundled in✅ v0.4 - The value layer: was it worth it?
📈 v0.5 - Trends & regressions
🔌 v0.6 - More frameworks & sources
🎯 The vision - Full continuous oversight
Have a use case or a trace format you want supported? Open an issue.
uv pip install -e ".[dev]"
python tests/run_all_tests.py     # run the full suite
ruff check . && ruff format --check .
Contributions are very welcome - and kept deliberately easy. No CLA, no strict process, no style police. If you use agents and want better reports, jump in.
Good first things to do:
parsers/__init__.py - write parse(payload) -> list[AgentRun] and register it;
nothing downstream changes).The whole flow:
ruff check . && ruff format . and python tests/run_all_tests.py
(a green suite is all that's expected - add a test if it makes sense, but don't sweat it).Questions, ideas, half-finished patches: all welcome. Star the repo, open an issue, or just say hi. 🙌
MIT - see LICENSE.
Download counts and popularity will appear here as the collector receives them.
| Version | Published | Direct dependencies | Open version |
|---|---|---|---|
| 0.4.2 | 14 Jun 2026 | 16 |
This describes our collected data; it is not a security assessment.
Observed since 20 Oct, 22:50 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
package:63b05b395349d752169d879f0b9e6266495082ba7372249ff12d5bdb6b074557