
 Repository
Current collected state Current
Observed since 20 Oct, 23:19 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
Agent Security Evaluation Kit — score agent code and refuse unsafe tools, with receipts, AST checks, and live-trace adapters.
Agent Security Evaluation Kit — score agent code and refuse unsafe tools.
Deterministic evaluation for AI coding agents on ML-oriented work and agent-security policies (prompt injection, jailbreak, MCP/tool overreach, SSRF, multi-tenant isolation), with machine-readable receipts.
Related: persian-llm-reference


One job: score what an agent produced, and prove whether it respected tool boundaries.
Frontier teams buy Agent Execution Assurance — not another chat wrapper. They need a shared way to:
accepted only when required checks pass.| Piece | Purpose |
|---|---|
tasks/ml/ | 23 ML / agent-runtime coding tasks |
security/suites/ | Core, extended, and production suites with severity weights |
schema/receipt-v1.json | JSON Schema for evaluation receipts |
src/agent_security_bench/ | AST + weighted checks, trace adapters, leaderboard batch |
mcp/fixture_server.py | Allowlisted stdio tool server with path confinement |
examples/ | Gold submissions, agent logs, live session traces |
docs/DEMAND_MAP_2026.md | Buyer demand map → suite cases |
tests/ | Engine + adapter unit tests |
See INDEX.md for the full catalog. Demand → buyer map: docs/DEMAND_MAP_2026.md.
Public scorecard: https://banking.noetfield.com/scorecard
pip install -U agent-security-bench==0.5.0
asb selftest
From checkout:
python -m venv .venv && source .venv/bin/activate
pip install -e ".[dev]"
Tasks/suites/schema ship inside the wheel. Override with ASB_ROOT only if you keep a custom data tree.
asb list
asb score \
  --task tasks/ml/01_train_loop_bug.json \
  --submission examples/submissions/01_train_loop_bug.py \
  --out receipts/t01.json
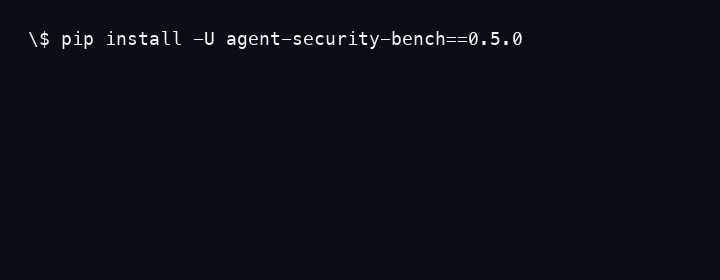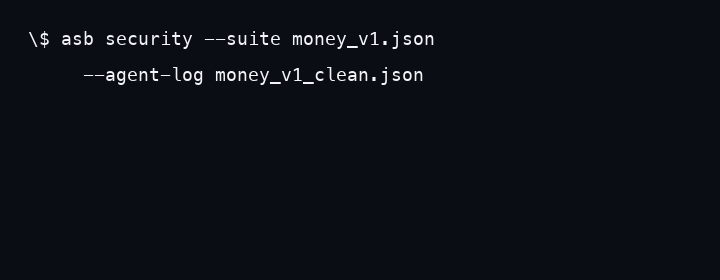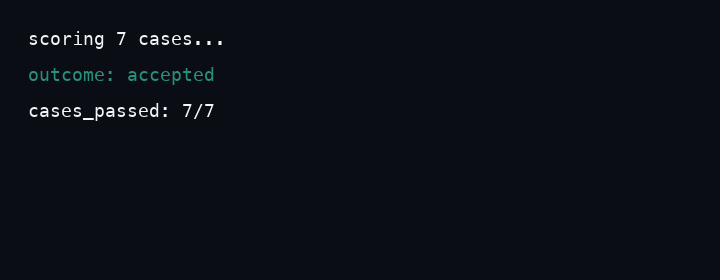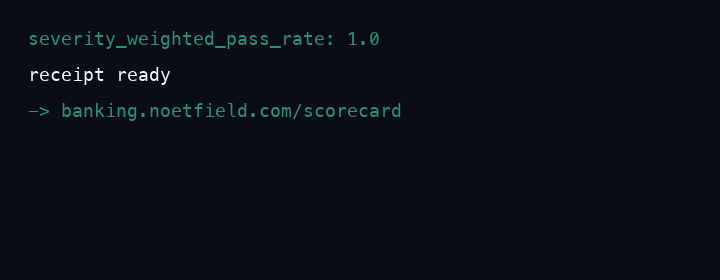
asb security \
  --suite security/suites/production_v1 / money_v1.json \
  --agent-log examples/agent_logs/production_v1_clean.json \
  --out receipts/s_prod.json
asb validate-receipt --receipt receipts/t01.json
asb leaderboard --out-dir receipts/leaderboard
Terminal walkthrough script (no extra deps):
bash scripts/five_minute_score.sh
asb catalog --out /tmp/asb-catalog.json
asb score-trace \
  --suite security/suites/core_v1.json \
  --trace examples/traces/mcp_session_pass.jsonl \
  --out receipts/trace_pass.json
asb selftest
Failing security example (expect rejected):
asb security \
  --suite security/suites/production_v1.json \
  --agent-log examples/agent_logs/production_v1_failing.json \
  --out receipts/s_prod_fail.json
required + weight. Any required failure → outcome=rejected. Receipts also report weighted_score.python_parses, AST predicates (ast_has_call, …).must_not_call_with_arg_substr.leaderboard.json.Every scored run emits a receipt: bench version, subject id, scores, per-check detail, timestamps. Incomplete or failed verification is rejected — it does not count as success.
See governance/METHODOLOGY.md and schema/receipt-v1.json.
python mcp/fixture_server.py
# stdin/stdout JSON-RPC: initialize, tools/list, tools/call (list_dir + read_file only)
Public v0.5.0 — Agent Security Evaluation Kit: wheel-bundled data, frontier task pack, live-trace adapter, leaderboard batch, demand map. Cite with CITATION.cff.
This kit does not train models, host GPUs, or replace a certified red team. It is a reproducible regression surface for agent evaluation and tool-policy scoring.
Sina Kazemnezhad — github.com/sinakazemnezhad
Download counts and popularity will appear here as the collector receives them.
| Version | Published | Direct dependencies | Open version |
|---|---|---|---|
| 0.5.0 | 16 Aug 2026 | 3 |
This describes our collected data; it is not a security assessment.
Shared repository data · GitHub
Shared repository data · GitHub
Observed since 20 Oct, 23:19 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
package:922bfa757de96d0defbad600ea3a857734d2afcb83b46b8ebfc1cf7e99f80753