
 Repository
Current collected state Current
Observed since 20 Oct, 21:58 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
Fork your LLM agent at any step and sweep prompts, models or tool results to find what fixes it.

Fork your LLM agent at any step, then sweep prompts, models or tool results to find what actually fixes it.
Watch the 90-second narrated demo
When an agent misbehaves at step 3, the usual loop is: tweak the prompt, re-run everything, eyeball one output, repeat. That is slow, costs tokens on steps that didn't change, and one lucky run proves nothing. agentfork records every LLM and tool call, replays earlier steps from cache, and runs many variants of one step, several times each, so you get pass rates instead of anecdotes.
Everything runs locally. No account, no server, no data leaves your machine.
A refund agent reads "amount": 4999, "currency": "USD" from an order API. The amount is in cents, and the agent refunds $4,999 for a $49.99 laptop (examples/refund_agent_cents.py). Is the fix a better model or a better prompt?
$ agentfork sweep 543da612 --step 3 --repeat 3 --expect "49.99" --model gpt-4o-mini,gpt-4o
Estimated cost: about $0.0050

  variant             ok    pass   tokens   time      cost   sample output
  original            1/1   0/1       446   1.7s   $0.0001   I have processed a refund of $4,999.00...
  model=gpt-4o-mini   3/3   0/3       446   1.4s   $0.0001   I have processed a refund of $4,999.00...
  model=gpt-4o        3/3   0/3       394   1.2s   $0.0015   The full amount of $4,999.00 for order A123...
A bigger model costs 15x more per run and doesn't fix it. One sentence in the prompt does:
$ agentfork sweep 543da612 --step 3 --repeat 3 --expect "49.99" \
    --system "You are a support agent. Look up the order, then refund the full order amount in USD." \
    --system "... Order amounts from the API are in cents; divide by 100 before refunding."
Estimated cost: about $0.0006

  variant     ok    pass   tokens   time      cost   sample output
  original    1/1   0/1       446   1.7s   $0.0001   I have processed a refund of $4,999.00...
  system #1   3/3   0/3       445   1.2s   $0.0001   I've successfully refunded you $4,999.00...
  system #2   3/3   3/3       457   1.2s   $0.0001   I have processed a refund of $49.99...
Steps 1 and 2 replayed from cache in every run, so only the step that mattered was paid for, and the runs went 4 at a time.
pip install "agentfork-cli[openai]" # or agentfork-cli[anthropic]
Add three things to your agent:
from openai import OpenAI
from agentfork import trace, tool, wrap_openai

client = wrap_openai(OpenAI())      # records every LLM call (wrap_anthropic for Claude)

@tool                               # records every tool call
def lookup_order(order_id): ...

@trace                              # one run = one call of your agent
def run_agent(question): ...
Run your agent as usual. Each run is saved to .agentfork/traces.db.
Wrap the chat model and put @agentfork.tool under LangChain's @tool. Forks and sweeps then work on the graph like on any other agent (examples/langgraph_refund_agent.py):
import agentfork
from langchain_core.tools import tool
from langchain_openai import ChatOpenAI
from langgraph.prebuilt import create_react_agent

llm = agentfork.wrap_langchain(ChatOpenAI(model="gpt-4o-mini"))   # or ChatAnthropic

@tool
@agentfork.tool
def lookup_order(order_id: str) -> str:
    """Look up an order by id."""
    ...

graph = create_react_agent(llm, [lookup_order])

@agentfork.trace
def run_agent(question):
    return graph.invoke({"messages": [("user", question)]})["messages"][-1].content
Streaming models (streaming=True) and the OpenAI Responses API aren't recorded yet.
| Command | What it does |
|---|---|
agentfork list | Recent runs with steps, tokens, duration and fork lineage |
agentfork show <id> [--full] | A run as a step tree, with optional full JSON |
agentfork fork <id> --step N --output/--model/--system ... | Re-run from step N with one change; earlier steps come from cache |
agentfork sweep <id> --step N --model a,b --system ... --repeat K --expect TEXT [--parallel P] | Try many variants of step N, K times each, P at a time (default 4), and compare pass rate, tokens, time and cost |
agentfork sweep <id> <id> ... --step N ... or --last N | Test the same variants across several recorded runs, to check a fix holds for every input |
agentfork diff <a> <b> | Compare two runs step by step |
agentfork save-test <id> | Save a run as a pytest test that replays from cache in CI with no API key |
agentfork ui [--port N] | Open the local web UI to browse, fork, sweep and compare runs |
One run passing proves the fix works for one input. To check it holds for others, record a few runs with different inputs and sweep them together. A plain --expect string can't work when each input has a different right answer, so pass a check function instead:
# examples/checks.py
def refund_matches_order(output, run):
    """Pass if the agent refunded the order amount, converted from cents to dollars."""
    order = json.loads([s for s in run["steps"] if s["name"] == "lookup_order"][-1]["output"])
    refund = [s for s in run["steps"] if s["name"] == "issue_refund"][-1]
    return abs(refund["input"]["kwargs"]["amount_usd"] - order["amount"] / 100) < 0.005
$ agentfork sweep --last 3 --step 3 --repeat 2 --check examples/checks.py:refund_matches_order \
    --system "You are a support agent. ..." --system "... Order amounts from the API are in cents; ..."

  variant     ab6e7c4a   578da5ae   31eb9611   total
  original    0/1        1/1        0/1        1/3
  system #1   0/2        2/2        0/2        2/6
  system #2   2/2        2/2        2/2        6/6

ab6e7c4a: Please refund order C789, the keys stick.
578da5ae: Order B456 never worked. I want my money back.
31eb9611: My headphones from order A123 arrived broken. Please refund me.
The original prompt gets order B456 right by luck, so testing only that input would hide the bug. The fix passes for all three.
A check gets the final output and the run: its input and every step's type, name, input and output, so it can look at tool calls instead of the reply's wording. --expect TEXT and --expect-regex PATTERN cover the simple cases, and you can combine them; a run passes only if every check does.
Prefer clicking to typing? The same fork, sweep and diff are available in a local web UI.
pip install "agentfork-cli[openai,ui]"
agentfork ui        # opens http://127.0.0.1:8000
Start it from the folder you ran your agent in, since runs are saved to .agentfork/ there. The server only listens on your own machine.
Find the step that went wrong. Pick a run on the left. Its timeline shows each LLM and tool call in plain words, such as Decided to call issue_refund(amount_usd=4999). Click a step to see its full input and output.
Try a change. On that step, use another model, edit the system prompt, or fake a tool's result. Earlier steps replay from cache, and the new run appears under the original.
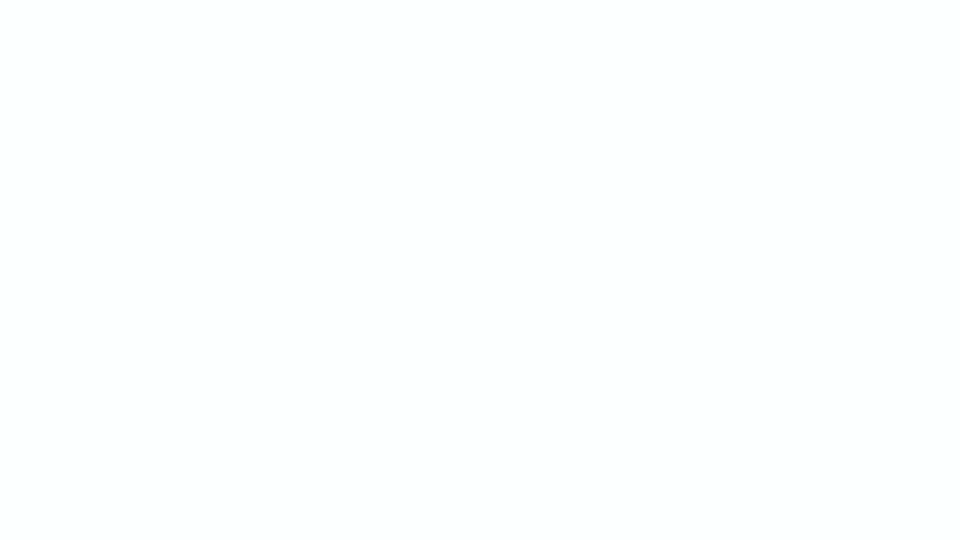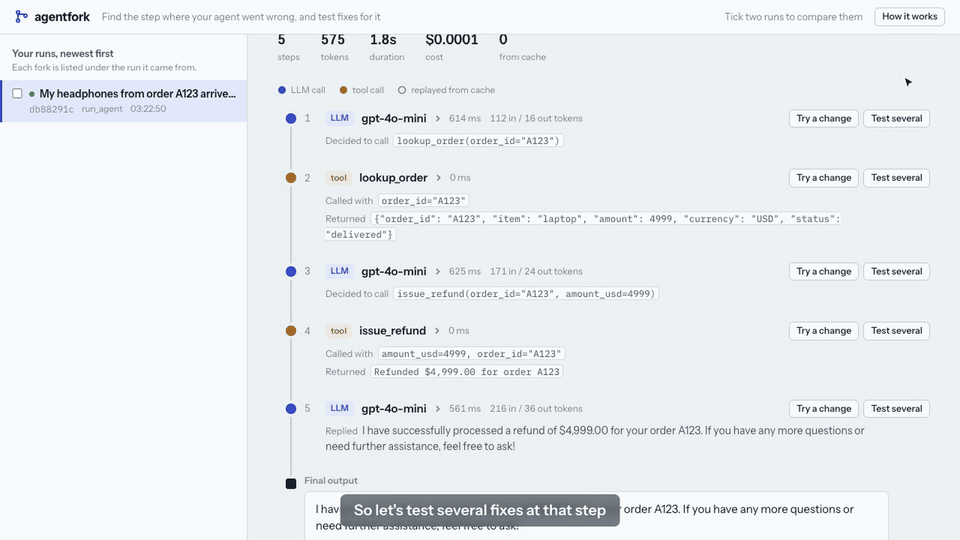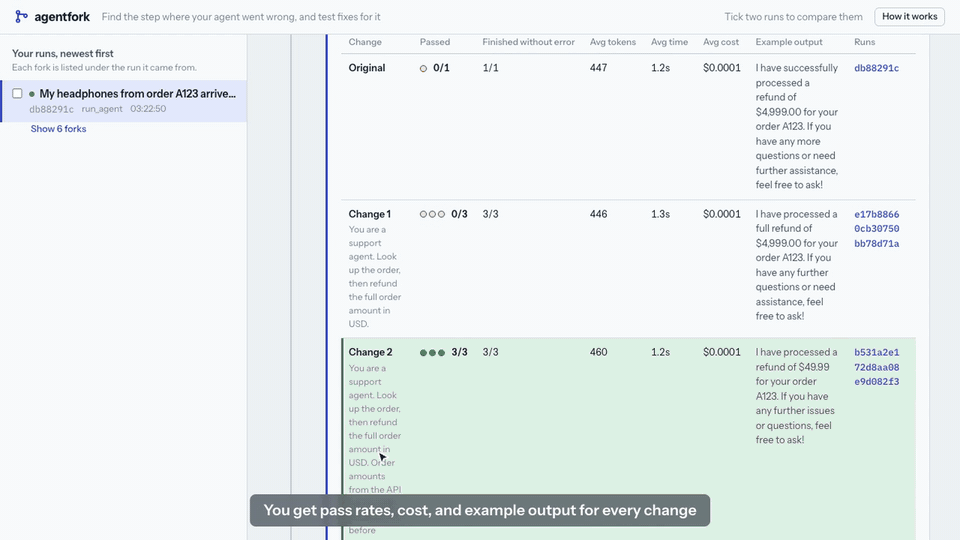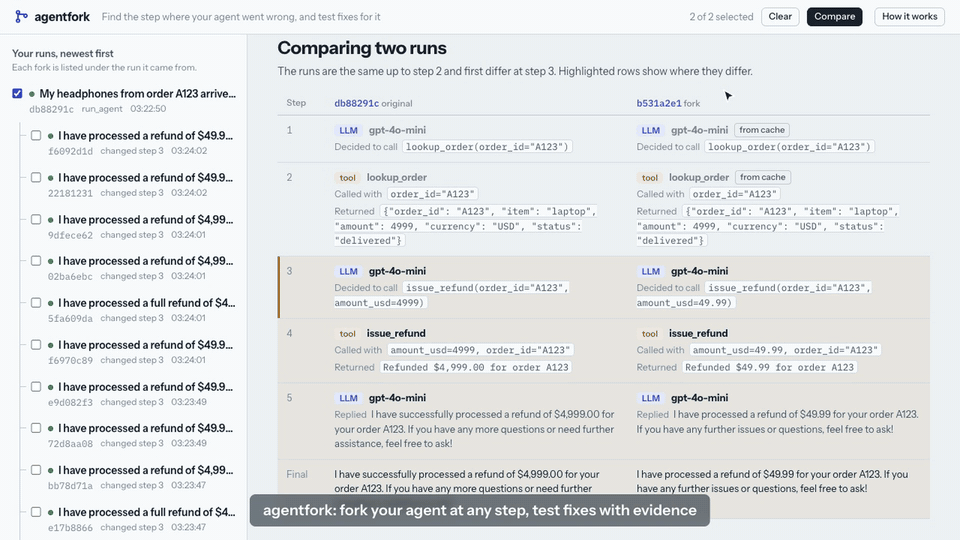
Test several. Enter a few changes, how many times to run each, and text the final output must contain. You get a pass rate per change, with the original run as the baseline:
Change      Passed   Example output
Original    ○ 0/1    I have processed a refund of $4,999.00...
Change 1    ●●● 3/3  I have processed a refund of $49.99...
Change 2    ○○○ 0/3  I have processed a refund of $4,999.00...
Compare. Tick two runs to see them side by side, with the first step where they differ highlighted.
@trace, @tool and wrap_openai/wrap_anthropic/wrap_langchain capture each step's inputs, outputs, tokens and latency, plus a hash of its inputs.--repeat times, --parallel at a time, and checks each final output for your --expect text. Before it starts, it estimates the cost from the tokens the original run used from step N on, priced per model.save-test writes a JSON snapshot plus a pytest file. The test replays every step from cache and fails with a diff if any step's inputs, the step count, or the final output changes.Costs use list prices per model for OpenAI and Anthropic, built into pricing.py. Prices change, and a model without a price shows -. To add or correct one, put USD per 1M input and output tokens in .agentfork/prices.json:
{"gpt-4o-mini": [0.15, 0.60], "my-finetune": [3.0, 12.0]}
agentfork overlaps with record/replay tools like agent-rewind, which supports many more providers, and agentstep, a LangGraph time-travel debugger with a web UI. agentfork's focus is the step after replay: sweeping many variants of one step, with repeats and pass rates, to choose a fix with evidence.
MIT
Download counts and popularity will appear here as the collector receives them.
| Version | Published | Direct dependencies | Open version |
|---|---|---|---|
| 0.4.0 | 18 Oct 2026 | 10 |
This describes our collected data; it is not a security assessment.
Observed since 20 Oct, 21:58 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
package:0b2256a06f234f23d55b2653af57b074e423c7d6cde657a1f9c2acc094a801a2