
 Repository
Current collected state Current
Observed since 20 Oct, 22:09 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
Independent, auditable verification for coding-agent claims
A verification layer for coding agents. It reruns what an agent claims and accepts only the results it can prove.
AgentHarness verifies run claims, reexecutes allowed test commands, scores held-out tasks, and separates genuine solution failure from invalid measurement.




|
2 core commands |
4 verdicts |
1 trust boundary |
0 blind trust |
Proves, not reportsIf an agent says tests passed, AgentHarness tries to prove it with controlled reexecution instead of trusting narration. |
Scores the real taskHeld-out evaluation stays separate from the claims the agent sees, so the benchmark measures outcome, not prompt gaming. |
Keeps failure honestIt distinguishes a bad solution from a broken measuring instrument, so invalid grading does not become fake rigor. |
English | Italiano (vai alla versione italiana)
Coding agents report success. They say the tests passed, the scope was respected, the artifact was produced. If you merge on that word alone, a fabricated green run becomes a production bug.
AgentHarness does not trust the report. It reruns the claim, captures what actually happened, and returns a verdict backed by evidence.
It also refuses the opposite mistake. A broken sandbox, missing dependency, or grader fault is a problem of the measurement layer, not of the solution. AgentHarness keeps that boundary explicit so a low score still means something.
AgentHarness does not run agents. It verifies what they claim to have done. It is model-agnostic and agent-agnostic.
git clone https://github.com/fabioscialanga/AgentHarness.git
cd AgentHarness
python3 -m venv .venv && . .venv/bin/activate
pip install -e .

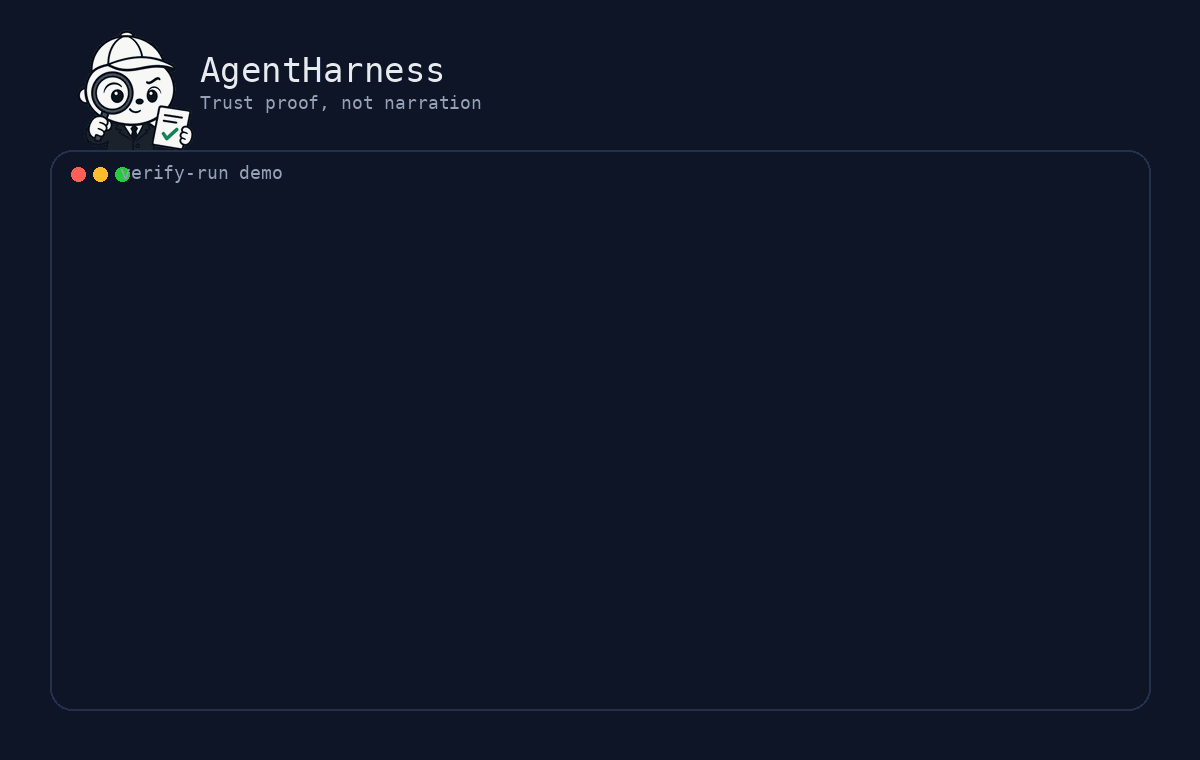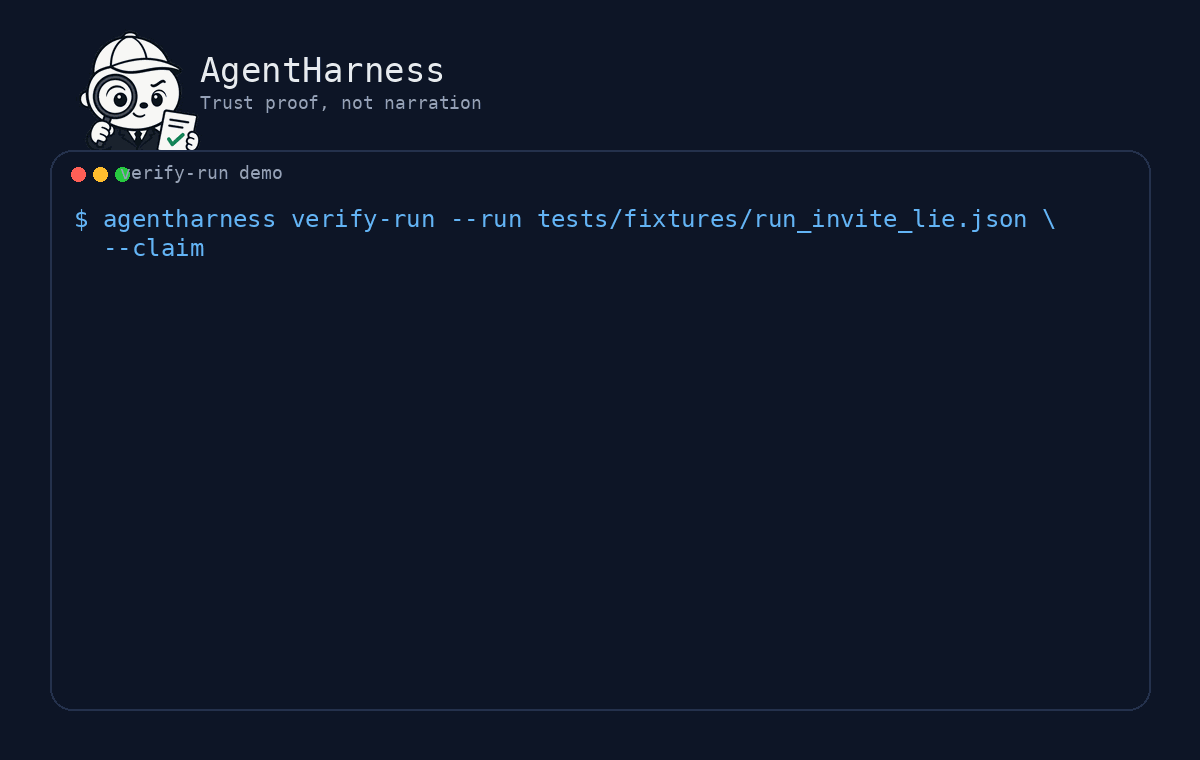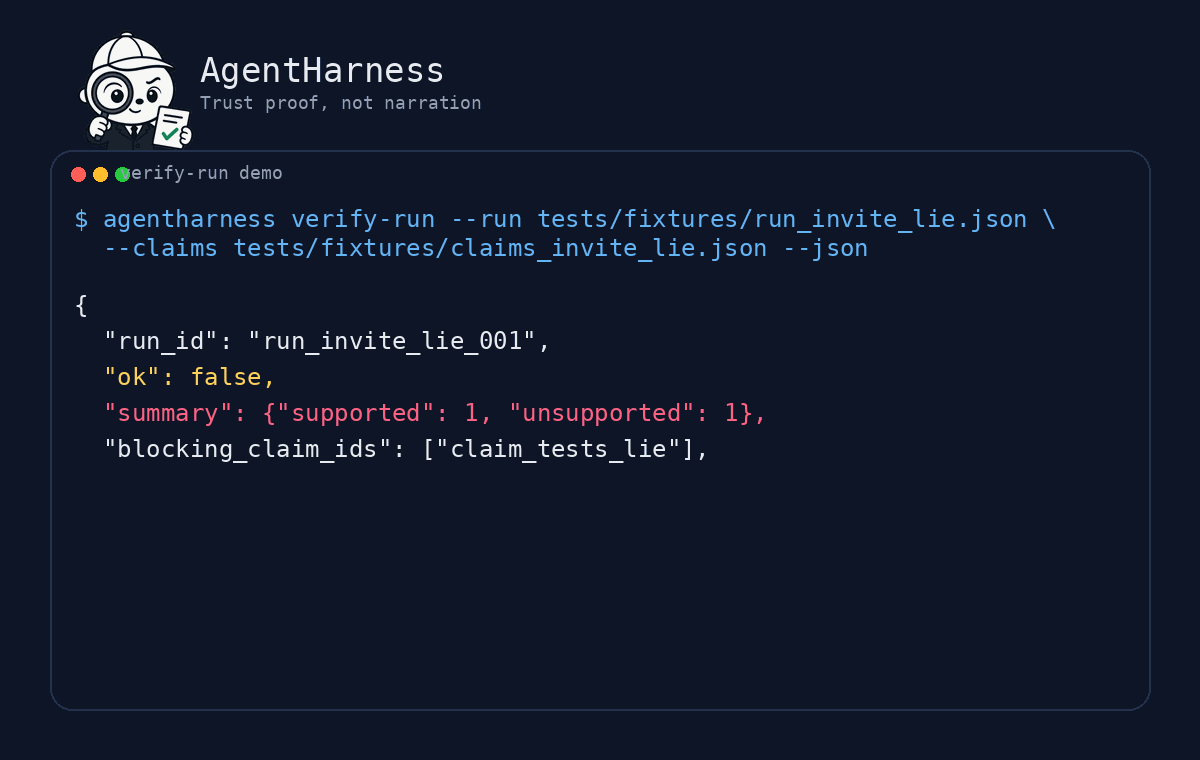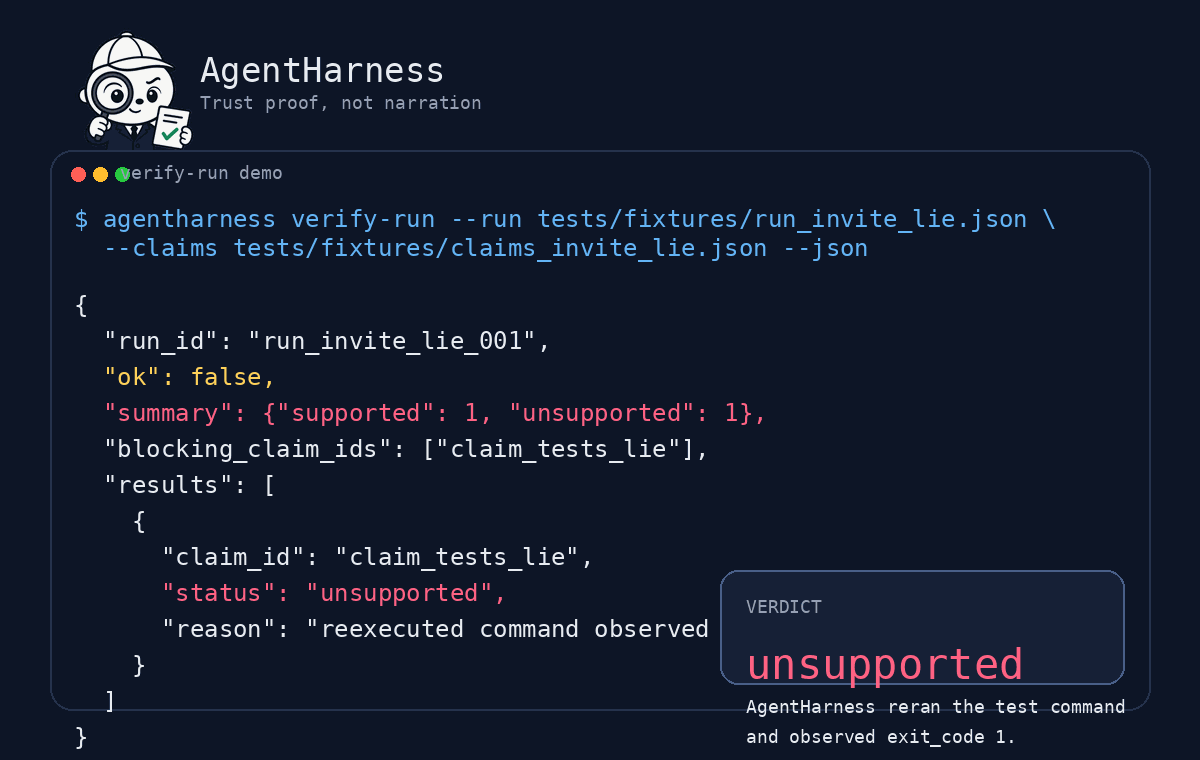
# a run whose agent declared a green pytest suite it did not actually pass
agentharness verify-run \
  --run tests/fixtures/run_invite_lie.json \
  --claims tests/fixtures/claims_invite_lie.json \
  --json
This case is designed to fail. The run record declares exit code 0, but AgentHarness reruns the allowed command, captures the real non-zero exit code under .agentharness/evidence/<run_id>/reexecuted/, and returns unsupported.
The success does not survive because the proof does not come from the agent's narration. It comes from controlled reexecution.
To see the clean path:
agentharness verify-run \
  --run tests/fixtures/run_invite_schema_success.json \
  --claims tests/fixtures/claims_invite_schema.json \
  --json
A raw model is not enough. Reliable agentic engineering needs a harness around it: context, rules, verification, evidence, and a clear boundary between a real failure and an invalid measurement. AgentHarness is that harness, focused on the verification end.
What it is:
What it is not:
AgentHarness sits downstream. The agent has already done the work, or claims to have done it. AgentHarness answers the trust question.
verify-run never guesses. Every claim resolves to one of:
| Verdict | Meaning |
|---|---|
supported | The claim is backed by reexecuted or coherent evidence. |
unsupported | Evidence exists and contradicts what the agent declared. |
inconclusive | Truth cannot be defended, so it is not claimed. |
invalid | The envelope is malformed or the harness itself failed. |
That last row is central. AgentHarness separates real_failure, a genuine fault of the work, from harness_invalid, a fault of the measuring instrument. A benchmark that cannot tell them apart is measuring itself.
Requirements: Python 3.11+ and git.
Install the current alpha from PyPI in the target project's virtual environment:
python3 -m venv .venv && . .venv/bin/activate
python -m pip install --upgrade pip
python -m pip install agentharness-verifier==0.1.0
agentharness --help
The PyPI distribution is named agentharness-verifier; the installed Python package and CLI remain agentharness. Contributors can use an editable source checkout:
git clone https://github.com/fabioscialanga/AgentHarness.git
cd AgentHarness
python3 -m venv .venv && . .venv/bin/activate
python -m pip install --upgrade pip
python -m pip install -e .
python -m pytest -q
See CONTRIBUTING.md for the contribution workflow and SECURITY.md before running untrusted code.
agentharness checkThis is the shortest path from an agent claim to independently reexecuted evidence:
agentharness check \
  --workspace . \
  --command "python -m pytest -q" \
  --json
check snapshots the workspace under .agentharness/runs/<run-id>/workspace, creates the run and claims envelopes, reexecutes the allowed pytest command in that persistent copy, and writes the evidence and verification report. The command never runs in the original workspace.
The current workspace-copy executor is mutation isolation, not a security sandbox. It does not block network access or isolate the rest of the host filesystem, and the JSON report says so explicitly.
Use repeated --allowed-path and --forbidden-path options when changed-file scope is also part of the claim.
agentharness verify-runThis is the lower-level, integration-friendly primitive.
It verifies an agent run against explicit claims and accepts a claim only when controlled proof can defend it.
What it does:
pytest, python -m pytest, and uv run pytestinconclusive when truth cannot be defended.agentharness/evidence/<run_id>/ namespaceIf the agent says a test suite passed, AgentHarness does not treat that as proof. It tries to prove it.
agentharness evaluate runs deterministic held-out suites against a run and its workspace. It produces a continuous task score from independent acceptance checks.agentharness verify checks a project against its contract, checks semantic consistency between AGENTS.md and project.yaml, and detects drift in checked-in .framework artifacts.agentharness run-plan executes a retry-aware plan with explicit fallbacks and records attempts, outputs, and winner selection as an audit trail.agentharness validate confirms a project is internally consistent before anything runs.agentharness generate regenerates deterministic .framework governance artifacts from project.yaml.agentharness bootstrap creates a new contract-first project skeleton and validates it.# validate, generate, and verify the worked example
agentharness validate examples/civictrack --json
agentharness generate examples/civictrack --json
agentharness verify examples/civictrack --json
# deterministic held-out evaluation
agentharness evaluate \
--run examples/cookbooks/evaluation-demo/run.json \
--suite examples/cookbooks/evaluation-demo/suite.json \
--json
# retry and fallback with an audit trail
agentharness run-plan \
--plan examples/cookbooks/retry-fallback-demo/plan.json \
--json
# start a new contract-first project
agentharness bootstrap ./my-project \
--project-name "My Project" \
--project-slug my-project \
--json
Spec-driven frameworks help an agent start well. They turn intent into structure and give the agent rules before execution.
AgentHarness sits later in the chain, where somebody has to decide whether the result is trustworthy. It reruns claims, judges behavior with held-out checks kept separate from what the agent sees, distinguishes a real solution failure from a harness fault, and leaves an auditable evidence trail.
The two layers are complementary. One helps generate the work. This one helps decide whether to trust the outcome.
PROJECT.md: human-readable project intentproject.yaml: structured, machine-readable project configAGENTS.md: agent operating rulesworkflows/, checklists/, policies/: task templates, review rules, testing rules, and guardrails.framework/: generated metadata, risk matrices, required checksA verification project should be the last to overclaim.
Works today:
real_failure and harness_invalid taxonomyNot yet:
workspace-copy keeps ordinary relative command writes in the snapshot but is not yet a network/filesystem security sandboxdocs/en/QUICKSTART.mddocs/en/GITHUB_ACTIONS.mddocs/en/RELEASING.mddocs/en/PROJECT_DOCUMENTATION.mddocs/en/VALIDATOR.mddocs/en/BOOTSTRAP.mddocs/en/AB_BENCHMARK.mddocs/en/EXAMPLE_CIVICTRACK.mdUno strato di verifica per agenti di coding. Riesegue cio che un agente dichiara e accetta solo i risultati che puo dimostrare.
Gli agenti di coding dichiarano successo. Dicono che i test passano, che lo scope e stato rispettato, che l'artefatto e stato prodotto. Se si fonde sulla sola parola, un falso verde diventa un bug in produzione.
AgentHarness non si fida del report. Riesegue il claim, cattura cio che e successo davvero e restituisce un verdetto sostenuto dall'evidenza.
Rifiuta anche l'errore opposto. Una sandbox rotta, una dipendenza mancante o un guasto del grader sono problemi dello strumento di misura, non della soluzione. AgentHarness mantiene questo confine esplicito, cosi un punteggio basso continua a significare qualcosa.
AgentHarness non esegue agenti. Verifica cio che dichiarano di aver fatto. E indipendente dal modello e dall'agente.
git clone https://github.com/fabioscialanga/AgentHarness.git
cd AgentHarness
python3 -m venv .venv && . .venv/bin/activate
pip install -e .

agentharness verify-run \
  --run tests/fixtures/run_invite_lie.json \
  --claims tests/fixtures/claims_invite_lie.json \
  --json
Questo caso e costruito per fallire. Il run record dichiara exit code 0, ma AgentHarness riesegue il comando consentito, cattura il vero exit code diverso da zero sotto .agentharness/evidence/<run_id>/reexecuted/ e restituisce unsupported.
Il successo non regge perche la prova non arriva dal racconto dell'agente. Arriva dalla riesecuzione controllata.
Per vedere il percorso pulito:
agentharness verify-run \
  --run tests/fixtures/run_invite_schema_success.json \
  --claims tests/fixtures/claims_invite_schema.json \
  --json
Un modello grezzo non basta. L'ingegneria agentica affidabile richiede un harness intorno: contesto, regole, verifica, evidenza e un confine chiaro tra fallimento reale e misura invalida. AgentHarness e quel layer, concentrato sul lato verifica.
Cosa e:
Cosa non e:
AgentHarness sta a valle. L'agente ha gia fatto il lavoro, o sostiene di averlo fatto. AgentHarness risponde alla domanda sulla fiducia.
verify-run non indovina. Ogni claim finisce in una di queste categorie:
| Verdetto | Significato |
|---|---|
supported | Il claim e sostenuto da evidenza rieseguita o coerente. |
unsupported | L'evidenza esiste e contraddice cio che l'agente ha dichiarato. |
inconclusive | La verita non e difendibile, quindi non viene dichiarata. |
invalid | L'envelope e malformato oppure ha fallito l'harness. |
L'ultima riga e il centro del progetto. AgentHarness separa real_failure, un guasto vero del lavoro, da harness_invalid, un guasto dello strumento di misura. Un benchmark che non sa distinguerli sta misurando se stesso.
Requisiti: Python 3.11+ e git.
Installa l'alpha corrente da PyPI nell'ambiente virtuale del progetto da verificare:
python3 -m venv .venv && . .venv/bin/activate
python -m pip install --upgrade pip
python -m pip install agentharness-verifier==0.1.0
agentharness --help
La distribuzione PyPI si chiama agentharness-verifier; il package Python e la CLI installati restano agentharness. Chi contribuisce puo usare un checkout editable:
git clone https://github.com/fabioscialanga/AgentHarness.git
cd AgentHarness
python3 -m venv .venv && . .venv/bin/activate
python -m pip install --upgrade pip
python -m pip install -e .
python -m pytest -q
Consulta CONTRIBUTING.md per il workflow di contribuzione e SECURITY.md prima di eseguire codice non fidato.
agentharness checkQuesto e il percorso piu breve dalla dichiarazione dell'agente a una prova rieseguita in modo indipendente:
agentharness check \
  --workspace . \
  --command "python -m pytest -q" \
  --json
check crea uno snapshot sotto .agentharness/runs/<run-id>/workspace, genera automaticamente gli envelope run e claims, riesegue il comando pytest consentito nella copia persistente e scrive evidenze e report. Il comando non viene eseguito nel workspace originale.
L'executor attuale workspace-copy isola le modifiche, ma non e un security sandbox: non blocca la rete e non isola il resto del filesystem host. Il report JSON lo dichiara esplicitamente.
Le opzioni ripetibili --allowed-path e --forbidden-path aggiungono anche la verifica dello scope dei file modificati.
agentharness verify-runE la primitive di livello inferiore per integrazioni ed envelope espliciti.
Verifica una run rispetto a claim espliciti e accetta un claim solo quando una prova controllata puo sostenerlo.
Cosa fa:
pytest, python -m pytest e uv run pytestinconclusive quando la verita non e difendibile.agentharness/evidence/<run_id>/Se l'agente dichiara che una suite e verde, AgentHarness non lo tratta come prova. Prova a dimostrarlo.
agentharness evaluate esegue suite held-out deterministiche contro una run e il suo workspace. Produce uno score continuo da controlli di accettazione indipendenti.agentharness verify controlla un progetto rispetto al contratto, controlla la coerenza semantica tra AGENTS.md e project.yaml e rileva drift negli artefatti .framework versionati.agentharness run-plan esegue un piano con retry e fallback espliciti e registra tentativi, output e selezione del vincitore come audit trail.agentharness validate conferma che un progetto sia internamente coerente prima di eseguire altro.agentharness generate rigenera gli artefatti .framework deterministici a partire da project.yaml.agentharness bootstrap crea un nuovo skeleton contract-first e lo valida.agentharness validate examples/civictrack --json
agentharness generate examples/civictrack --json
agentharness verify examples/civictrack --json
agentharness evaluate \
--run examples/cookbooks/evaluation-demo/run.json \
--suite examples/cookbooks/evaluation-demo/suite.json \
--json
agentharness run-plan \
--plan examples/cookbooks/retry-fallback-demo/plan.json \
--json
agentharness bootstrap ./my-project \
--project-name "My Project" \
--project-slug my-project \
--json
I framework spec-driven aiutano l'agente a partire bene. Trasformano l'intento in struttura e forniscono regole prima dell'esecuzione.
AgentHarness sta piu avanti nella catena, nel punto in cui qualcuno deve decidere se il risultato e affidabile. Riesegue i claim, giudica il comportamento con controlli held-out separati da cio che l'agente vede, distingue tra fallimento reale della soluzione e guasto dell'harness, e lascia una traccia di evidenza auditabile.
I due layer sono complementari. Uno aiuta a generare il lavoro. Questo aiuta a decidere se fidarsi del risultato.
PROJECT.md: intento del progetto leggibile da umaniproject.yaml: configurazione strutturata e machine-readableAGENTS.md: regole operative per agentiworkflows/, checklists/, policies/: template di task, regole di review, test e guardrail.framework/: metadata generati, matrici di rischio, controlli richiestiUn progetto sulla verifica dovrebbe essere l'ultimo a promettere troppo.
Funziona oggi:
real_failure e harness_invalidNon ancora:
workspace-copy mantiene nella copia le normali scritture relative del comando, ma non e ancora un security sandbox di rete/filesystemdocs/it/QUICKSTART.mddocs/it/INTEGRAZIONE_GITHUB_ACTIONS.mddocs/it/RILASCIO.mddocs/it/DOCUMENTAZIONE_PROGETTO.mddocs/it/VALIDATORE.mddocs/it/BOOTSTRAP.mddocs/it/BENCHMARK_AB.mddocs/it/ESEMPIO_CIVICTRACK.mdpypistats · 47 observations shown. Missing days are unknown. Source category: overall: without mirrors.
| Date / source period | Value | Observed at |
|---|---|---|
| 2026-10-20 – 2026-10-20 | 2 | 2026-10-21T14:30:19.2783495Z |
| 2026-10-18 – 2026-10-18 | 3 | 2026-10-21T14:30:19.2783495Z |
| 2026-10-17 – 2026-10-17 | 7 | 2026-10-21T14:30:19.2783495Z |
| 2026-10-16 – 2026-10-16 | 1 | 2026-10-21T14:30:19.2783495Z |
| 2026-10-15 – 2026-10-15 | 4 | 2026-10-21T14:30:19.2783495Z |
| 2026-10-14 – 2026-10-14 | 2 | 2026-10-21T14:30:19.2783495Z |
| 2026-10-13 – 2026-10-13 | 2 | 2026-10-21T14:30:19.2783495Z |
| 2026-10-12 – 2026-10-12 | 3 | 2026-10-21T14:30:19.2783495Z |
| 2026-10-09 – 2026-10-09 | 2 | 2026-10-21T14:30:19.2783495Z |
| 2026-10-08 – 2026-10-08 | 1 | 2026-10-21T14:30:19.2783495Z |
| 2026-10-06 – 2026-10-06 | 1 | 2026-10-21T14:30:19.2783495Z |
| 2026-10-05 – 2026-10-05 | 1 | 2026-10-21T14:30:19.2783495Z |
| 2026-10-04 – 2026-10-04 | 1 | 2026-10-21T14:30:19.2783495Z |
| 2026-10-02 – 2026-10-02 | 1 | 2026-10-21T14:30:19.2783495Z |
| 2026-09-30 – 2026-09-30 | 1 | 2026-10-21T14:30:19.2783495Z |
| 2026-09-27 – 2026-09-27 | 1 | 2026-10-21T14:30:19.2783495Z |
| 2026-09-26 – 2026-09-26 | 1 | 2026-10-21T14:30:19.2783495Z |
| 2026-09-23 – 2026-09-23 | 2 | 2026-10-21T14:30:19.2783495Z |
| 2026-09-22 – 2026-09-22 | 2 | 2026-10-21T14:30:19.2783495Z |
| 2026-09-20 – 2026-09-20 | 2 | 2026-10-21T14:30:19.2783495Z |
| 2026-09-19 – 2026-09-19 | 4 | 2026-10-21T14:30:19.2783495Z |
| 2026-09-16 – 2026-09-16 | 3 | 2026-10-21T14:30:19.2783495Z |
| 2026-09-14 – 2026-09-14 | 1 | 2026-10-21T14:30:19.2783495Z |
| 2026-09-13 – 2026-09-13 | 2 | 2026-10-21T14:30:19.2783495Z |
| 2026-09-07 – 2026-09-07 | 3 | 2026-10-21T14:30:19.2783495Z |
| 2026-09-06 – 2026-09-06 | 1 | 2026-10-21T14:30:19.2783495Z |
| 2026-09-01 – 2026-09-01 | 3 | 2026-10-21T14:30:19.2783495Z |
| 2026-08-31 – 2026-08-31 | 2 | 2026-10-21T14:30:19.2783495Z |
| 2026-08-28 – 2026-08-28 | 5 | 2026-10-21T14:30:19.2783495Z |
| 2026-08-24 – 2026-08-24 | 9 | 2026-10-21T14:30:19.2783495Z |
| 2026-08-23 – 2026-08-23 | 6 | 2026-10-21T14:30:19.2783495Z |
| 2026-08-17 – 2026-08-17 | 2 | 2026-10-21T14:30:19.2783495Z |
| 2026-08-14 – 2026-08-14 | 5 | 2026-10-21T14:30:19.2783495Z |
| 2026-08-11 – 2026-08-11 | 1 | 2026-10-21T14:30:19.2783495Z |
| 2026-08-09 – 2026-08-09 | 1 | 2026-10-21T14:30:19.2783495Z |
| 2026-08-07 – 2026-08-07 | 1 | 2026-10-21T14:30:19.2783495Z |
| 2026-08-06 – 2026-08-06 | 2 | 2026-10-21T14:30:19.2783495Z |
| 2026-08-04 – 2026-08-04 | 2 | 2026-10-21T14:30:19.2783495Z |
| 2026-08-03 – 2026-08-03 | 1 | 2026-10-21T14:30:19.2783495Z |
| 2026-08-02 – 2026-08-02 | 1 | 2026-10-21T14:30:19.2783495Z |
| 2026-07-30 – 2026-07-30 | 2 | 2026-10-21T14:30:19.2783495Z |
| 2026-07-29 – 2026-07-29 | 2 | 2026-10-21T14:30:19.2783495Z |
| 2026-07-28 – 2026-07-28 | 2 | 2026-10-21T14:30:19.2783495Z |
| 2026-07-27 – 2026-07-27 | 3 | 2026-10-21T14:30:19.2783495Z |
| 2026-07-26 – 2026-07-26 | 1 | 2026-10-21T14:30:19.2783495Z |
| 2026-07-25 – 2026-07-25 | 1 | 2026-10-21T14:30:19.2783495Z |
| 2026-07-23 – 2026-07-23 | 4 | 2026-10-21T14:30:19.2783495Z |
| Version | Published | Direct dependencies | Open version |
|---|---|---|---|
| 0.1.0 | 15 Jul 2026 | 4 |
This describes our collected data; it is not a security assessment.
Shared repository data · GitHub
Observed since 20 Oct, 22:09 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
package:2a4c7d3b3445a7387409551a2030d648ff899a82f870885c98f3916066cf55e1