

 Repository
Current collected state Current
Observed since 21 Oct, 08:55 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
Check a coding agent's claims against the repository before you approve.



When a coding agent says "all tests pass" or "nothing else depends on this", Agentvow checks that against the repository and tells you what it could confirm, what it contradicted, and what it could not check. It runs outside the agent (an agent must not grade itself), uses no LLM, and never approves, rejects or merges anything.
Status: 0.2.1 (prototype). Not a safety verdict. Python repositories; running tests needs macOS or Linux (bubblewrap). See Known limits and docs/SECURITY_MODEL.md.

Recorded from examples/demo_capture.py on the released package: a real virtualenv with pytest, a real commit, a real agentvow capture, a real sandboxed replay and a real changed-line coverage measurement. Staged for the recording, not faked: the pacing and simulated typing of the two commands, the "agent" scene (a pre-made commit stands in for a live agent), and the line wrapping of the report text so it fits the terminal. Note what the report does and does not say: the tests pass and the result reproduces from the captured packages, but nearly half of the changed lines were never run by any test, which is exactly what a person would want to know before trusting "all tests pass".
Name: Agentvow (an agent's claims are vows; this checks them). It was developed under the working name AgentMirror; the name was changed because that name, and its Python module, belong to an unrelated PyPI project.
pip install agentvow                    # from PyPI; or from a checkout: pip install .  (no dependencies; Python 3.10+)
agentvow doctor --repo /path/to/project       # checks your setup and runs the whole hook path end to end
echo "I changed X. All 12 tests pass. Nothing else depends on it." | agentvow check --repo /path/to/project
agentvow check --repo . --transcript msg.txt --run-tests --python venv/bin/python   # also run the tests (sandboxed, macOS/Linux)
agentvow check --repo . --transcript msg.txt --run-tests --changed-coverage           # also say how many changed source lines the tests actually ran
agentvow check --repo . --transcript msg.txt --evidence-pack --html report.html   # receipt + reproducibility (captured vs project setup) + changed-line coverage (docs/EVIDENCE_PACK.md)
agentvow capture --repo . && agentvow check --repo . --transcript msg.txt --run-tests --from-capsule   # replay from the packages captured when the agent ran its tests (docs/CAPSULES.md)
agentvow check --repo . --transcript msg.txt --ci --html report.html                # also read CI results; write a visual report
--recipe recipe.json replays the agent's own declared setup and test command in a clean sandbox (see docs/RECIPES.md).
agentvow audit-env --session <session.jsonl> [--recipe recipe.json] lists what an agent session installed or exported and whether the repository or recipe declares it.
Exit codes: 0 no contradiction found (scoped), 1 review required, 2 insufficient evidence, 3 tool error. Other options: --markdown, --json, --session <Claude Code session.jsonl>, --base <ref>, --test-cmd, --test-timeout, --setup auto, --new-test-failures review.
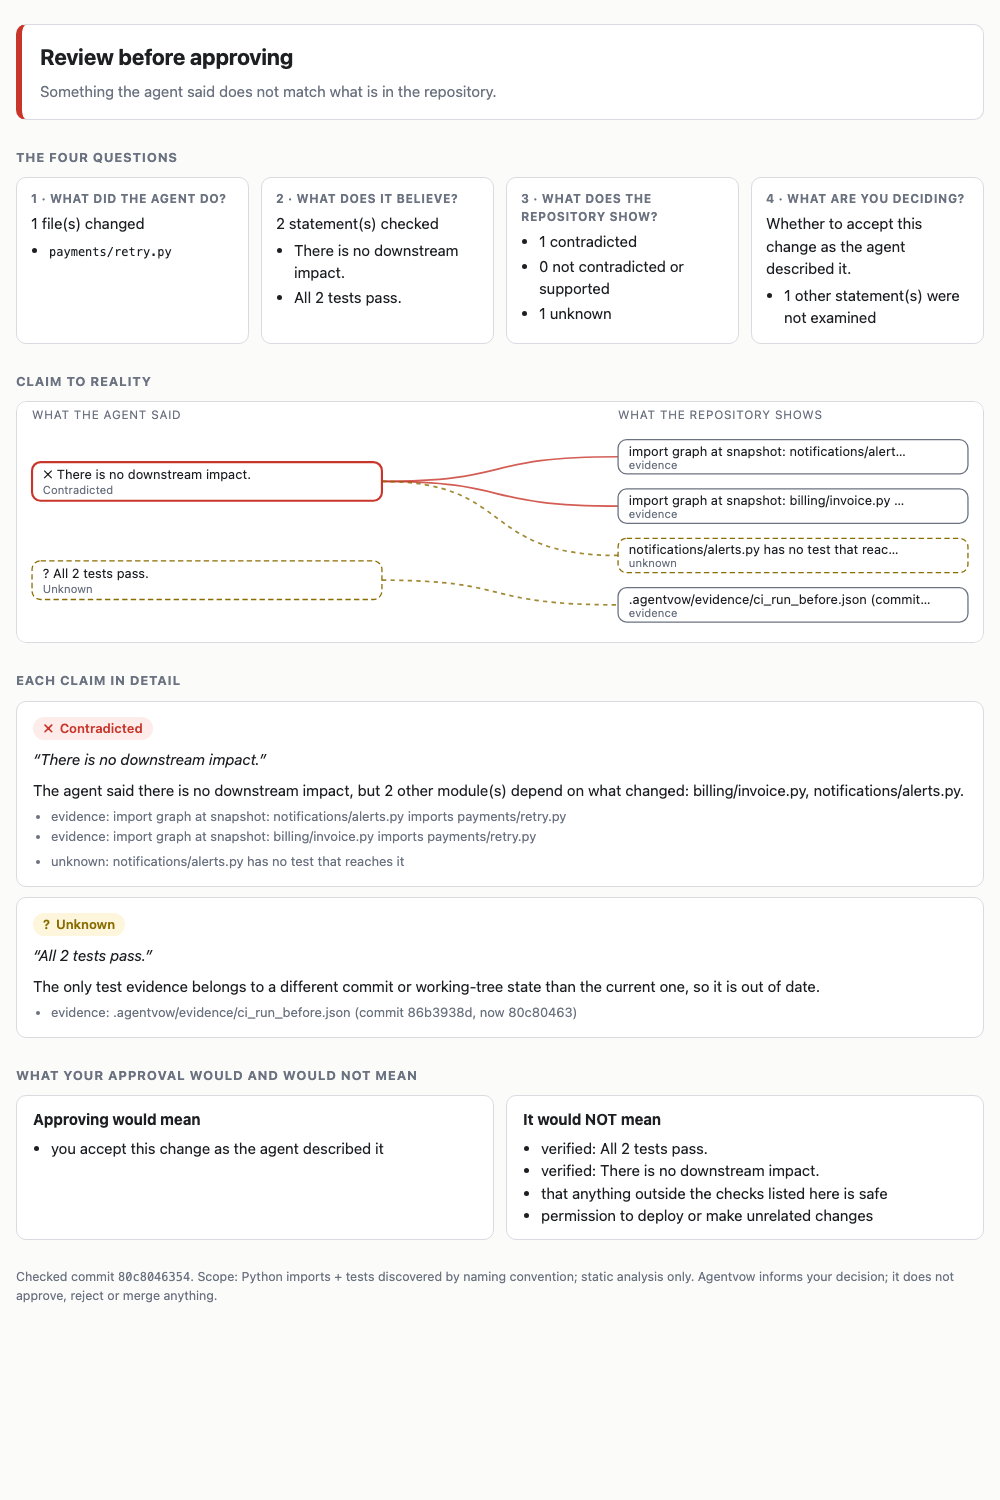
agentvow demo # builds a small demo repo, checks "no downstream impact" against it and writes a sealed result
In VS Code run Agentvow: Try the demo: it shows the red verdict panel and copies a prompt you can paste into Copilot (in the demo folder, with the hook added) to see the same on a real agent turn.
| Claim in the agent's message | How it is checked |
|---|---|
| "tests pass" (with an optional count) | tests run at the base and head states in a sandbox; a regression is a test that passed before and fails now; the claimed count is compared; failures that also occur at base are treated as environmental; deleted/skipped tests and modified existing tests prevent a plain "supported"; CI test jobs for the commit are read with --ci |
| "backward compatible" | static public-API diff of changed Python files (removed or renamed names and parameters, new required parameters, __init__ re-exports) |
| "no downstream impact" | static import graph (src layout aware); deleted modules, dynamic imports and non-Python code make the result UNKNOWN |
Anything else the agent says is listed as unchecked, and the report says how many statements were not examined. UNKNOWN is a real result: missing evidence, a failed collector, an unreadable message or an unfamiliar format never become "OK". The best possible status is NO CONTRADICTION FOUND (scoped, not a safety verdict).
| Where | How | Status |
|---|---|---|
| GitHub Copilot in VS Code (agent chat, Copilot CLI engine) | .github/hooks/agentvow.json (extension command Agentvow: Add the agent hook) | Verified on a real run: Copilot ran the hook, its payload and session file (events.jsonl) are parsed, the result is sealed and detected by the extension. Hooks are a Preview feature |
| Claude Code | Stop hook agentvow check --hook (settings: {"hooks": {"Stop": [{"hooks": [{"type": "command", "command": "agentvow check --hook --evidence-pack"}]}]}} in .claude/settings.json) | Verified on real runs (Claude Code 2.1.263, claude -p): payload and transcript parsed, result sealed, never blocks; the --evidence-pack background run (capture, both replay contexts, changed-line coverage) verified on one toy project |
| Copilot CLI (terminal), Copilot cloud agent | same hook file | From documentation only |
| Codex, Cursor, Gemini CLI | their stop hooks → agentvow check --hook | Not tested; AGENTVOW_DEBUG=1 records only the structure of what an agent sends so an adapter can be built |
| Any agent's pull request | GitHub Action action.yml: PR description as the claim, CI results, comment + report | Shell step tested locally; not run on GitHub |
| Anything else | paste or pipe the message; VS Code commands for clipboard/selection | Tested |
Copilot keeps only decision/reason from a hook's output, so a hook cannot add text to Copilot's own reply. The verdict is shown in:
agentvow.notify: review default, always, never) and the report panel; the extension logs to the Agentvow output channel;@agentvow in the chat: prints the last sealed verdict as its own message (not part of Copilot's reply);agentvow agent-instructions --write .github/copilot-instructions.md: tells the chat agent to run the check itself and show its output (works through the model; the agent chooses the draft it checks, so the independent hook remains the check that does not depend on the agent);agentvow check --hook --feedback-to-agent (opt-in): asks the agent, once, to revise an answer with a contradicted claim (the only mode in which the hook can block);agentvow post-test-hook (opt-in, Claude Code PostToolUse on Bash): captures the environment right after the agent runs its tests, so the pack can say whether files were edited after the last test run (docs/CAPSULES.md).agentvow check --hook --evidence-pack (opt-in): after the agent stops, a background run captures its environment, replays the tests in the captured environment and in the project's own setup, measures changed-line coverage and updates the result with an Evidence pack (docs/EVIDENCE_PACK.md).agentvow check --hook --background-tests (opt-in): the hook answers at once with what it can see, then runs your tests in the background (sandboxed, macOS/Linux) and updates the verdict when they finish, so slow suites do not hit the agent's hook timeout. Changes are counted since the previous check in the repository (not since your last commit), so earlier uncommitted work is not blamed on the agent.UserPromptSubmit hook (agentvow prompt-hook) that tells the agent the last verdict on your next prompt. In one live session the first delivery coincided with a Copilot chat that stalled (cause unproven).
Details and a step-by-step live test: docs/LIVE_TESTING.md.From the Marketplace: search for Agentvow, or run code --install-extension NavikkumarModi.agentvow. (From a checkout: code --install-extension dist/agentvow-0.2.1.vsix --force.) You also need the command-line tool (pip install agentvow).
Then Developer: Reload Window, and click Agentvow in the status bar to try the demo. The extension is plain JavaScript with no dependencies; it calls the agentvow command, which must be reachable by path (use the full path in agentvow.command if VS Code does not see your shell's PATH).
Running tests executes the project's code. It runs in a sandbox: macOS sandbox-exec or Linux bubblewrap (apt install bubblewrap; on Ubuntu 24.04+ unprivileged user namespaces must be allowed, e.g. sysctl kernel.apparmor_restrict_unprivileged_userns=0; agentvow doctor tells you). Network denied, file writes only inside a throwaway worktree plus a private scratch directory, signing key and credential folders unreadable, whole process group killed on timeout; on Windows, or where no working sandbox exists, Agentvow refuses to run tests (static checks and CI reading still work; agentvow doctor says which). The Linux sandbox makes the whole filesystem read-only; the macOS one allows OS services by default (a review showed a Mach service could still write outside it; common helpers like open/defaults/osascript are blocked, which is not complete containment). Results are HMAC-sealed with a key outside the repository, which stops casual forgery and files copied from elsewhere, but test results are only as trustworthy as the repository's own test code: a hostile conftest.py can print fake pass counts. Treat a "no contradiction" on an untrusted repository accordingly. Text from agents and repositories is length-bounded, stripped of control characters and escaped in reports and in plain-text output. Full model, reviews and open weaknesses: docs/SECURITY_MODEL.md, docs/research/RISKS.md.
docs/research/CI_CLAIM_STUDY.mddocs/research/LOCAL_COVERAGE.mdreview policy), none was declared fine, and 1 of 14 CI-passing controls got a false alert (a dependency-version mismatch, since guarded). Small, clustered, in-sample for the follow-up rules. docs/research/DETECTION_V2.mddocs/research/PLANTED_FAULTS.md, docs/research/DETECTION_STUDY.mddocs/research/NOVELTY_BOUNDARY.md.Python only for impact and API checks; claim extraction is rule-based (three claim types); CI job classification is by name; trivialised tests are not detected; tests that start daemons can hang under the sandbox (ends at --test-timeout); hooks and Copilot integration are Preview features and only the Copilot CLI engine inside VS Code has been observed live; Windows has no test sandbox (tests are refused there); the chat-injection routes go through the model; one annotator behind every hand-validated number.
scripts/validate_all.sh        # tests, consistency, secret scan, wheel + clean-room install, extension package, leaks (builds dist/)
python3 -m unittest discover -s tests && node --test vscode/test/extension.test.js vscode/test/helpers.test.js
Design and research: docs/research/ (start with NOVELTY_BOUNDARY.md, RISKS.md, PILOT_P0.md), product notes docs/product/, rules for contributors CLAUDE.md. License: MIT (LICENSE).
Download counts and popularity will appear here as the collector receives them.
| Version | Published | Direct dependencies | Open version |
|---|---|---|---|
| 0.2.1 | 14 Oct 2026 | 0 |
This describes our collected data; it is not a security assessment.
Observed since 21 Oct, 08:55 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
package:f41b90fa6b5d2072f097b8834103da68034fbebcb15d6ffb9b10ced1013bb651