
Current collected state Current
Observed since 21 Oct, 09:07 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
AgileRL is a deep reinforcement learning library focused on improving RL development through RLOps.

The complete post-training stack for LLMs + RL for any problem
Visit our website. View documentation.
Join the Discord Server for questions, help and collaboration.



AgileRL takes an open-weights LLM from supervised fine-tuning through preference tuning to multi-turn agentic RL, in one library. The same library covers classic deep RL (single-agent, multi-agent, offline and bandits) with evolutionary hyperparameter optimization built in.
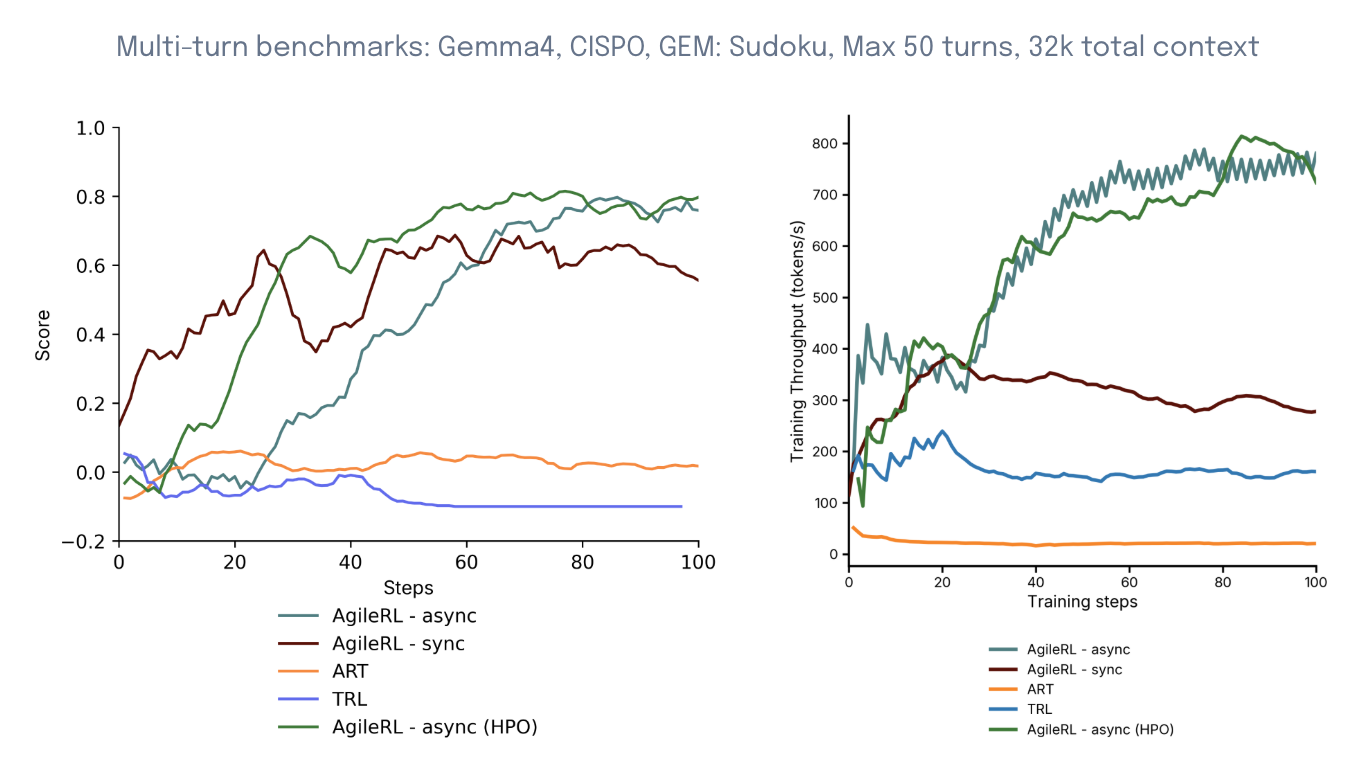
torchrun. One FSDPConfig works for every LLM algorithm. See Multi-GPU LLM training.arena agent generate.AgileRL trains on over 4x more tokens/s than ART and TRL, and reaches higher reward on half the GPU memory.
AgileRL's CISPO against ART and TRL on the GEM Sudoku Hard task: 32k-token context, up to 50 turns per rollout. The async and HPO runs were on Arena. AgileRL ran on A100 40GB nodes. ART and TRL needed A100 80GB. All runs used the same starting hyperparameters.
pip install "agilerl[llm]"        # LLM post-training
pip install agilerl               # classic RL + the Arena CLI
| Installation | Description |
|---|---|
agilerl[llm] | Hugging Face transformers, PEFT, datasets, Liger, bitsandbytes, and vLLM (Linux). |
agilerl[cpu-llm] | Same Hugging Face stack as [llm], without vLLM. Use this when you do not need the vLLM engine (for example with [cpu]). |
agilerl[box2d] | Box2D physics engine for Gymnasium environments. |
agilerl[cpu] | CPU-only PyTorch wheels (no NVIDIA stack). |
agilerl[all] | Box2D and LLM extras. |
agilerl-arena | Arena SDK and CLI only, no torch. Included with agilerl. |
PyPI is the released line. main can be ahead.
For the development tip of main: pip install git+https://github.com/AgileRL/AgileRL.git@main. For development mode: clone the repo and run pip install -e ..
Every training run is a YAML manifest. Arena runs it on managed GPU clusters, with async rollouts and population-based HPO across nodes. Supported base models range from Qwen, Granite and Gemma up to 100B+ models such as Nemotron 3.5 Super VL 120B-A12B, and the list keeps growing. The arena CLI ships with agilerl:
arena login
arena models list                                   # supported base models
arena experiments submit my_manifest.yaml --project my-project
arena agent deploy my-experiment                    # deploy the best checkpoint
arena agent run my-deployment
arena agent generate --prompt "What is 17 * 23?"
Point Cursor, Claude Code or Codex at the arena CLI and it can run the whole loop itself: write a manifest, check it, launch it, pull metrics and deploy.
export ARENA_API_KEY="arena_pat_..."                # no interactive login
arena manifest schema                               # JSON Schema the agent writes against
arena manifest validate my_manifest.yaml --json     # one JSON verdict, stable exit codes
arena experiments submit my_manifest.yaml --project my-project
arena experiments metrics my-experiment             # download metrics to judge the run
Upload your own data with arena datasets create, or your own environment with arena env validate. The same operations are on ArenaClient in Python. See the Arena docs and the agilerl-arena README.
The same manifests run on your own GPU. This one trains Qwen2.5-0.5B with GRPO on GEM's multi-turn Guess the Number game:
pip install gem-llm
python -m agilerl.train configs/training/llm_finetuning/grpo_env.yaml
Or from Python:
from agilerl import LocalTrainer

trainer = LocalTrainer.from_manifest("configs/training/llm_finetuning/grpo_env.yaml")
population, fitnesses = trainer.train()
More manifests for SFT, DPO, CISPO, GSPO, LLM PPO and LLM REINFORCE are in configs/training/llm_finetuning.

On-policy, off-policy, offline, multi-agent and contextual bandit algorithms, all with evolutionary HPO. Train a population of agents and the hyperparameters evolve during a single run, instead of running hundreds of trials first.
from agilerl import LocalTrainer
from agilerl.models import TrainingSpec

trainer = LocalTrainer(
    algorithm="DQN",
    environment="LunarLander-v3",
    training=TrainingSpec(pop_size=4),
    hpo=True,
)
population, fitnesses = trainer.train()
Or from a manifest: python -m agilerl.train configs/training/dqn/dqn.yaml. You can swap in your own Gymnasium or PettingZoo environments, evolvable networks, algorithms or training loops. See Trainers.
A single AgileRL run with evolutionary HPO against the multiple Optuna runs needed to tune other frameworks. Global steps counts every step taken by every agent in the population:

| Tutorial Type | Description | Tutorials |
|---|---|---|
| LLM Fine-tuning | SFT, DPO, single- and multi-turn RL, HPO and remote environments. | GRPO reasoning SFT and DPO GRPO with HPO Multi-turn GRPO and PPO Remote env server |
| Training on Arena | Upload and validate custom environments, submit training jobs on managed cloud infrastructure, and deploy trained agents for inference. | PPO - Acrobot Custom Environment |
| Single-agent tasks | Train on- and off-policy agents on Gymnasium environments. | PPO - Acrobot TD3 - Lunar Lander Rainbow DQN - CartPole Recurrent PPO - Masked Pendulum |
| Multi-agent tasks | PettingZoo environments, including Connect Four with curriculum learning and self-play. | DQN - Connect Four MADDPG - Space Invaders MATD3 - Speaker Listener |
| Hierarchical curriculum learning | Teach agents skills and combine them to reach an end goal. | PPO - Lunar Lander |
| Contextual multi-arm bandits | Make the right decision in single-timestep environments. | NeuralUCB - Iris Dataset NeuralTS - PenDigits |
| Custom Modules & Networks | Build custom evolvable modules and networks. | Dueling Distributional Q Network EvolvableSimBa |
| RL | Algorithm |
|---|---|
| Multi-agent | Multi-Agent Deep Deterministic Policy Gradient (MADDPG) Multi-Agent Twin-Delayed Deep Deterministic Policy Gradient (MATD3) Independent Proximal Policy Optimization (IPPO) |
| RL | Algorithm |
|---|---|
| Bandits | Neural Contextual Bandits with UCB-based Exploration (NeuralUCB) Neural Contextual Bandits with Thompson Sampling (NeuralTS) |
If you use AgileRL in your work, please cite the repository:
@software{Ustaran-Anderegg_AgileRL,
author = {Ustaran-Anderegg, Nicholas and Pratt, Michael and Sabal-Bermudez, Jaime and Doherty, Michael},
license = {Apache-2.0},
title = {{AgileRL}},
url = {https://github.com/AgileRL/AgileRL}
}
Download counts and popularity will appear here as the collector receives them.
| Version | Published | Direct dependencies | Open version |
|---|---|---|---|
| 2.56.1 | 15 Oct 2026 | 40 |
This describes our collected data; it is not a security assessment.
Observed since 21 Oct, 09:07 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
package:79f2caf25f47bc9caab4ca40e26681a9b2334b2cbcad0cdbd140f8776c98cd46