
 Repository
Current collected state Current
Observed since 21 Oct, 09:16 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
AGNES - Flexible Reinforcement Learning Framework with PyTorch
Status: This framework is under active development and bugs may occur.


(Current results)
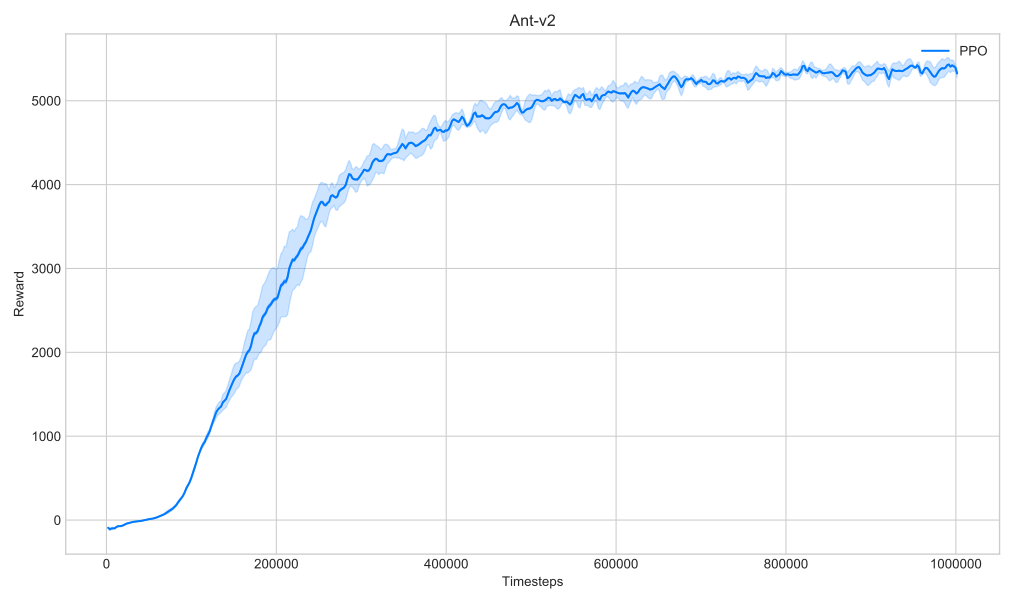 MuJoCo "Ant-v2" training with 1M steps. Single runner with PPO algorithm, MLP NN and 32 number of envs. The curve is an average of 3 runs.
You can get the Tensorboard log file by clicking the image above(You will be redirected to the destination GitHub folder). The default config for the MuJoCo environment was used. Plotted by examples/plot.py
(Old results)
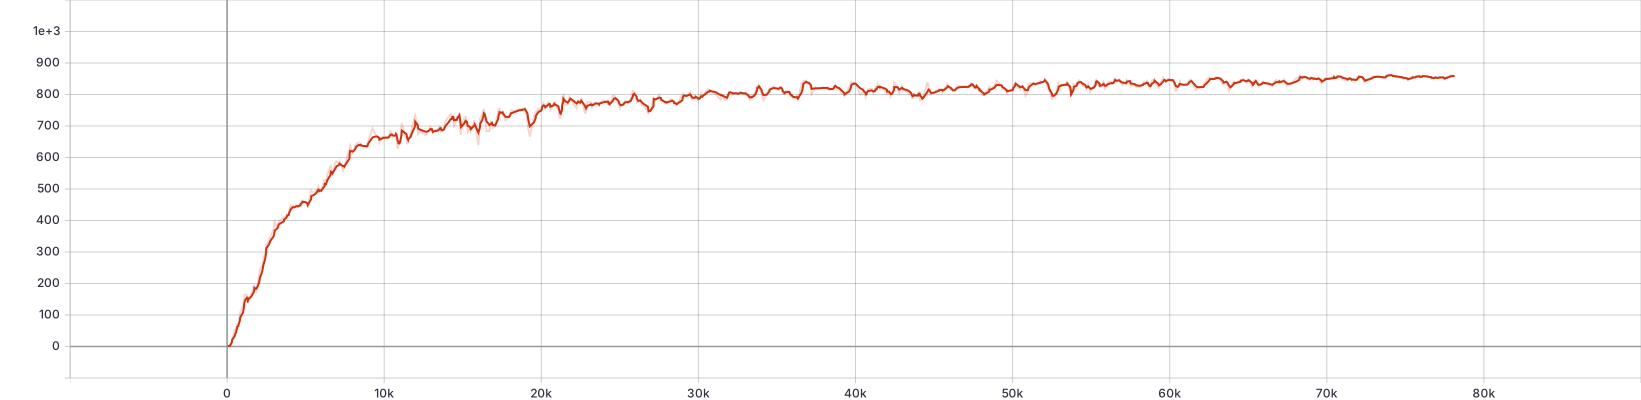 Atari "BreakoutNoFrameskip-v4" with frame stack training with 10M steps. DistributedMPI runner with PPO algorithm, LSTMCNN and 16 number of envs.
You can get the Tensorboard log file by clicking the image above(You will be redirected to the destination GitHub folder). The default config for the Atari environment was used.
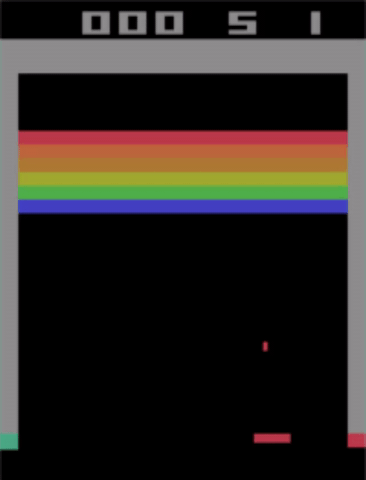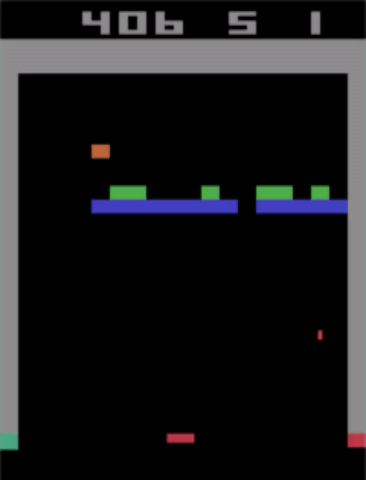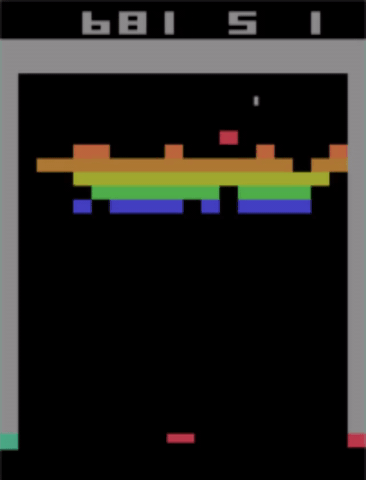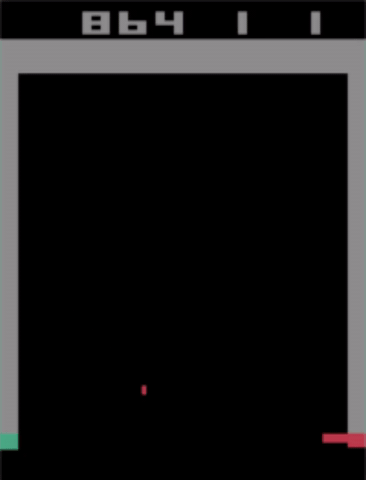
Grad-cam technique was used for sampled action chosen by trained LSTMCNN(previous point).

One worker and trainer. agnes.make_vec_env can also be used here.
import agnes
import time


if __name__ == '__main__':
    env = agnes.make_env("InvertedDoublePendulum-v2")
    runner = agnes.Single(env, agnes.PPO, agnes.MLP)
    runner.log(agnes.log, agnes.TensorboardLogger(".logs/"), agnes.CsvLogger(".logs/"))
    runner.run()
agnes.log - object of StandardLogger class that outputs parameters to console. agnes.TensorboardLogger - class for writing logs in Tensorboard file. agnes.CsvLogger - class for writing logs in csv file. (required for plotting)
Unlike in Single runner, in DistributedMPI runner due to async executing, weights are delayed by one rollout but this has no effect on learning because weights are delayed only by one update as it is in Single runner. So all parameters like probabilities ratio stay the same.
Runs with
mpiexec -n 3 python -m mpi4py script_name.py
or
mpirun -n 3 python -m mpi4py script_name.py
This command will run 2 workers and 1 trainer.
# script_name.py
import agnes


if __name__ == '__main__':
    env = agnes.make_vec_env("BreakoutNoFrameskip-v4")
    runner = agnes.DistributedMPI(env, agnes.PPO, agnes.CNN)
    runner.run()
Sync version of Advantage Actor Critic is implemented in this framework and can be used simply:
import agnes


if __name__ == '__main__':
    runner = agnes.Single(env, agnes.A2C, agnes.MLP)
    runner.run()
Proximal Policy Optimization is implemented in this framework and can be used simply:
import agnes


if __name__ == '__main__':
    runner = agnes.Single(env, agnes.PPO, agnes.MLP)
    runner.run()
Can be used with both continuous and discrete action spaces.
...
runner = agnes.Single(env, agnes.PPO, agnes.MLP)
...
Can be used only with discrete action spaces.
...
runner = agnes.Single(env, agnes.PPO, agnes.CNN)
...
Can be used with both continuous and discrete action spaces.
...
runner = agnes.Single(env, agnes.PPO, agnes.RNN)
...
Can be used only with discrete action spaces.
...
runner = agnes.Single(env, agnes.PPO, agnes.RNNCNN)
...
Can be used only with discrete action spaces.
...
runner = agnes.Single(env, agnes.PPO, agnes.LSTMCNN)
...
make_vec_env(env, envs_num=ncpu, config=None)**
Parameters:
Returns:
The whole tuple should be put in a runner.
make_env(env, config=None) is an alias of make_vec_env without envs_num argument that will be setted to 1.
Notice: Some plot functions and environment wrappers were taken from OpenAI Baselines(2017).
Download counts and popularity will appear here as the collector receives them.
| Version | Published | Direct dependencies | Open version |
|---|---|---|---|
| 0.0.7.4 | 29 May 2020 | 9 |
This describes our collected data; it is not a security assessment.
Observed since 21 Oct, 09:16 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
package:d819509441321e8e90c2579a29a8d3f6eb6374616227b2ab8f7d9cbe418fcd7f