
 Repository
Current collected state Current
Observed since 21 Oct, 11:06 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
An automated machine learning framework


Automatic Tool Kit for Machine Learning and Datascience.
The objective is to provide tools to ease the repetitive part of the DataScientist job and so that he/she can focus on modelization. This package is still in alpha and more features will be added. Its mains features are:
Full documentation is available here: https://aikit.readthedocs.io/en/latest/
You can run examples here, thanks to Binder.
The GraphPipeline object is an extension of sklearn.pipeline.Pipeline but the transformers/models can be chained with any directed graph.
The objects takes as input two arguments:
Example:
gpipeline = GraphPipeline(
    models = {
        "vect": CountVectorizerWrapper(analyzer="char",
                                       ngram_range=(1, 4),
                                       columns_to_use=["text1", "text2"]),
        "cat": NumericalEncoder(columns_to_use=["cat1", "cat2"]),
        "rf": RandomForestClassifier(n_estimators=100)
    },
    edges = [("vect", "rf"), ("cat", "rf")]
)
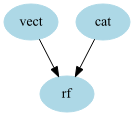
Aikit contains an AutoML part which will test several models and transformers for a given dataset.
For example, you can create the following python script run_automl_titanic.py:
from aikit.datasets import load_dataset, DatasetEnum
from aikit.ml_machine import MlMachineLauncher

def loader():
    dfX, y, *_ = load_dataset(DatasetEnum.titanic)
    return dfX, y

def set_configs(launcher):
    """ modify that function to change launcher configuration """
    launcher.job_config.score_base_line = 0.75
    launcher.job_config.allow_approx_cv = True
    return launcher

if __name__ == "__main__":
    launcher = MlMachineLauncher(base_folder = "~/automl/titanic",
                                 name = "titanic",
                                 loader = loader,
                                 set_configs = set_configs)
    launcher.execute_processed_command_argument()
And then run the command:
python run_automl_titanic.py run -n 4
To run the automl using 4 workers, the results will be stored in the specified folder You can aggregate those result using:
python run_automl_titanic.py result
Download counts and popularity will appear here as the collector receives them.
| Version | Published | Direct dependencies | Open version |
|---|---|---|---|
| 0.2.2 | 18 Sept 2020 | 8 |
This describes our collected data; it is not a security assessment.
Observed since 21 Oct, 11:06 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
package:fef89d2086ea75f8315705eb2d169d0dea8cfcd2057a1297687cbfb4c04a1632