

 Repository
Current collected state Current
Observed since 20 Oct, 18:25 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
acroforge
Turn flat PDFs into real, fillable AcroForms - permissive, deterministic, zero-copyleft.
Turn flat PDFs into real, fillable AcroForms. Permissive (Apache-2.0), deterministic, zero-copyleft.




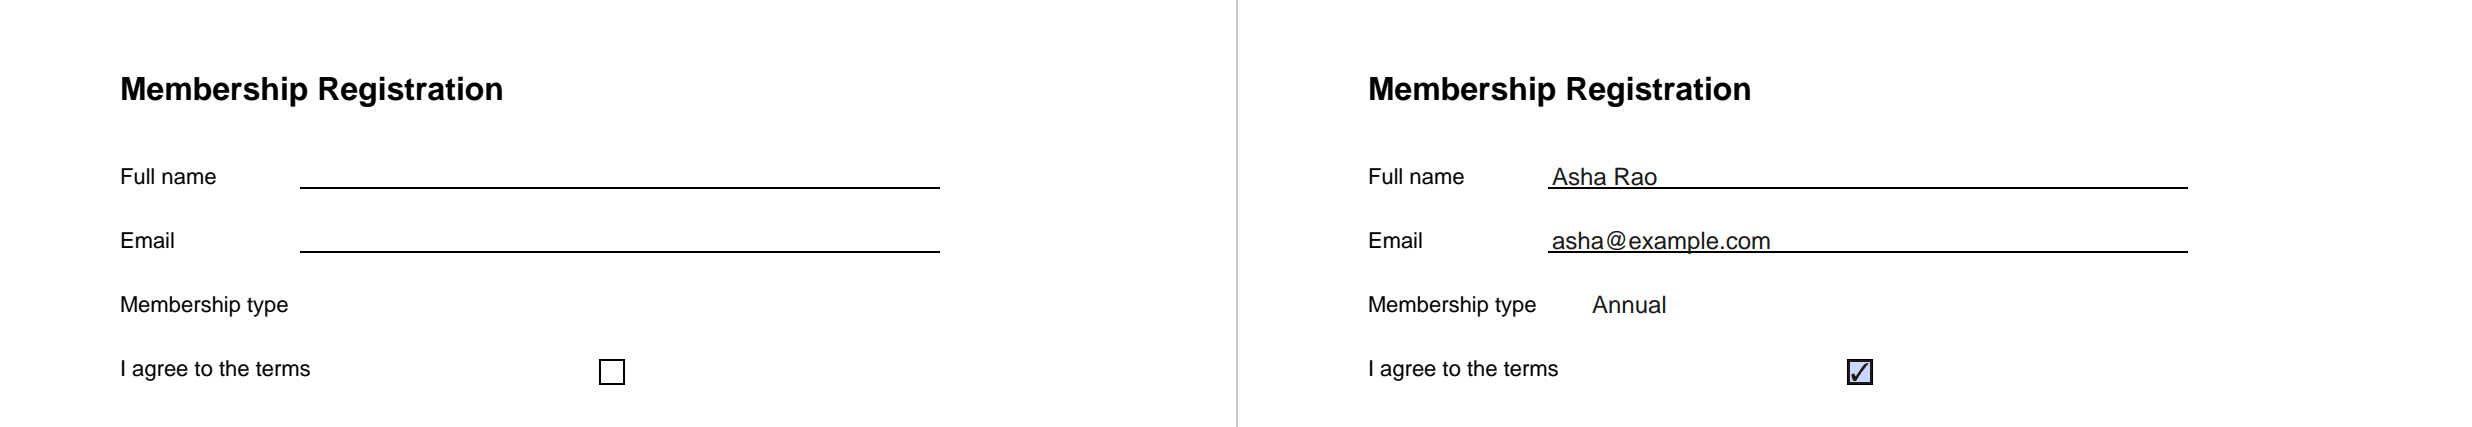
Left: a flat PDF - just printed lines and an empty box. Right: the same PDF after acroforge - real, fillable form fields, filled and rendered correctly. No Adobe, no cloud, no AGPL.
acroforge takes any PDF - vector or scanned - and injects real AcroForm fields at positions you specify. The result is a standards-compliant fillable PDF that renders correctly in Chrome's pdfium and Firefox's pdf.js.
Four operations:
| Operation | What it does |
|---|---|
build | Inject interactive AcroForm fields into a flat PDF |
fill | Set field values by name on a fillable PDF |
remove | Delete specific fields by name (raises if a name is missing) |
flatten | Bake field appearances into page content; remove interactive fields |
All accept and return plain bytes, making them easy to compose in any pipeline.
The deterministic core (build / fill / flatten / read_fields) is validated against 125 real public PDF forms - IRS and other government forms (VA, OPM, GSA), CMS / Medicare and hospital healthcare forms, federal- and state-court legal forms, and SBA / USPTO / vendor business forms. It reads every one of them, and fills, flattens, and round-trips every fillable one (over 11,000 real fields) without a single crash. Every field type renders correctly in Chrome's pdfium and Firefox's pdf.js, golden-image tested in CI.
The detect() layer below is separate and clearly labeled best-effort.
pip install acroforge
Or from source:
git clone https://github.com/san64777/acroforge
cd acroforge
pip install -e .   # or: uv pip install -e .
import io
from reportlab.pdfgen import canvas  # any PDF source works
import acroforge as af
from acroforge import FieldSpec, FieldType

# --- Step 0: obtain a flat PDF (bytes) any way you like ---
buf = io.BytesIO()
c = canvas.Canvas(buf, pagesize=(612, 792))
c.drawString(72, 720, "Name:")
c.drawString(72, 680, "Agree to terms:")
c.save()
flat_pdf: bytes = buf.getvalue()

# --- Step 1: describe the fields you want ---
fields = [
    FieldSpec(
        type=FieldType.TEXT,
        page=0,
        rect=(200, 700, 450, 730),  # (x0, y0, x1, y1) in PDF points
        name="full_name",
    ),
    FieldSpec(
        type=FieldType.CHECKBOX,
        page=0,
        rect=(200, 660, 220, 680),
        name="agree",
        export_value="Yes",
    ),
]

# --- Step 2: inject the fields ---
fillable: bytes = af.build(flat_pdf, fields)

# --- Step 3: fill values ---
filled: bytes = af.fill(fillable, {"full_name": "Jane Doe", "agree": True})

# --- Step 4: flatten (optional - locks the form) ---
final: bytes = af.flatten(filled)

# Write to disk
with open("output.pdf", "wb") as f:
    f.write(final)
# 1. Inject fields described in a JSON manifest
acroforge build in.pdf manifest.json fillable.pdf

# 2. Fill fields from a JSON object {name: value}
acroforge fill fillable.pdf data.json filled.pdf

# 3. Flatten (bake and lock)
acroforge flatten filled.pdf final.pdf
Example manifest.json:
[
  {
    "type": "text",
    "page": 0,
    "rect": [200, 700, 450, 730],
    "name": "full_name"
  },
  {
    "type": "checkbox",
    "page": 0,
    "rect": [200, 660, 220, 680],
    "name": "agree",
    "export_value": "Yes"
  },
  {
    "type": "radio",
    "page": 0,
    "rect": [200, 620, 220, 640],
    "name": "plan",
    "options": ["basic", "pro", "enterprise"],
    "export_value": "pro"
  }
]
Example data.json:
{"full_name": "Jane Doe", "agree": true, "plan": "pro"}
| Type | FieldType | Notes |
|---|---|---|
| Single-line text | FieldType.TEXT | Optional maxlen to cap character count |
| Multi-cell comb | FieldType.COMB | maxlen sets the number of cells (e.g. SSN = 9) |
| Checkbox | FieldType.CHECKBOX | export_value is the on-state value (default "Yes") |
| Radio button | FieldType.RADIO | One FieldSpec per button; share name, set export_value per button |
| Signature | FieldType.SIGNATURE | Placeholder widget - renders a blank sig box |
| Dropdown / list box | FieldType.CHOICE | options lists the choices; list_box, multi_select, editable flags (see note) |
FieldSpec referenceclass FieldSpec(BaseModel):
type: FieldType
page: int # 0-indexed
rect: tuple[float, float, float, float] # (x0, y0, x1, y1) in PDF points
name: str # AcroForm field name
options: list[str] | list[tuple[str, str]] | None = None # choice options (str or (export, label))
maxlen: int | None = None # TEXT cap / COMB cell count
export_value: str | None = None # radio/checkbox on-value
list_box: bool = False # CHOICE: False=dropdown, True=list box
multi_select: bool = False # CHOICE list box: allow multiple selections
editable: bool = False # CHOICE combo: accept free-typed text
confidence: float = 1.0 # 1.0 = explicit; <1.0 = best-effort guess
FieldType.CHOICE)# dropdown (combo box)
FieldSpec(type=FieldType.CHOICE, page=0, rect=(200, 620, 360, 640),
name="state", options=["CA", "NY", "TX"])
# (export, label) pairs: store "CA", display "California"
FieldSpec(type=FieldType.CHOICE, page=0, rect=(200, 580, 360, 600),
name="st", options=[("CA", "California"), ("NY", "New York")])
# scrolling list box, multi-select
FieldSpec(type=FieldType.CHOICE, page=0, rect=(200, 500, 360, 570),
name="langs", options=["en", "fr", "de"], list_box=True, multi_select=True)
All four variants - dropdown, single-select list box, editable dropdown, and
multi-select list box - are cross-viewer verified: the selected value renders in
both pdfium and pdf.js. read_fields recovers a choice field's structure (its
options and the list_box / multi_select / editable flags); it does not
recover the current selection, since a FieldSpec describes the field, not its
filled value.
In addition to the deterministic engine, acroforge ships an optional, best-effort detector that guesses where fields belong on a flat vector PDF by reading its vector geometry and nearby text labels. It handles both common form archetypes:
import acroforge as af

pdf = open("form.pdf", "rb").read()

# Inspect candidate fields (a FormManifest); every field has confidence < 1.0
manifest = af.detect(pdf)
for f in manifest.fields:
    print(f.type, f.name, f.rect, f.confidence)

# Or go straight to a fillable PDF (detect() then build())
fillable: bytes = af.make_fillable(pdf)
CLI:
# Print the detected manifest as JSON (review it!)
acroforge detect form.pdf

# Detect and write a fillable PDF in one step
acroforge make-fillable form.pdf fillable.pdf
Read this before relying on it:
ScannedPDFError - there is no OCR.FieldSpec carries confidence < 1.0 to
flag it as a guess. Explicitly authored specs use confidence = 1.0.detect() / make-fillable as a
draft manifest to inspect and correct, not a finished form.read_fields(pdf) ingests the AcroForm fields already present in a fillable PDF as FieldSpecs (real registered fields, so confidence = 1.0). It is the inverse of build, so the two round-trip:
import acroforge as af

specs = af.read_fields(open("fillable.pdf", "rb").read())   # -> list[FieldSpec]
for s in specs:
    print(s.type.value, s.name, s.rect)

# copy one form's field layout onto another PDF
af.build(other_pdf, af.read_fields(template_pdf))
(One FieldSpec per widget, with coordinates, type, name, and checkbox/radio on-states recovered. Dropdowns are reported as text. Pushbuttons are skipped.)
remove(pdf, names) deletes specific fields by the name read_fields reports, so the two compose. Handy when make_fillable over-detects, or to strip a field before sending a form:
specs = af.read_fields(pdf)
junk = [s.name for s in specs if s.type == af.FieldType.SIGNATURE]
clean = af.remove(pdf, junk)        # raises ValueError if any name is missing
Naming a radio group removes the whole group; removing the last field leaves an empty, re-usable /AcroForm.
detect() returns a FormManifest and read_fields() returns list[FieldSpec] - both pydantic models, so store / send-to-a-UI / round-trip them with pydantic's built-ins (no extra API to learn):
data = manifest.model_dump_json()                  # -> JSON string
manifest = FormManifest.model_validate_json(data)  # -> back to a FormManifest
af.build(pdf, manifest.fields)                      # build from the (edited) specs
(export, label) option pairs round-trip as [export, label] arrays and back to tuples; generate a TypeScript type from FormManifest.model_json_schema().
The reliable part is the deterministic build / fill / flatten engine. You
supply field positions via FieldSpecs - acroforge injects, fills, and flattens them
reliably at exactly the coordinates you give it, on any PDF (vector or scanned).
detect() / make_fillable() are the best-effort layer described above: use them
to bootstrap a manifest, then review and hand off the corrected specs to the engine.
XFA / dynamic forms: some PDFs (many government forms) carry a dynamic XFA layer over the standard AcroForm. acroforge operates on the AcroForm layer - which is what most viewers render - and drops the XFA layer on output. Flattened output is unambiguous everywhere; for interactive output, an XFA-first viewer (some Adobe configurations) may prefer the dropped layer, so flatten the result if you need cross-Adobe fidelity.
There is no AI in this package, and no copyrighted form templates are bundled - bring your own PDFs.
Runtime dependencies are strictly permissive:
| Package | License | Role |
|---|---|---|
reportlab | BSD | Field widget rendering |
pypdf | BSD-3-Clause | PDF read / merge / flatten |
pdfplumber | MIT | PDF geometry utilities |
PyPDFForm | MIT | Fill helpers |
pydantic | MIT | FieldSpec / FormManifest validation |
Optional extras:
[fallback] - adds pikepdf (MPL-2.0) as a fallback PDF writer; not required for the default engine path.[harness] - adds pypdfium2 + Pillow for cross-viewer visual regression tests.No GPL, AGPL, LGPL, or SSPL in the runtime tree. CI enforces this on every push via pip-licenses --fail-on='GPL;AGPL;LGPL;SSPL'.
Apache-2.0. See LICENSE.
No copyrighted form templates are included or bundled. Bring your own PDFs.
Download counts and popularity will appear here as the collector receives them.
| Package / target | Requirement | Relationship |
|---|---|---|
pdfplumberEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.11",
"evaluation": "NOT_EVALUATED"
} | pdfplumber>=0.11.9 | runtime |
pydanticEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.11",
"evaluation": "NOT_EVALUATED"
} | pydantic>=2 | runtime |
pypdfEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.11",
"evaluation": "NOT_EVALUATED"
} | pypdf<7,>=6.13.0 | runtime |
reportlabEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.11",
"evaluation": "NOT_EVALUATED"
} | reportlab>=4.5.1 | runtime |
mypyEnvironment{
"extras": "",
"marker": "extra == \"dev\"",
"requires_python": ">=3.11",
"evaluation": "NOT_EVALUATED"
} | mypy>=1.11; extra == "dev" | runtime |
pip-licensesEnvironment{
"extras": "",
"marker": "extra == \"dev\"",
"requires_python": ">=3.11",
"evaluation": "NOT_EVALUATED"
} | pip-licenses>=5; extra == "dev" | runtime |
pytestEnvironment{
"extras": "",
"marker": "extra == \"dev\"",
"requires_python": ">=3.11",
"evaluation": "NOT_EVALUATED"
} | pytest>=8; extra == "dev" | runtime |
ruffEnvironment{
"extras": "",
"marker": "extra == \"dev\"",
"requires_python": ">=3.11",
"evaluation": "NOT_EVALUATED"
} | ruff>=0.6; extra == "dev" | runtime |
pikepdfEnvironment{
"extras": "",
"marker": "extra == \"fallback\"",
"requires_python": ">=3.11",
"evaluation": "NOT_EVALUATED"
} | pikepdf>=10.7.3; extra == "fallback" | runtime |
pillowEnvironment{
"extras": "",
"marker": "extra == \"harness\"",
"requires_python": ">=3.11",
"evaluation": "NOT_EVALUATED"
} | pillow>=11; extra == "harness" | runtime |
pypdfium2Environment{
"extras": "",
"marker": "extra == \"harness\"",
"requires_python": ">=3.11",
"evaluation": "NOT_EVALUATED"
} | pypdfium2>=5.9.0; extra == "harness" | runtime |
bdist_wheel · 35.65 KB · Python py3
sdist · 764.03 KB · Python source
Observed since 20 Oct, 18:25 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
package_version:23fbe56d68d62174e9a8bca6ca54cc1a1ed67f5601a2068d73edc4a8a29da702