


 Repository
Current collected state Current
Observed since 20 Oct, 21:09 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
afnio
Afnio Python library and Tellurio Studio CLI tool
Afnio is a framework for automatic prompt and hyperparameter optimization, particularly designed for complex AI systems where Language Models (LMs) are employed multiple times in workflows, such as in LM pipelines and agent-driven architectures. Effortlessly build and optimize AI systems for classification, information retrieval, question-answering, etc.
Get started with Afnio in six steps, or try it instantly in Colab: 
pip install afnio
export OPENAI_API_KEY="your-api-key"
afnio login
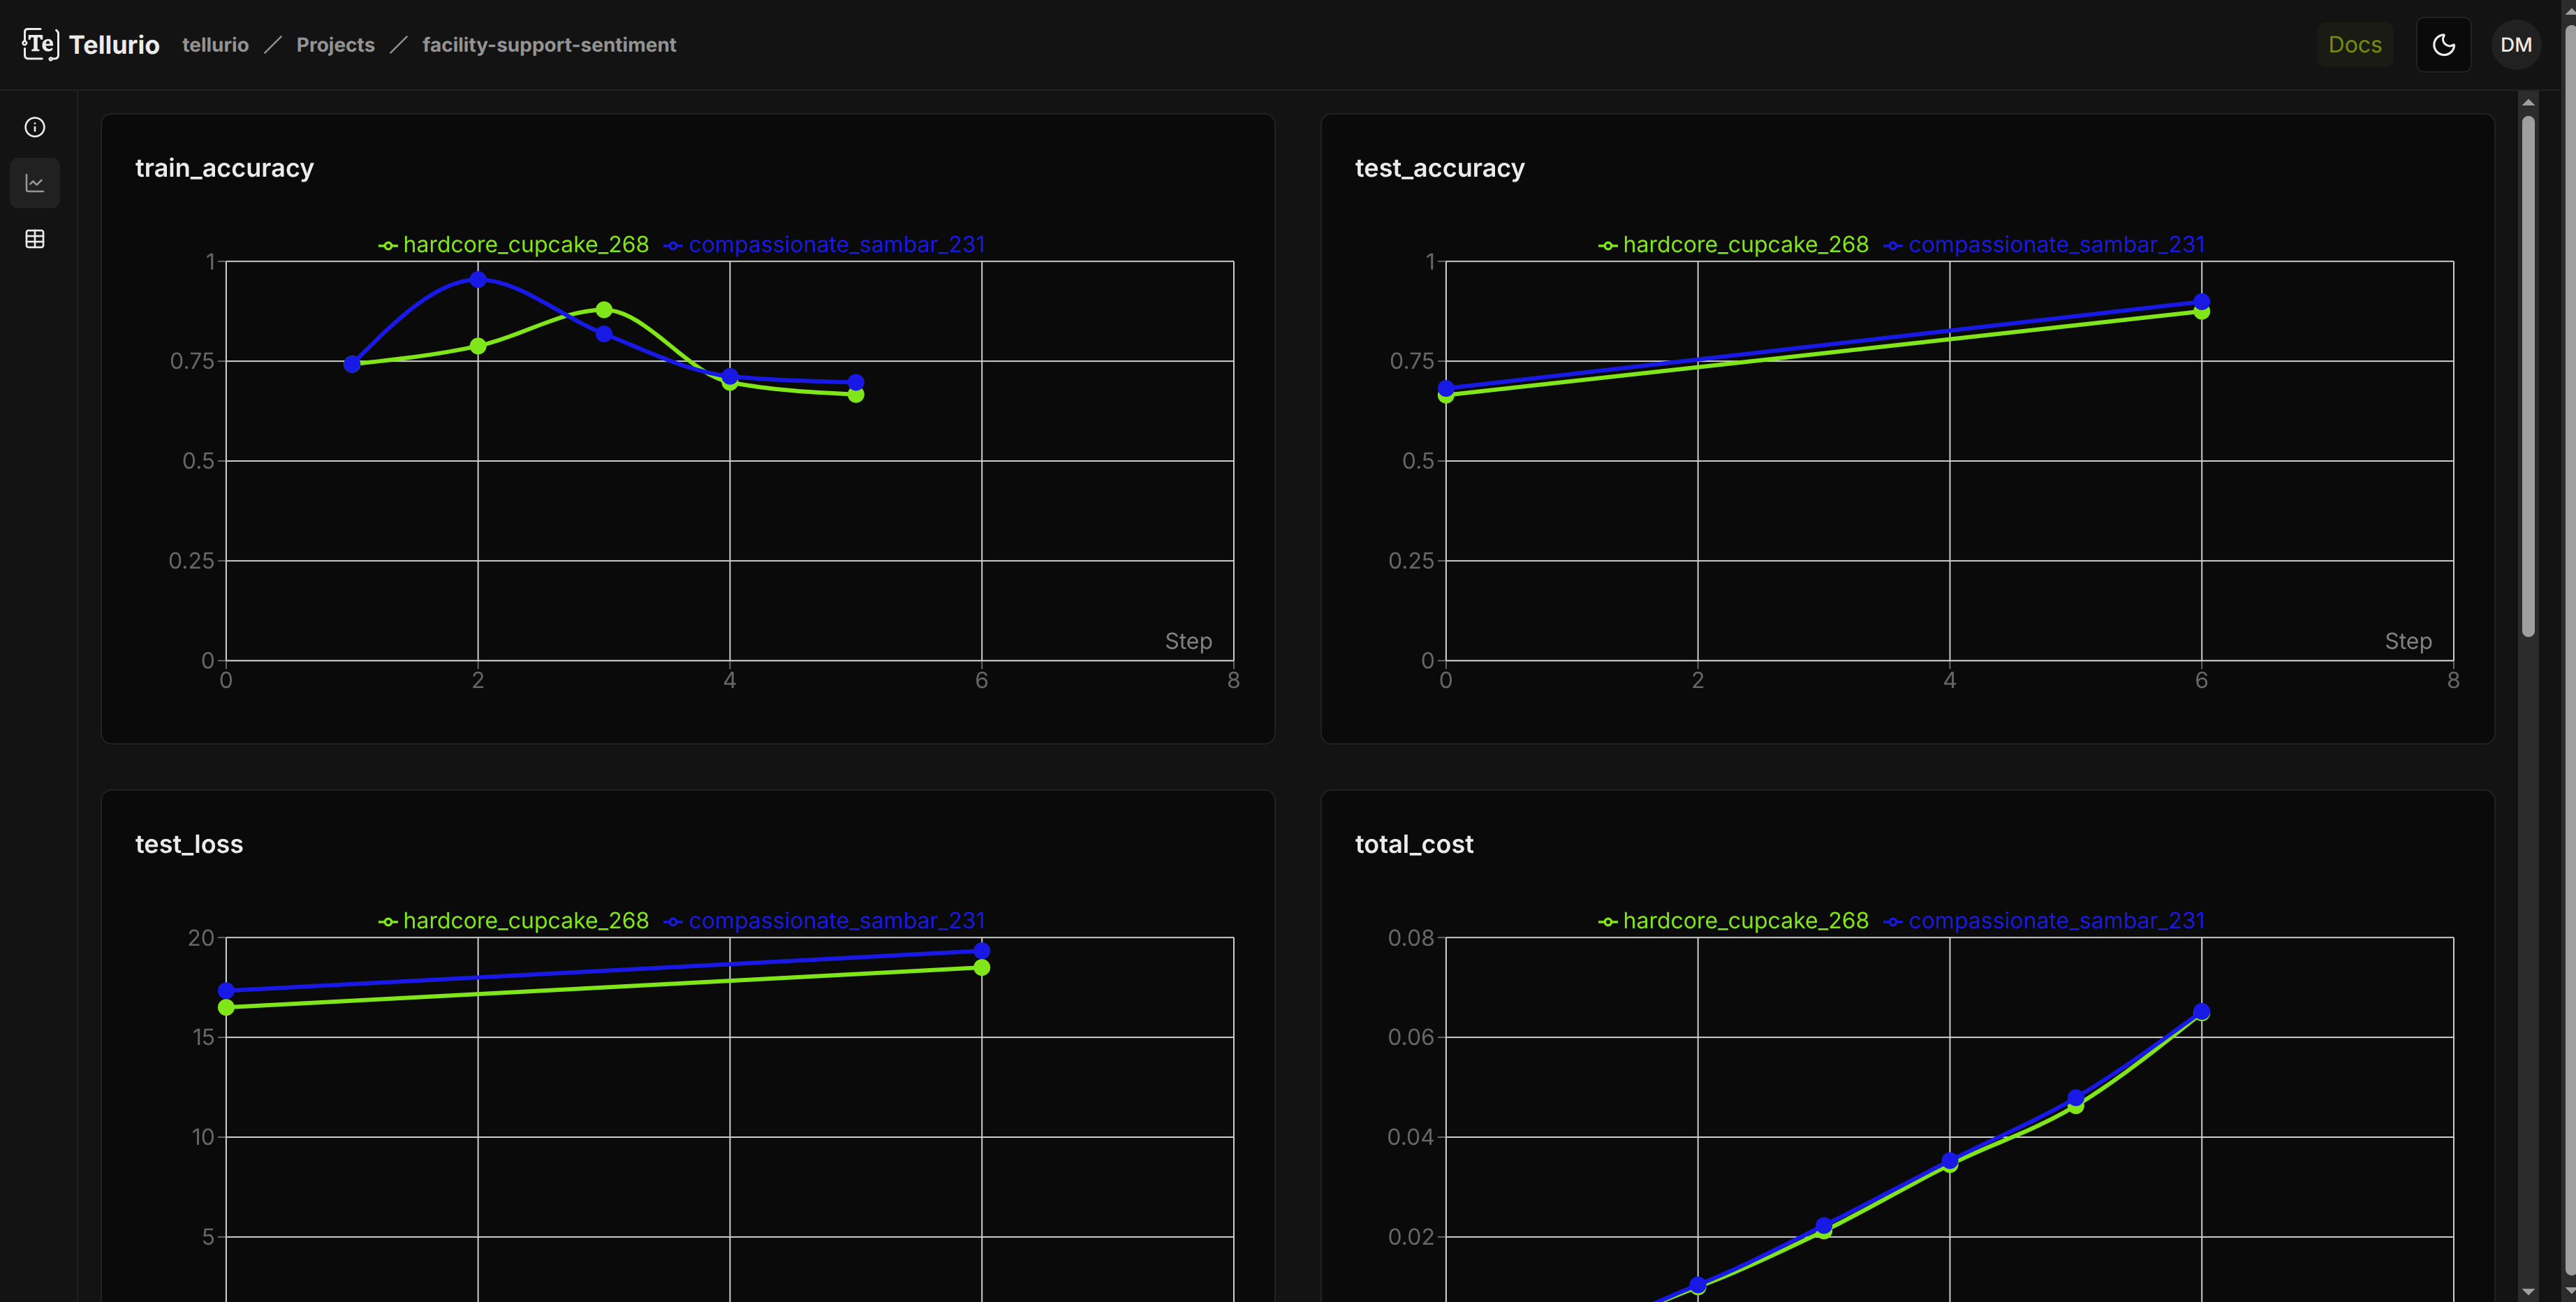
Copy and run this sample code to optimize your AI agent and track its quality metrics. Your first Run will appear in Tellurio Studio. Your system's checkpoints will be saved under the local checkpoint/ directory created in the same path where you executed the script.
This example uses Meta's Facility Support Analyzer dataset to classify enterprise support emails as positive, neutral, or negative. Expect accuracy to improve from 66.4% ±1.5% to 80.8% ±12.5% — a +14.5% absolute gain.
import json
import re

import afnio
import afnio.cognitive as cog
import afnio.cognitive.functional as F
import afnio.tellurio as te
from afnio.models.openai import AsyncOpenAI
from afnio.trainer import Trainer
from afnio.utils.data import DataLoader, WeightedRandomSampler
from afnio.utils.datasets import FacilitySupport

# Initialize Project and experiment Run
run = te.init("your-username", "Facility Support")


# Compute per-sample weights to balance the training set
def compute_sample_weights(data):
    with te.suppress_variable_notifications():
        labels = [y.data for _, (_, y, _) in data]
        counts = {label: labels.count(label) for label in set(labels)}
        total = len(data)
    return [total / counts[label] for label in labels]


# Prepare data and loaders
train_data = FacilitySupport(split="train", root="data")
test_data = FacilitySupport(split="test", root="data")
val_data = FacilitySupport(split="val", root="data")

weights = compute_sample_weights(train_data)
sampler = WeightedRandomSampler(weights, num_samples=len(train_data), replacement=True)

BATCH_SIZE = 33
train_dataloader = DataLoader(train_data, sampler=sampler, batch_size=BATCH_SIZE)
val_dataloader = DataLoader(val_data, batch_size=BATCH_SIZE, seed=42)
test_dataloader = DataLoader(test_data, batch_size=BATCH_SIZE, seed=42)

# Define prompt and response format
sentiment_task = "Read the provided message and determine the sentiment."
sentiment_user = "Read the provided message and determine the sentiment.\n\n**Message:**\n\n{message}\n\n"
SENTIMENT_RESPONSE_FORMAT = {
    "type": "json_schema",
    "json_schema": {
        "strict": True,
        "name": "sentiment_response_schema",
        "schema": {
            "type": "object",
            "properties": {
                "sentiment": {
                    "type": "string",
                    "enum": ["positive", "neutral", "negative"],
                },
            },
            "additionalProperties": False,
            "required": ["sentiment"],
        },
    },
}

# Set up LM model clients used for forward, backward passes and optimization step
afnio.set_backward_model_client("openai/gpt-5", completion_args={"temperature": 1.0, "max_completion_tokens": 32000, "reasoning_effort": "low"})
fw_model_client = AsyncOpenAI()
optim_model_client = AsyncOpenAI()


# Define the sentiment classification agent
class FacilitySupportAnalyzer(cog.Module):
    def __init__(self):
        super().__init__()
        self.sentiment_task = cog.Parameter(data=sentiment_task, role="system prompt for sentiment classification", requires_grad=True)
        self.sentiment_user = afnio.Variable(data=sentiment_user, role="input template to sentiment classifier")
        self.sentiment_classifier = cog.ChatCompletion()

    def forward(self, fwd_model, inputs, **completion_args):
        sentiment_messages = [
            {"role": "system", "content": [self.sentiment_task]},
            {"role": "user", "content": [self.sentiment_user]},
        ]
        return self.sentiment_classifier(fwd_model, sentiment_messages, inputs=inputs, response_format=SENTIMENT_RESPONSE_FORMAT, **completion_args)

    def training_step(self, batch, batch_idx):
        X, y = batch
        _, gold_sentiment, _ = y
        pred_sentiment = self(fw_model_client, inputs={"message": X}, model="gpt-4.1-nano", temperature=0.0)
        pred_sentiment.data = [json.loads(re.sub(r"^```json\n|\n```$", "", item))["sentiment"].lower() for item in pred_sentiment.data]
        loss = F.exact_match_evaluator(pred_sentiment, gold_sentiment)
        return {"loss": loss, "accuracy": loss[0].data / len(gold_sentiment.data)}

    def validation_step(self, batch, batch_idx):
        return self.training_step(batch, batch_idx)

    def test_step(self, batch, batch_idx):
        return self.validation_step(batch, batch_idx)

    def configure_optimizers(self):
        constraints = [
            afnio.Variable(
                data="The improved variable must never include or reference the characters `{` or `}`. Do not output them, mention them, or describe them in any way.",
                role="optimizer constraint",
            )
        ]
        optimizer = afnio.optim.TGD(self.parameters(), model_client=optim_model_client, constraints=constraints, momentum=3, model="gpt-5", temperature=1.0, max_completion_tokens=32000, reasoning_effort="low")
        return optimizer


# Instantiate agent and trainer
agent = FacilitySupportAnalyzer()
trainer = Trainer(max_epochs=5)

# Evaluate the agent on the test set before training (baseline performance)
llm_clients = [fw_model_client, afnio.get_backward_model_client(), optim_model_client]
trainer.test(agent=agent, test_dataloader=test_dataloader, llm_clients=llm_clients)

# Train the agent on the training set and validate on the validation set
trainer.fit(agent=agent, train_dataloader=train_dataloader, val_dataloader=val_dataloader, llm_clients=llm_clients)

run.finish()
💻 Would love to contribute? Please follows our contribution guidelines.
Afnio is open-source under the GNU Affero General Public License v3 (AGPLv3).
You can freely use Afnio — in personal, research, or commercial projects.
You don’t need to open-source your code; the license only applies if you modify Afnio itself and share that version publicly.
We keep Afnio open so everyone can build freely while helping the project grow.
💌 Questions or ideas? We’d love to hear from you at contact@tellurio.ai.
Download counts and popularity will appear here as the collector receives them.
| Package / target | Requirement | Relationship |
|---|---|---|
clickEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.9",
"evaluation": "NOT_EVALUATED"
} | click<9,>=8.1.8 | runtime |
httpxEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.9",
"evaluation": "NOT_EVALUATED"
} | httpx<1,>=0.28.1 | runtime |
ipythonEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.9",
"evaluation": "NOT_EVALUATED"
} | ipython<10,>=7.34.0 | runtime |
ipywidgetsEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.9",
"evaluation": "NOT_EVALUATED"
} | ipywidgets<9,>=8.1.7 | runtime |
keyringEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.9",
"evaluation": "NOT_EVALUATED"
} | keyring<26,>=25.6.0 | runtime |
openaiEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.9",
"evaluation": "NOT_EVALUATED"
} | openai<3,>=2.32.0 | runtime |
python-dotenvEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.9",
"evaluation": "NOT_EVALUATED"
} | python-dotenv<2,>=1.1.0 | runtime |
python-slugifyEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.9",
"evaluation": "NOT_EVALUATED"
} | python-slugify<9,>=8.0.4 | runtime |
richEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.9",
"evaluation": "NOT_EVALUATED"
} | rich<14,>=13.9.4 | runtime |
websocketsEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.9",
"evaluation": "NOT_EVALUATED"
} | websockets<16,>=15.0.1 | runtime |
pytestEnvironment{
"extras": "",
"marker": "extra == \"testing\"",
"requires_python": ">=3.9",
"evaluation": "NOT_EVALUATED"
} | pytest>=8.3.5; extra == "testing" | runtime |
pytest-asyncioEnvironment{
"extras": "",
"marker": "extra == \"testing\"",
"requires_python": ">=3.9",
"evaluation": "NOT_EVALUATED"
} | pytest-asyncio>=0.26.0; extra == "testing" | runtime |
bdist_wheel · 252.48 KB · Python py3
sdist · 221.33 KB · Python source
Observed since 20 Oct, 21:09 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
package_version:35bdf4843ad5a7ff21f693dd2a5afef64a7c5ba95e2ef7450c423b2cc9daaffb