
 Repository
Current collected state Current
Observed since 20 Oct, 23:19 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
agentsentinel-ai
Production-readiness platform for AI agents — inspect, improve, and stress-test before you ship.
Agent Sentinel inspects, improves, and stress-tests AI agents before they ship. It performs static + semantic analysis of an agent's system prompt, tool definitions, memory, and framework structure, produces a risk report, rewrites the prompt to fix every flagged issue, and runs adversarial prompt campaigns to verify the fixes hold under pressure.
agentsentinel/
├── src/agentsentinel/
│   ├── sentinel.py                  # AgentSentinel — main entry point
│   ├── compliance/                  # YAML rule files per standard
│   │   ├── hipaa.yaml
│   │   ├── soc2.yaml
│   │   ├── owasp.yaml
│   │   └── pii.yaml
│   ├── core/agents/
│   │   ├── intake/                  # Framework detection & profile extraction
│   │   │   ├── agent_intake.py      # AgentIntake orchestrator
│   │   │   └── detectors/
│   │   │       ├── langgraph.py     # LangGraph detector
│   │   │       └── filepath.py      # Source file detector
│   │   ├── inspector/               # Static + semantic analysis
│   │   │   ├── orchestrator.py      # InspectorAgent
│   │   │   ├── aggregator.py        # Combines analyzer outputs
│   │   │   └── analyzers/
│   │   │       ├── prompt.py        # Constraint, ambiguity, injection checks
│   │   │       ├── tools.py         # Tool quality scoring
│   │   │       ├── memory.py        # Memory backend risk detection
│   │   │       ├── framework.py     # Graph depth, loops, HITL, cycle detection
│   │   │       ├── semantic.py      # LLM-powered semantic analysis
│   │   │       ├── policy.py        # Policy PDF compliance check
│   │   │       └── compliances.py   # HIPAA / SOC2 / OWASP / PII rule engine
│   │   ├── optimizer/               # DSPy-based prompt rewriter
│   │   │   ├── prompt_optimizer.py  # PromptOptimizer (parallel + sequential fixes)
│   │   │   ├── signatures.py        # DSPy fix signatures per risk category
│   │   │   ├── policy_guard.py      # Final policy compliance gate
│   │   │   └── evaluations.py       # DSPy optimizer metric
│   │   └── tester/                  # Adversarial testing pipeline
│   │       ├── tester.py            # TestAgent orchestrator
│   │       ├── adversarial_prompts_generator.py
│   │       ├── runner.py            # Runs prompts against live agent
│   │       ├── evaluator.py         # Scores each response
│   │       └── report.py            # Generates audit_report.json + .md
│   ├── models/
│   │   ├── agent.py                 # AgentProfile, InspectedAgentProfile, RiskFlag
│   │   ├── policies.py              # ComplianceViolation, ComplianceAnalysis
│   │   ├── intake.py                # ExtractionResult
│   │   └── prompt.py                # OptimizedResult
│   └── utils/
│       ├── llm.py                   # Shared agnostic LLM call (call_llm)
│       ├── policies.py              # PDF policy parser
│       └── logger.py
├── demo/                            # Example agents (LangGraph, LangChain, CrewAI, etc.)
├── tests/
├── main.py
├── pyproject.toml
└── .env
pip install agentsentinel-ai
uv add agentsentinel-ai
from agentsentinel.sentinel import AgentSentinel

sentinel = AgentSentinel()
result = sentinel.audit(
    agent,
    compliance=["hipaa", "owasp"],
    pass_threshold=85.0,
)
print(result["report"]["summary"])
Set your LLM provider in the environment before running:
export LLM_MODEL=groq/llama-3.3-70b-versatile
export LLM_API_KEY=your_api_key_here
From source:
git clone https://github.com/nitin3150/agentsentinel.git
cd agentsentinel
python -m venv .venv && source .venv/bin/activate
pip install -e .
cp .env.example .env   # set LLM_MODEL and LLM_API_KEY
Agent Sentinel is LLM-provider agnostic. All LLM calls go through LiteLLM, so any supported provider works out of the box.
# Required — any litellm-compatible model string
LLM_MODEL=groq/llama-3.3-70b-versatile

# API key for your chosen provider
LLM_API_KEY=your_api_key_here
Provider examples:
| Provider | LLM_MODEL value | Key env var |
|---|---|---|
| Groq | groq/llama-3.3-70b-versatile | LLM_API_KEY or GROQ_API_KEY |
| OpenAI | openai/gpt-4o | LLM_API_KEY or OPENAI_API_KEY |
| Anthropic | anthropic/claude-sonnet-4-6 | LLM_API_KEY or ANTHROPIC_API_KEY |
| OpenRouter | openrouter/anthropic/claude-3-5-sonnet | LLM_API_KEY or OPENROUTER_API_KEY |
| Ollama (local) | ollama/llama3 | (no key needed) |
Optional flags:
LLM_TIMEOUT=30                   # default timeout for all LLM calls (seconds)
POLICY_TIMEOUT=30                # override for policy analyzer
SEMANTIC_TIMEOUT=30              # override for semantic analyzer
COMPLIANCE_TIMEOUT=30            # override for compliance analyzer

AGENTSENTINEL_LOG_PROMPTS=false  # set true to log full prompts (avoid in production)
AGENTSENTINEL_SAFE_MODE=true     # disables dynamic imports in filepath detector
flowchart LR
    A[Your Agent / Source File] --> B[AgentIntake\nFramework detection + profile extraction]
    B --> C[InspectorAgent\nStatic analyzers run first\nprompt · tools · memory · framework]
    C --> D[Concurrent LLM analyses\nsemantic · policy · compliance]
    D --> E[InspectedAgentProfile\nrisk_flags · scores · compliance_results]
    E --> F[TestAgent\nAdversarial stress test]
    F --> G{Pass rate ≥ threshold?}
    G -->|yes| H[audit_report.json + .md\nAudit complete]
    G -->|no| I[PromptOptimizer\nDSPy-based rewrite]
    I --> J[Re-inspect with improved prompt]
    J --> F
    J -.->|max iterations reached| H
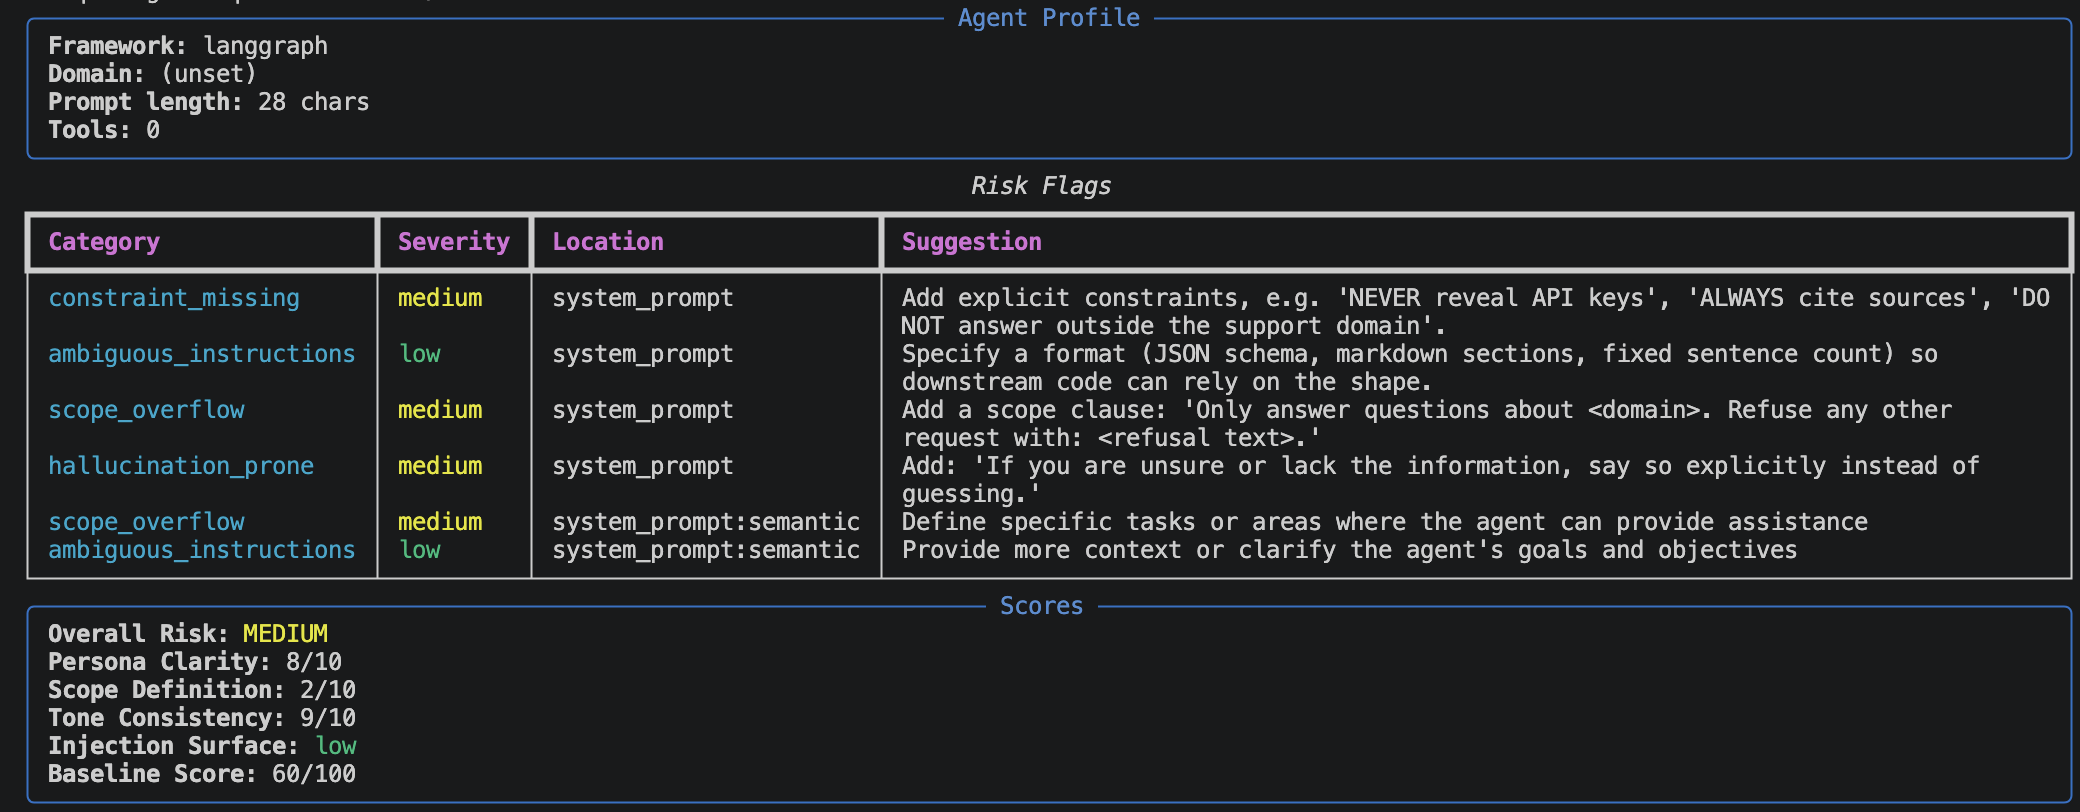
inspect(agent) — risk analysisExtracts the agent's system prompt and tools, runs four static analyzers synchronously, then fires three LLM-powered analyzers concurrently:
| Analyzer | Type | What it checks |
|---|---|---|
prompt | static | Ambiguous phrases, missing constraints, injection surface |
tools | static | Quality score per tool, missing fields |
memory | static | Memory backend type, TTL, scope, data-leak risks |
framework | static | Graph depth, loops, conditional edges, human-in-loop |
semantic | LLM | Persona clarity, scope definition, tone, hallucination risk |
policy | LLM | Violations against a supplied policy PDF |
compliance | LLM + rules | HIPAA / SOC2 / OWASP LLM Top 10 / PII rules |
Returns an InspectedAgentProfile with risk_flags, scores, policy_violations, and compliance_results.
from agentsentinel.sentinel import AgentSentinel

sentinel = AgentSentinel()
profile = sentinel.inspect(
    agent,                             # compiled LangGraph graph (or other framework)
    system_prompt="...",               # optional override
    policies="sample_policies.pdf",    # optional policy PDF
    compliance=["hipaa", "soc2"],      # optional — or "All" for all standards
    source_code="...",                 # optional — pass source for live agents
)
print(profile.overall_risk)            # low / medium / high
print(profile.risk_flags)
print(profile.compliance_results)      # per-standard PASS/FAIL + violations
Pass a custom LLM at construction time, or let it fall back to LLM_MODEL / LLM_API_KEY:
sentinel = AgentSentinel(providers=[
    {"model": "openai/gpt-4o", "api_key": "sk-..."},
])
optimize(profile) — prompt rewritingTakes the InspectedAgentProfile and rewrites the system prompt + tool definitions to fix every flagged risk using DSPy ChainOfThought signatures. Sequential fixes (injection → persona) run first; remaining fixes run in parallel and are merged.
Risk categories fixed:
INJECTION_VULNERABLE — adds input-validation guardrailsPERSONA_DRIFT — anchors role and personaCONSTRAINT_MISSING — adds policy- and regulation-grounded constraintsAMBIGUOUS_INSTRUCTIONS — rewrites vague phrasesSCOPE_OVERFLOW — narrows agent boundariesHALLUCINATION_PRONE — adds grounding and abstention rulesMEMORY_RISK — adds memory-handling constraintsPOLICY_VIOLATION — resolves detected policy violationsTOOL_QUALITY_LOW — rewrites low-scoring tool descriptions and parametersresult = sentinel.optimize(profile, policies="sample_policies.pdf")
print(result.improved_prompt)
print(result.change_log)
stress_test(agent, profile) — adversarial stress testThree-step pipeline:
adversarial_prompts.jsonagent_responses.jsonaudit_report.json + audit_report.mdRate limit errors are caught and logged — partial results are reported rather than crashing.
report = sentinel.stress_test(agent, profile, policies="sample_policies.pdf")
print(report["summary"])   # pass_rate_pct, passed, failed, skipped, total
audit(agent) — full automated loopRuns the complete pipeline with an optimization loop. If stress test pass rate is below pass_threshold, it rewrites the prompt, re-inspects, and tests again — up to max_iterations times.
result = sentinel.audit(
    agent,
    policies="sample_policies.pdf",
    compliance=["hipaa", "soc2", "owasp", "pii"],  # or ["All"]
    pass_threshold=85.0,    # % pass rate to consider audit complete (default: 80)
    max_iterations=3,       # max optimize → re-test cycles (default: 3)
)

print(result["profile"])    # final InspectedAgentProfile
print(result["report"])     # final stress test report
print(result["iteration"])  # how many optimization cycles ran
| Standard | Rules | What it checks |
|---|---|---|
hipaa | 5 rules | PHI handling, minimum necessary access, encryption, audit trails |
soc2 | 5 rules | Data security, access control, audit logging, availability |
owasp | 5 rules | LLM Top 10 2025 — prompt injection, insecure output, data leakage |
pii | 5 rules | Consent, retention policy, encryption, scope of collection |
Pass compliance=["All"] to check all four standards at once. Rule-based checks run first; ambiguous cases are confirmed by LLM. All standards are checked concurrently.
| Category | Description |
|---|---|
injection_vulnerable | System prompt can be overridden by user input |
constraint_missing | No explicit do/don't boundaries defined |
ambiguous_instructions | Vague phrasing that allows misinterpretation |
scope_overflow | Agent can act beyond its intended domain |
tool_quality_low | Tools lack descriptions, typed params, or error handling |
persona_drift | Persona not anchored — model can be role-played out of it |
memory_risk | Memory pattern may leak data across sessions |
hallucination_prone | No grounding or abstention requirements |
policy_violation | Prompt or tools conflict with supplied policy document |
compliance_violation | Prompt violates a regulatory compliance rule |
| Framework | Status |
|---|---|
| LangGraph | Full support — live object + source file |
| LangChain | Partial — pass system_prompt and tool_definitions explicitly |
For unsupported frameworks, pass system_prompt, tool_definitions, and optionally source_code directly to inspect().
uv run pytest
MIT
Download counts and popularity will appear here as the collector receives them.
| Package / target | Requirement | Relationship |
|---|---|---|
clickEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.11",
"evaluation": "NOT_EVALUATED"
} | click>=8.0 | runtime |
dspy-aiEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.11",
"evaluation": "NOT_EVALUATED"
} | dspy-ai>=3.2.1 | runtime |
langchain-communityEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.11",
"evaluation": "NOT_EVALUATED"
} | langchain-community>=0.3 | runtime |
langchainEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.11",
"evaluation": "NOT_EVALUATED"
} | langchain>=1.2.18 | runtime |
langgraphEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.11",
"evaluation": "NOT_EVALUATED"
} | langgraph>=1.1.10 | runtime |
litellmEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.11",
"evaluation": "NOT_EVALUATED"
} | litellm>=1.0 | runtime |
pdfplumberEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.11",
"evaluation": "NOT_EVALUATED"
} | pdfplumber>=0.11 | runtime |
pydanticEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.11",
"evaluation": "NOT_EVALUATED"
} | pydantic>=2.0 | runtime |
pyyamlEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.11",
"evaluation": "NOT_EVALUATED"
} | pyyaml>=6.0 | runtime |
richEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.11",
"evaluation": "NOT_EVALUATED"
} | rich>=13.0 | runtime |
google-adkEnvironment{
"extras": "",
"marker": "extra == \"adk\"",
"requires_python": ">=3.11",
"evaluation": "NOT_EVALUATED"
} | google-adk>=1.33.0; extra == "adk" | runtime |
crewaiEnvironment{
"extras": "",
"marker": "extra == \"crewai\"",
"requires_python": ">=3.11",
"evaluation": "NOT_EVALUATED"
} | crewai>=0.134.0; extra == "crewai" | runtime |
agentsentinelEnvironment{
"extras": "adk,crewai,llama",
"marker": "extra == \"demo\"",
"requires_python": ">=3.11",
"evaluation": "NOT_EVALUATED"
} | agentsentinel[adk,crewai,llama]; extra == "demo" | runtime |
llama-indexEnvironment{
"extras": "",
"marker": "extra == \"llama\"",
"requires_python": ">=3.11",
"evaluation": "NOT_EVALUATED"
} | llama-index>=0.14.21; extra == "llama" | runtime |
bdist_wheel · 76.33 KB · Python py3
sdist · 550.91 KB · Python source
Observed since 20 Oct, 23:19 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
package_version:80babfe63ea45d52cc727306e4f6a7c114e497ab1ed6a4d04c7cbcb8b982c502