
 Repository
Current collected state Current
Observed since 21 Oct, 10:07 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
aicertify
Open-source compliance-as-code for AI systems: evaluate declared facts and measured evidence with versioned OPA/Rego policies and generate portable PDF, Markdown, JSON, or HTML reports.

Open-source compliance-as-code for AI systems: one contract, executable OPA/Rego policies, and reproducible evidence across the EU AI Act, UK AI governance, NIST AI RMF, and more.




📦 Full documentation, forkable examples, contributing guides, translations, and 92 GOPAL/Rego policies live in the GitHub repository.
AICertify is the open execution and evidence layer for AI governance. Describe an AI system in a contract, supply organisation-known facts, attach or compute measured metrics, evaluate that evidence against versioned GOPAL policies through Open Policy Agent, and generate dated PDF, Markdown, JSON, or HTML reports.
The goal is simple: move from “we have an AI policy” to evidence another engineer, auditor, or risk team can inspect and reproduce.
Use AICertify to:
AICertify is part of the Open Policy Agent ecosystem, using the same policy engine widely used for Kubernetes admission, service authorisation, and infrastructure policy.
⭐ Building AI governance as code? Star the GitHub repo so other practitioners can find it.
# 1. Install AICertify (~3–5 min on first install; pulls langchain + transformers)
pip install aicertify

# 2. Install the OPA binary, one-time (~80 MB)
curl -L https://openpolicyagent.org/downloads/latest/opa_linux_amd64 -o /usr/local/bin/opa && sudo chmod +x /usr/local/bin/opa

# 3. Run the bundled demo (no contract file or API keys)
aicertify demo
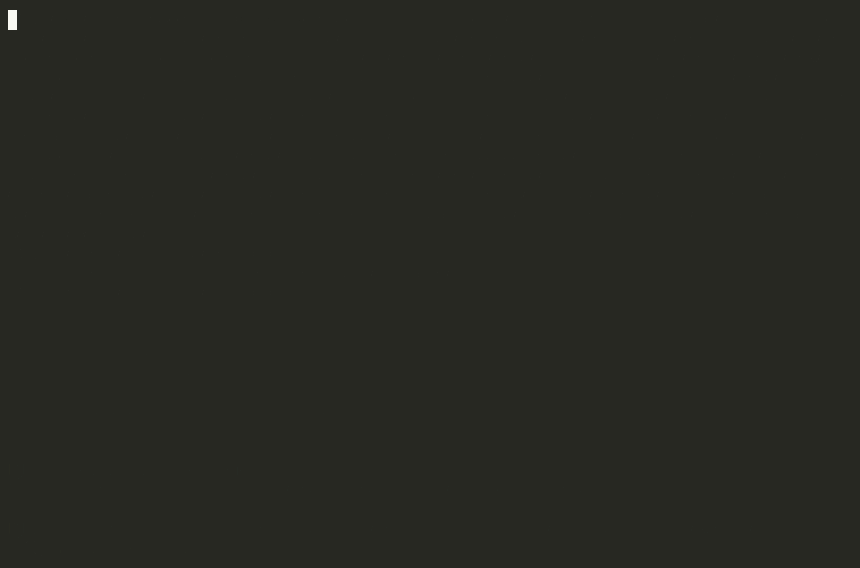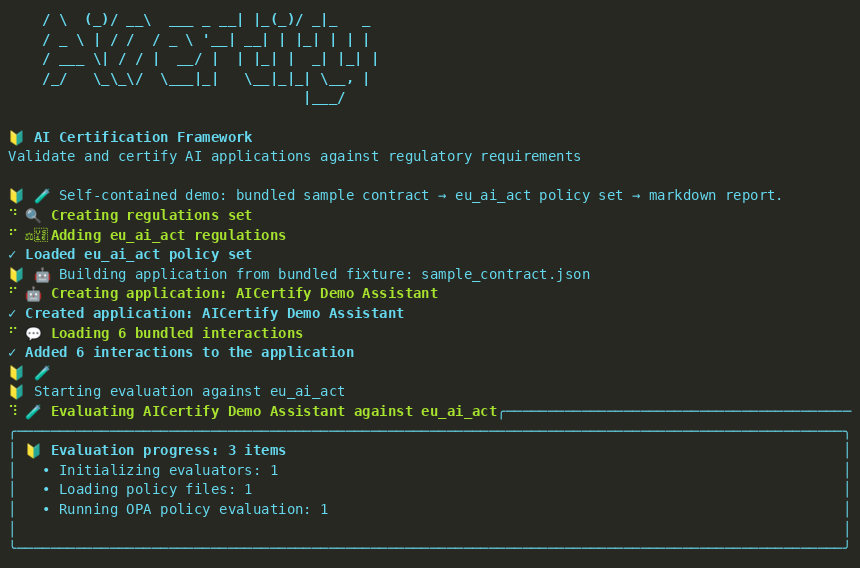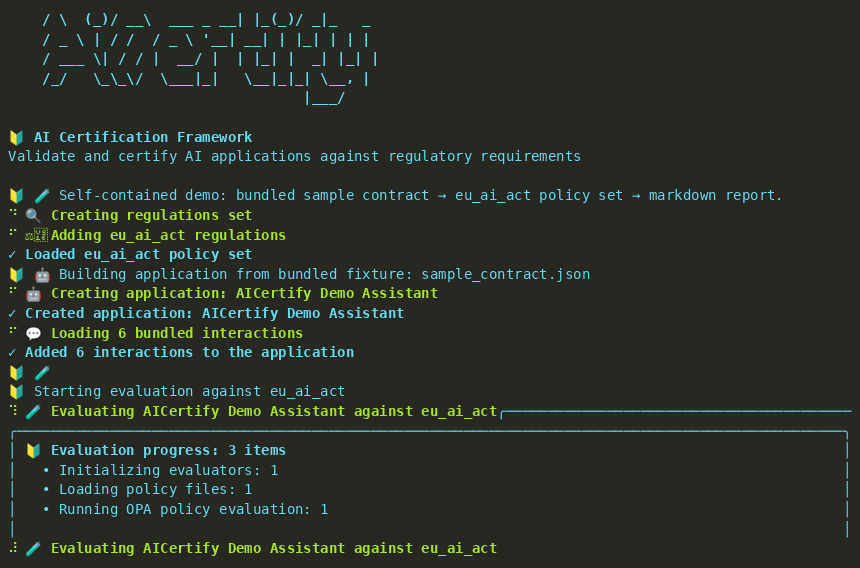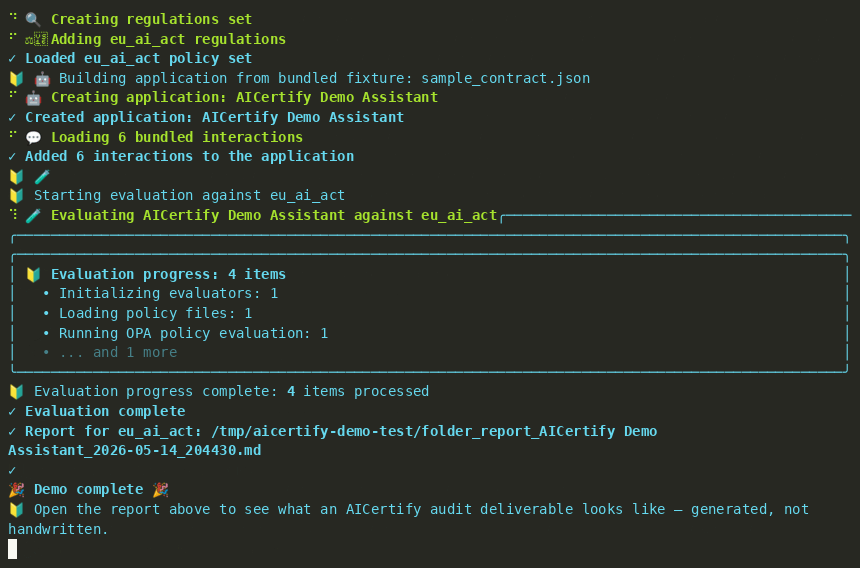
aicertify demo loads a bundled sample contract, evaluates it against the EU AI Act policy set via OPA, and writes aicertify_demo_report.md. The sample intentionally contains no compliance declarations, so evidence-dependent policies deny; this demonstrates fail-closed behavior rather than an artificially green demo.
For richer evaluations (LangFair fairness metrics, DeepEval content-safety scoring, PDF reports), see examples/quickstart.py and the forkable example bots, each of which ships an input_contract.json, a policy_config.yaml, and a run.py.
from aicertify import regulations, application

# 1. Pick the regulations you want to certify against
regs = regulations.create("my_regulations")
regs.add("eu_ai_act")

# 2. Wrap your AI app
app = application.create(
    name="customer-support-bot",
    model_name="gpt-4o",
    model_version="2024-08-06",
)

# 3. Feed it real interactions
app.add_interaction(
    input_text="I want a refund for my order",
    output_text="I can help with that. Could you share your order number?",
)

# 4. Evaluate and get reports back
await app.evaluate(regulations=regs, report_format="pdf", output_dir="reports")
That's the whole loop. Contract → evidence → policy evaluation → report.
Evaluation libraries such as Fairlearn and AI Fairness 360 measure specific properties. Governance platforms address broader inventory and workflow needs. AICertify provides the open execution layer between them: combine declared system facts with measured evidence, run inspectable GOPAL/Rego policies through OPA, and emit portable, dated results.
The differentiator is reproducibility: inspect the rules, pin versions, run locally or air-gapped, review changes in Git, and retain the evidence outside a vendor account.
See the full positioning in docs/why-aicertify.md on GitHub.
| AICertify | Fairlearn / AIF360 | MS RAI Toolbox | Governance SaaS | |
|---|---|---|---|---|
| Open source | ✅ Apache 2.0 | ✅ MIT | ✅ MIT | Varies |
| Local / air-gapped execution | ✅ | ✅ | ✅ | Varies |
| Named governance / regulatory policy sets | ✅ via GOPAL | ❌ (measurement library) | ❌ (toolkit) | Common |
| Inspectable policy-as-code | ✅ OPA / Rego | ❌ | ❌ | Varies |
| Industry-specific policy coverage | ✅ | ❌ | ❌ | Varies |
| Portable dated reports | ✅ PDF / MD / JSON / HTML | ❌ | Partial | Common |
| Custom policy logic | ✅ Rego | ❌ | N/A | Product-specific |
If you already use OPA, AICertify gives you the AI-application context layer OPA was missing. You bring your AI app; AICertify captures the interactions, feeds them through the OPA engine against AI-specific Rego policies sourced from gopal, and emits audit-ready evidence.
The whole stack is policy-as-code: the same workflow you already use for Kubernetes admission, microservice authorisation, and infrastructure governance.
Copy any of these and substitute your own contract:
Each example ships an input_contract.json, policy_config.yaml, sample_interactions.json, an expected_report.md, and a run.py you can execute directly.
You don't have to install anything to see what AICertify produces. A sample pre-generated PDF is in the repo:
examples/outputs/loan_evaluation/Apache 2.0, see the LICENSE file.
Download counts and popularity will appear here as the collector receives them.
| Package / target | Requirement | Relationship |
|---|---|---|
PygmentsEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | Pygments>=2.20.0 | runtime |
aiohttpEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | aiohttp>=3.14.1 | runtime |
banksEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | banks>=2.4.2 | runtime |
blackEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | black<27.0.0,>=26.3.1 | runtime |
brotliEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | brotli>=1.2.0 | runtime |
colorlogEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | colorlog<7.0.0,>=6.9.0 | runtime |
cryptographyEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | cryptography>=50.0.0 | runtime |
datasetsEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | datasets<4.0.0,>=3.3.2 | runtime |
deepevalEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | deepeval<3.0.0,>=2.4.8 | runtime |
fastapiEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | fastapi<1.0,>=0.119.0 | runtime |
filelockEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | filelock>=3.20.3 | runtime |
h11Environment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | h11>=0.14.0 | runtime |
huggingface-hubEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | huggingface-hub<2.0,>=0.34.0 | runtime |
langchainEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | langchain>=1.3.9 | runtime |
langchain-communityEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | langchain-community>=0.3.27 | runtime |
langchain-coreEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | langchain-core>=1.2.22 | runtime |
langchain-openaiEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | langchain-openai>=1.1.14 | runtime |
langchain-text-splittersEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | langchain-text-splitters>=1.1.2 | runtime |
langfairEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | langfair<1.0,>=0.8.0 | runtime |
langgraph-checkpointEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | langgraph-checkpoint>=4.1.1 | runtime |
langgraph-sdkEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | langgraph-sdk>=0.3.15 | runtime |
langsmithEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | langsmith>=0.8.18 | runtime |
markdownEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | markdown<4.0,>=3.8.1 | runtime |
marshmallowEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | marshmallow>=3.26.2 | runtime |
nltkEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | nltk>=3.10.0 | runtime |
opa-python-clientEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | opa-python-client>=0.1.0 | runtime |
orjsonEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | orjson>=3.11.6 | runtime |
pandasEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | pandas>=2.2.0 | runtime |
pillowEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | pillow>=12.3.0 | runtime |
protobufEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | protobuf<6,>=5.29.6 | runtime |
pyasn1Environment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | pyasn1>=0.6.4 | runtime |
pycaresEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | pycares<5.0.0,>=4.9.0 | runtime |
pydanticEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | pydantic<3.0.0,>=2.10.6 | runtime |
pydantic-aiEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | pydantic-ai<0.0.25,>=0.0.24 | runtime |
pydantic-settingsEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | pydantic-settings>=2.14.2 | runtime |
pypdfEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | pypdf>=6.15.0 | runtime |
pytestEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | pytest<10.0.0,>=9.0.3 | runtime |
python-dotenvEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | python-dotenv>=1.2.2 | runtime |
reportlabEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | reportlab<5.0.0,>=4.3.1 | runtime |
requestsEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | requests<3.0.0,>=2.33.0 | runtime |
richEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | rich<14.0.0,>=13.8.0 | runtime |
sentencepieceEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | sentencepiece>=0.2.1 | runtime |
setuptoolsEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | setuptools>=83.0.0 | runtime |
soupsieveEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | soupsieve>=2.8.4 | runtime |
starletteEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | starlette>=1.3.1 | runtime |
torchEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | torch>=2.13.0 | runtime |
transformersEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | transformers>=5.5.0 | runtime |
urllib3Environment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | urllib3>=2.7.0 | runtime |
uvicornEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | uvicorn<0.35.0,>=0.34.0 | runtime |
virtualenvEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | virtualenv>=20.36.1 | runtime |
yfinanceEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.13,>=3.12",
"evaluation": "NOT_EVALUATED"
} | yfinance<0.3.0,>=0.2.54 | runtime |
bdist_wheel · 832.25 KB · Python py3
sdist · 588.27 KB · Python source
Shared repository data · GitHub
Shared repository data · GitHub
Observed since 21 Oct, 10:07 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
package_version:a8bc5800bcf02368b97fb38b5c6f082effbc04cfca5b6b6b079e729f0453044c