
 Repository
Current collected state Current
Observed since 21 Oct, 11:17 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
aimd-tool
Context preparation tool for LLM workflows.
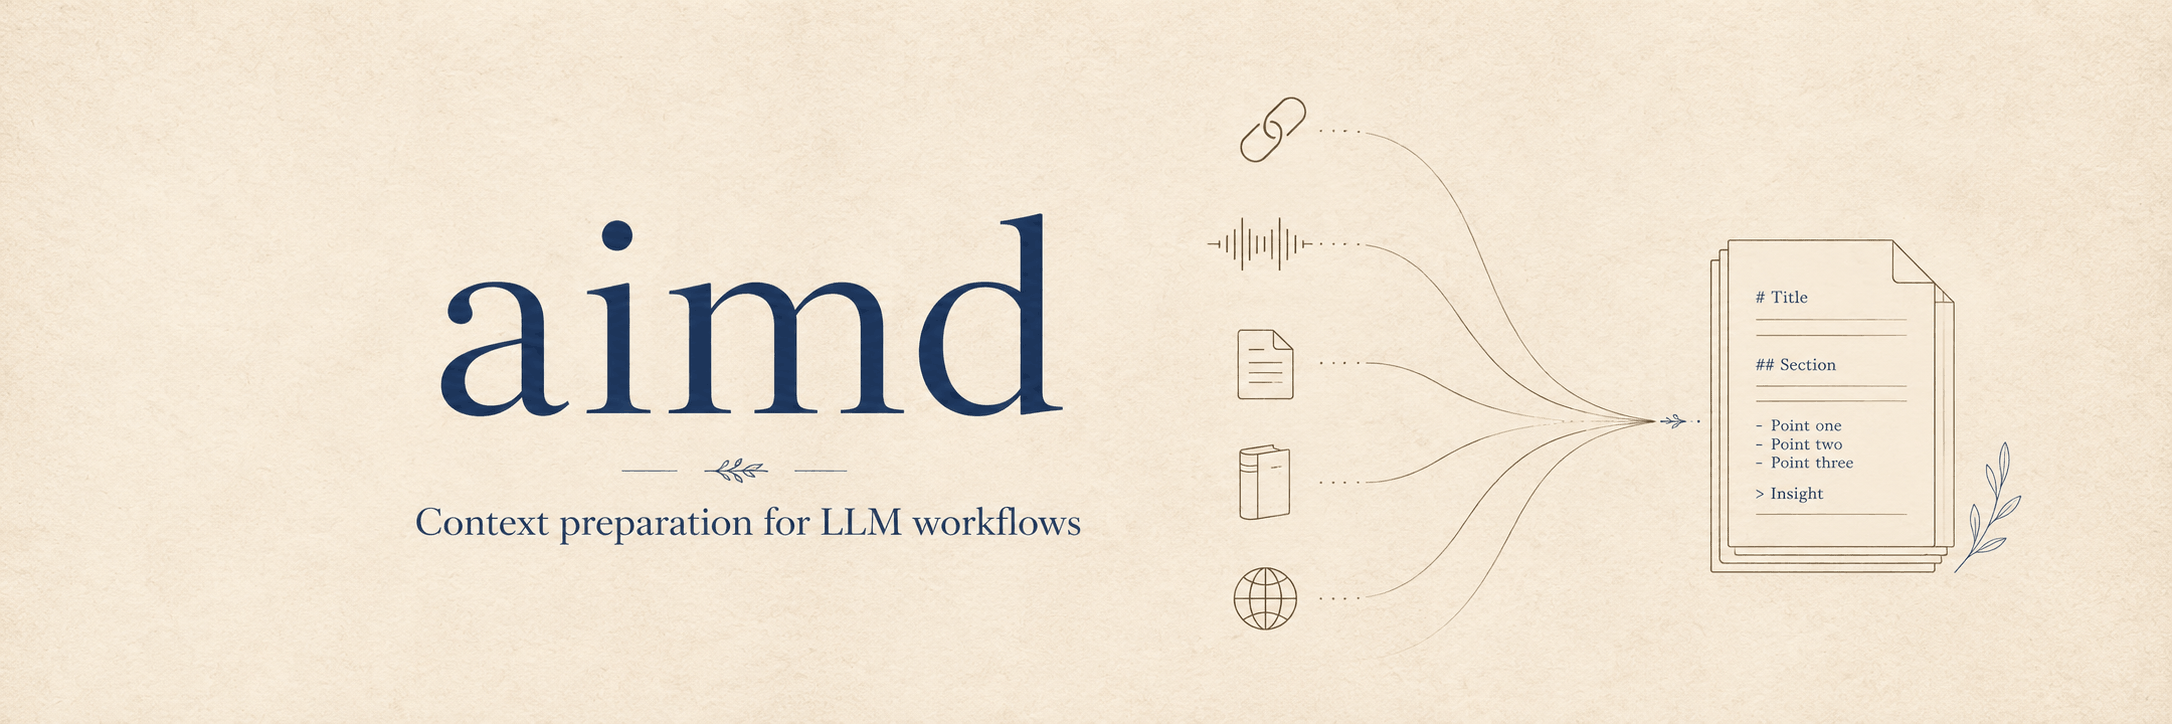


Prepare LLM-ready context from URLs, audio/video, and documents.
aimd gives you one command that auto-detects input type, extracts or transcribes the content, converts it to Markdown, and returns a chunked text context suitable for downstream AI workflows.
aimd.plugins.url: yt-dlp transcript URLs such as podcasts, YouTube, and Bilibili, plus opt-in readable HTML extraction through Defuddle.aimd.plugins.asr: local audio/video transcription with mlx-audio by default on Apple Silicon, Qwen3-ASR through native Transformers on CUDA, or an opt-in OpenAI-compatible remote endpoint.mlx-audio or Qwen3-ASR through Transformers.aimd.plugins.doc plugin.mlx-vlm on macOS/Apple Silicon, CUDA VLM OCR models through Transformers on Linux, or an opt-in remote Unlimited-OCR endpoint.aimd), HTTP API (aimd-api), and MCP server (aimd-mcp).Install the CLI after release:
uv tool install aimd-tool
aimd --help
Install from GitHub main before a release:
uv tool install --force \
  "aimd-tool @ git+https://github.com/shuuul/aimd.git@main"
Install the full tool set from GitHub, including the API and MCP runtime dependencies:
uv tool install --force \
  "aimd-tool[all] @ git+https://github.com/shuuul/aimd.git@main"
Install API/MCP dependencies from PyPI when needed:
# HTTP API + MCP server
uv tool install "aimd-tool[all]"

# Or install into an existing Python environment
uv pip install "aimd-tool[all]"
The public PyPI release is intentionally a single distribution (aimd-tool). The installed command remains aimd.
From a source checkout, use the project directly:
git clone https://github.com/shuuul/aimd.git
cd aimd
uv sync --dev
uv run aimd --help
Platform notes:
mlx-audio; this remains the default backend.mlx-vlm on Python 3.12+ and downloads OCR model weights on first use.Qwen/Qwen3-ASR-*-hf (or legacy Qwen/Qwen3-ASR-*) transcription model IDs use native Transformers Qwen3-ASR (transformers>=5.14.1); on macOS this is an opt-in MPS path, not the default.AIMD_ASR_BASE_URL or AIMD_OCR_BASE_URL uses an OpenAI-compatible remote service and skips local MLX/CUDA model loading for that modality.aimd.plugins.doc MarkItDown plugin; EPUB uses a custom ZIP/spine pipeline for stable chapter ordering and image extraction, while other Pandoc-supported formats go through the Pandoc CLI directly.# Auto-detect input type
aimd audio.mp3
aimd "https://youtube.com/watch?v=..."
aimd document.epub
aimd notes.txt
aimd scan.pdf
aimd page.png
# Common options
aimd audio.mp3 --output transcript.md
aimd audio.wav --language zh
aimd scan.pdf --task ocr --start 0 --end 2
aimd "https://youtube.com/watch?v=..." --cookies-from-browser chrome
aimd "https://youtube.com/watch?v=..." --raw-transcript
Remote inference is opt-in. Base URLs may include /v1; aimd adds it when a
bare server URL is supplied. The server controls weight precision, so
--precision is ignored with a warning in remote mode.
AIMD_ASR_BASE_URL=http://192.168.100.114:8000 \
AIMD_ASR_MODEL=Qwen3-ASR-1.7B \
  aimd audio.wav --model qwen3-asr-1.7b

AIMD_OCR_BASE_URL=http://192.168.100.114:10000 \
AIMD_OCR_MODEL=Unlimited-OCR \
  aimd scan.png --model unlimited-ocr
Equivalent CLI options are --asr-base-url, --asr-model, --asr-api-key,
--ocr-base-url, --ocr-model, and --ocr-api-key. HTTP API request fields
and MCP tool parameters use the same underscore names. API keys default to
not-needed for unauthenticated LAN services.
aimd interview.m4a
aimd lecture.mp3
aimd audio.wav --language zh
aimd audio.wav --model mlx-community/Qwen3-ASR-1.7B-4bit
Backend selection is automatic:
| Platform | Backend | Notes |
|---|---|---|
| macOS Apple Silicon | MLX | Uses mlx-audio when available. |
| CUDA-capable non-Darwin | Transformers | Uses Qwen3-ASR through Transformers when CUDA is available. |
Passing an explicit transcription model ID such as Qwen/Qwen3-ASR-0.6B-hf (or the legacy alias Qwen/Qwen3-ASR-0.6B) opts into the native Transformers Qwen3-ASR backend, including on macOS/MPS. The automatic macOS backend remains MLX because the quantized MLX models are usually faster and lower-maintenance on Apple Silicon.
--model is interpreted by the platform-selected backend. The table below lists the only supported model aliases and IDs. Arbitrary Hugging Face model IDs are rejected so that model/runtime compatibility stays explicit.
| Task | Platform/backend | --model value | Upstream model / runtime | Default | Notes |
|---|---|---|---|---|---|
| Transcription | macOS Apple Silicon / MLX | mlx-community/Qwen3-ASR-1.7B-4bitmlx-community/Qwen3-ASR-1.7B-6bitmlx-community/Qwen3-ASR-1.7B-8bitmlx-community/Qwen3-ASR-1.7B-bf16 | mlx-audio STT | 4bit | Qwen3-ASR 1.7B, all supported MLX precisions. |
| Transcription | macOS Apple Silicon / MLX | mlx-community/Qwen3-ASR-0.6B-4bitmlx-community/Qwen3-ASR-0.6B-6bitmlx-community/Qwen3-ASR-0.6B-8bitmlx-community/Qwen3-ASR-0.6B-bf16 | mlx-audio STT | No | Qwen3-ASR 0.6B, all supported MLX precisions. |
| Transcription | CUDA-capable non-Darwin / Transformers; explicit opt-in on macOS/MPS | Qwen/Qwen3-ASR-1.7B-hf | Native Transformers Qwen3-ASR | Yes on CUDA Transformers | Default CUDA Transformers ASR model; explicit opt-in on macOS. Legacy Qwen/Qwen3-ASR-1.7B resolves here. |
| Transcription | CUDA-capable non-Darwin / Transformers; explicit opt-in on macOS/MPS | Qwen/Qwen3-ASR-0.6B-hf | Native Transformers Qwen3-ASR | No | Lower-memory Qwen3-ASR option; explicit opt-in on macOS. Legacy Qwen/Qwen3-ASR-0.6B resolves here. |
| OCR | macOS Apple Silicon / mlx-vlm | unlimited_ocr (default)unlimited_ocr_4bit / unlimited_ocr_6bit / unlimited_ocr_8bit / unlimited_ocr_bf16mlx-community/Unlimited-OCR-4bitmlx-community/Unlimited-OCR-6bitmlx-community/Unlimited-OCR-8bitmlx-community/Unlimited-OCR-bf16 | mlx-vlm | Yes | Unlimited-OCR MLX checkpoints. The default alias resolves to mlx-community/Unlimited-OCR-4bit; each page uses single-image gundam mode. |
| OCR | macOS Apple Silicon / mlx-vlm | glm_ocr / glm-ocr (default)mlx-community/GLM-OCR-4bitmlx-community/GLM-OCR-6bitmlx-community/GLM-OCR-8bitmlx-community/GLM-OCR-bf16 | mlx-vlm | No | GLM-OCR MLX checkpoints; the default alias resolves to the 4-bit checkpoint. |
| OCR | Linux/CUDA / Transformers | unlimited_ocr, unlimited-ocr, baidu/Unlimited-OCR | baidu/Unlimited-OCR | Yes | Default Linux/CUDA OCR model. Uses Baidu Unlimited-OCR remote code with CUDA and save_results=True. |
| OCR | Linux/CUDA / Transformers | glm_ocr, glm-ocr, zai-org/GLM-OCR | zai-org/GLM-OCR | No | May require a newer Transformers build than the PyPI baseline. |
aimd "https://www.youtube.com/watch?v=..."
aimd "https://www.bilibili.com/video/BV..."
aimd "https://www.xiaoyuzhoufm.com/episode/..."
Subtitles are simplified to plain text by default. Use --raw-transcript to preserve SRT/VTT formatting.
When a URL has no subtitles and audio transcription is used, aimd injects the page metadata (title, author, description, tags, chapters) as ASR context so proper nouns and names are recognized more accurately. This is enabled by default; disable it with --no-context, or supply your own biasing text with --context (works for local audio files too):
aimd "https://youtube.com/watch?v=..." --no-context
aimd interview.mp3 --context "Vocabulary: Qwen, MLX, LoRA."
For authenticated or restricted content:
aimd "https://youtube.com/watch?v=..." --cookies cookies.txt
aimd "https://www.bilibili.com/video/BV..." --cookies-from-browser "chrome:default"
When no cookie option is provided, URL extraction may try available browser cookie sources before falling back to unauthenticated access. Keep this behavior because it makes restricted media work out of the box, but explicit cookie options should fail fast when invalid. Transcript requests should also fail when subtitles and audio transcription both produce no text, instead of returning metadata-only Markdown as a successful transcript.
aimd document.epub
aimd document.pdf
aimd notes.md
aimd document.epub --output output.md
Asset-bearing documents such as EPUB are expanded into a structured output directory:
document_name/
├── document_name.md
├── chapters/
└── images/
The EPUB pipeline preserves spine order, extracts images, converts chapters through Pandoc, and applies Markdown cleanup. Other Pandoc-supported formats are converted by Pandoc directly. Text-layer PDFs are converted locally by pdf-inspector through the same document plugin, producing structured Markdown (headings, lists, tables) without OCR. Pandoc does not support MOBI/AZW3 as input formats, so AIMD no longer advertises them as supported document inputs.
aimd page.png
aimd scan.pdf                                  # OCR if no extractable PDF text or broken font encoding is found
aimd scan.pdf --task ocr                       # Force OCR; default model is unlimited_ocr
aimd scan.pdf --model unlimited_ocr_bf16       # macOS MLX full-precision Unlimited-OCR
aimd scan.pdf --model glm_ocr                  # GLM-OCR on macOS or Linux/CUDA
aimd scan.pdf --start 0 --end 2                # 0-based inclusive OCR PDF page range
OCR keeps the same Markdown/TextContext output contract as transcript and convert tasks. Images route to OCR automatically. PDF routing is probed with pdf-inspector: PDFs with a clean extractable text layer route to normal document conversion, while scanned PDFs and PDFs whose text layer has broken font encodings (pdf-inspector has_encoding_issues, undecodable CID fonts) route to OCR automatically. Linux/CUDA defaults to baidu/Unlimited-OCR through the Transformers backend. macOS uses mlx-vlm>=0.6.4 and defaults to mlx-community/Unlimited-OCR-4bit; unlimited_ocr_4bit, unlimited_ocr_6bit, unlimited_ocr_8bit, and unlimited_ocr_bf16 select the other MLX checkpoints. Unlimited-OCR uses single-image gundam mode (cropping=True, image_size=640, prompt document parsing.), Baidu's sliding-window no-repeat n-gram guard (ngram_size=35, window=128), and max_tokens=8192. GLM-OCR is available through the four mlx-community/GLM-OCR-* MLX checkpoints on macOS and zai-org/GLM-OCR on Linux/CUDA. Long PDFs are OCR'd page-by-page so page boundaries stay reliable. Unsupported model IDs are rejected.
aimd uses MarkItDown with plugins enabled. The bundled aimd.plugins.url, aimd.plugins.asr, aimd.plugins.doc, and aimd.plugins.ocr modules register standard markitdown.plugin entry points, so installing aimd-tool also installs URL transcript/readable HTML, local audio/video ASR, Pandoc document, and OCR converters.
You can also use the plugins from MarkItDown directly:
markitdown --list-plugins
markitdown --use-plugins document.epub -o doc.md
markitdown --use-plugins audio.mp3 -o transcript.md
The Defuddle-backed aimd.plugins.url readable HTML converter is opt-in so normal HTML conversion does not require Node.js/npm:
from markitdown import MarkItDown

result = MarkItDown(enable_plugins=True).convert("article.html", defuddle=True)
print(result.markdown)
Run the API server:
aimd-api
Endpoints:
curl http://127.0.0.1:8000/healthz

curl -X POST http://127.0.0.1:8000/v1/process \
  -H "Content-Type: application/json" \
  -d '{
    "input_source": "https://www.youtube.com/watch?v=...",
    "language": "en"
  }'

curl -X POST http://127.0.0.1:8000/v1/process \
  -H "Content-Type: application/json" \
  -d '{
    "input_source": "scan.pdf",
    "task_type": "ocr",
    "start": 0,
    "end": 2
  }'
The process response includes both lossless markdown for display/persistence and
chunk_list for context-window consumers. asset_base_uri is the URL or local file:
directory (with a trailing slash) against which relative Markdown resources resolve; it
is null for local transcriptions without associated resources.
Document conversions that extract assets return a canonical output_dir beside the
source file. That directory and its Markdown/assets are durable caller-owned output: AIMD
does not remove them when a request or job ends. An output_file request is ignored for
such conversions because moving only the Markdown would break its relative asset links.
For results without output_dir, requested output files are written byte-for-byte from
markdown; chunk_list is never recombined for persistence.
OpenAPI docs are available at /docs and /redoc.
The asynchronous desktop contract is POST /v1/jobs, GET /v1/jobs/{id}, resumable
GET /v1/jobs/{id}/events, and cancellation through DELETE /v1/jobs/{id}. See the
local desktop sidecar contract for authenticated launch, loopback,
allow-root, readiness, cancellation, and shutdown requirements.
Run the stdio MCP server:
aimd-mcp
Tools:
healthzprocess_inputprocess_input mirrors the CLI/API flow and accepts options such as input_source, task_type, model, language, start, end, output_file, save_original, cookies, cookies_from_browser, and raw_transcript. For MCP, temporary files are controlled by the AIMD_TEMP_DIR environment variable.
# Optional yt-dlp configuration
export YT_DLP_CONFIG_HOME="/path/to/config"
export YT_DLP_CACHE_DIR="/path/to/cache"

# Optional temporary directory for downloads, transcoding, and document extraction
export AIMD_TEMP_DIR="/path/to/writable/tmp"
You can also pass --temp-dir on the CLI.
uv sync --dev --upgrade
uv run prek --all-files
uv run pytest -q
Useful maintenance commands:
uv run prek autoupdate
uv build
Releases are managed by release-please. Commits to main update a release PR;
merging that PR creates the tag and GitHub Release. The release workflow then builds
the single aimd-tool distribution, smoke-installs it on Linux and macOS, and
publishes it to PyPI.
Project layout:
src/
└── aimd/            # core, interfaces/{cli,api,mcp,output.py}, and bundled MarkItDown plugins
aimd is a single published distribution, aimd-tool. See docs/architecture.md for the full architecture notes and docs/performance.md for performance expectations and measurement guidance.
The package uses MarkItDown as the URL/local-file conversion contract and keeps core as a small interface-independent processing service:
aimd.core.models and aimd.core.process own canonical request/response models, input routing, and processing; ASR/OCR backends are selected internally from the current platform.aimd.core.process.process_input() sends URL and local-file work through MarkItDown(enable_plugins=True).aimd.plugins.url for URL transcript extraction and opt-in Defuddle-backed HTML extraction, aimd.plugins.asr for local audio/video inputs, aimd.plugins.doc for Pandoc-backed documents and pdf-inspector text-layer PDFs, and aimd.plugins.ocr for explicit OCR of images and scanned PDFs.aimd.interfaces.cli:main, aimd.interfaces.api:main, and aimd.interfaces.mcp.app:main; MarkItDown plugin entry points are aimd.plugins.asr, aimd.plugins.url, aimd.plugins.doc, and aimd.plugins.ocr.aimd.plugins.url owns URL extraction: yt-dlp metadata, subtitle download, cookie handling, audio download fallback, and readable HTML extraction. It intentionally keeps automatic browser-cookie probing for convenience, while explicit cookie arguments and transcript/audio fallback failures should surface clear errors. aimd.plugins.asr owns transcription backend selection, model validation, and the local audio/video MarkItDown plugin.aimd.core.process preserves each lossless MarkItDown result on ProcessResult and
separately shapes it into TextContext chunks.aimd.interfaces.output; it is not part of ProcessInput.All processing returns a shared ProcessResult: lossless Markdown and its optional asset
base URI alongside TextContext title, chunks, and split metadata.
Apache-2.0. See LICENSE.
Download counts and popularity will appear here as the collector receives them.
| Package / target | Requirement | Relationship |
|---|---|---|
addictEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.14,>=3.11",
"evaluation": "NOT_EVALUATED"
} | addict>=2.4.0 | runtime |
easydictEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.14,>=3.11",
"evaluation": "NOT_EVALUATED"
} | easydict>=1.13 | runtime |
einopsEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.14,>=3.11",
"evaluation": "NOT_EVALUATED"
} | einops>=0.8.2 | runtime |
loglyEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.14,>=3.11",
"evaluation": "NOT_EVALUATED"
} | logly>=0.2.1 | runtime |
markitdownEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.14,>=3.11",
"evaluation": "NOT_EVALUATED"
} | markitdown<0.2.0,>=0.1.7 | runtime |
matplotlibEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.14,>=3.11",
"evaluation": "NOT_EVALUATED"
} | matplotlib>=3.10.9 | runtime |
mlx-audioEnvironment{
"extras": "",
"marker": "sys_platform == \"darwin\"",
"requires_python": "<3.14,>=3.11",
"evaluation": "NOT_EVALUATED"
} | mlx-audio>=0.4.4; sys_platform == "darwin" | runtime |
mlx-vlmEnvironment{
"extras": "",
"marker": "python_full_version >= \"3.12\" and sys_platform == \"darwin\"",
"requires_python": "<3.14,>=3.11",
"evaluation": "NOT_EVALUATED"
} | mlx-vlm>=0.6.8; python_full_version >= "3.12" and sys_platform == "darwin" | runtime |
pdf-inspectorEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.14,>=3.11",
"evaluation": "NOT_EVALUATED"
} | pdf-inspector>=1.14.2 | runtime |
pillowEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.14,>=3.11",
"evaluation": "NOT_EVALUATED"
} | pillow>=12.3.0 | runtime |
pydanticEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.14,>=3.11",
"evaluation": "NOT_EVALUATED"
} | pydantic>=2.13.4 | runtime |
pymupdfEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.14,>=3.11",
"evaluation": "NOT_EVALUATED"
} | pymupdf>=1.28.0 | runtime |
python-dotenvEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.14,>=3.11",
"evaluation": "NOT_EVALUATED"
} | python-dotenv>=1.2.2 | runtime |
secretstorageEnvironment{
"extras": "",
"marker": "sys_platform == \"linux\"",
"requires_python": "<3.14,>=3.11",
"evaluation": "NOT_EVALUATED"
} | secretstorage>=3.5.0; sys_platform == "linux" | runtime |
torchEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.14,>=3.11",
"evaluation": "NOT_EVALUATED"
} | torch>=2.13.0 | runtime |
torchvisionEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.14,>=3.11",
"evaluation": "NOT_EVALUATED"
} | torchvision>=0.28.0 | runtime |
transformersEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.14,>=3.11",
"evaluation": "NOT_EVALUATED"
} | transformers>=5.14.1 | runtime |
typerEnvironment{
"extras": "",
"marker": null,
"requires_python": "<3.14,>=3.11",
"evaluation": "NOT_EVALUATED"
} | typer>=0.27.0 | runtime |
yt-dlpEnvironment{
"extras": "default",
"marker": null,
"requires_python": "<3.14,>=3.11",
"evaluation": "NOT_EVALUATED"
} | yt-dlp[default]>=2026.7.4 | runtime |
fastapiEnvironment{
"extras": "",
"marker": "extra == \"all\"",
"requires_python": "<3.14,>=3.11",
"evaluation": "NOT_EVALUATED"
} | fastapi>=0.141.1; extra == "all" | runtime |
mcpEnvironment{
"extras": "",
"marker": "extra == \"all\"",
"requires_python": "<3.14,>=3.11",
"evaluation": "NOT_EVALUATED"
} | mcp>=2.0.0; extra == "all" | runtime |
uvicornEnvironment{
"extras": "",
"marker": "extra == \"all\"",
"requires_python": "<3.14,>=3.11",
"evaluation": "NOT_EVALUATED"
} | uvicorn>=0.52.0; extra == "all" | runtime |
fastapiEnvironment{
"extras": "",
"marker": "extra == \"api\"",
"requires_python": "<3.14,>=3.11",
"evaluation": "NOT_EVALUATED"
} | fastapi>=0.141.1; extra == "api" | runtime |
uvicornEnvironment{
"extras": "",
"marker": "extra == \"api\"",
"requires_python": "<3.14,>=3.11",
"evaluation": "NOT_EVALUATED"
} | uvicorn>=0.52.0; extra == "api" | runtime |
mcpEnvironment{
"extras": "",
"marker": "extra == \"mcp\"",
"requires_python": "<3.14,>=3.11",
"evaluation": "NOT_EVALUATED"
} | mcp>=2.0.0; extra == "mcp" | runtime |
bdist_wheel · 101.44 KB · Python py3
sdist · 74.95 KB · Python source
Observed since 21 Oct, 11:17 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
package_version:b7894991d2452a847c427d4d5d48f4c36c61ba475cf25b2c5a85fdc4de510acc