
 Repository
Current collected state Current
Observed since 20 Oct, 22:20 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
agenticrag
Modular and extensible Agentic RAG library


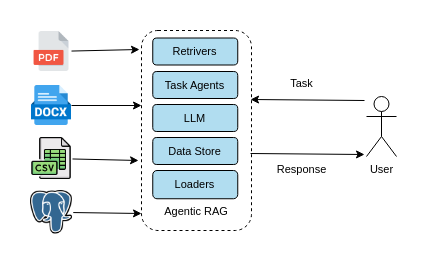
AgenticRAG is a modular library for building customizable Retrieval-Augmented Generation systems. It provides a complete stack for ingesting, storing, retrieving, and acting on diverse data types through a unified interface.
Install the stable release from PyPI:
pip install agenticrag
Clone the repository and install development dependencies:
git clone https://github.com/yourusername/agenticrag.git
cd agenticrag
pip install -r requirements.txt
from agenticrag import RAGAgent

# Initialize agent with default components
agent = RAGAgent(persistent_dir="./agenticrag_data")

# Load some data
agent.load_pdf("path/to/document.pdf", name="company_handbook")
agent.load_csv("path/to/data.csv", name="sales_data")

# Ask questions using the data
response = agent.invoke("What were our top selling products last quarter?")
print(response)
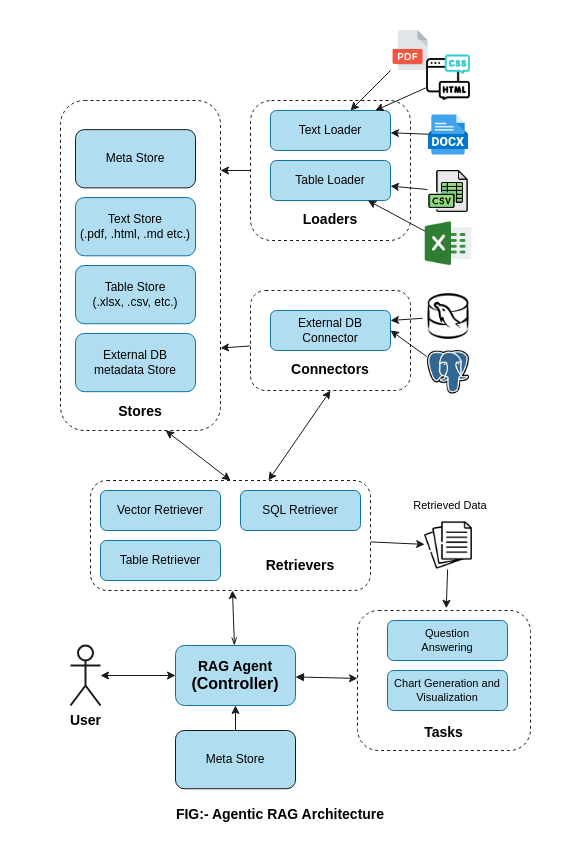
The AgenticRAG system follows a modular, layered architecture where each component has specific responsibilities:
For detailed documentation, check out:
├── agenticrag/                # Main package
│   ├── connectors/            # Database and API connectors
│   ├── loaders/               # Data ingestion components
│   ├── retrievers/            # Context retrieval components
│   ├── stores/                # Data storage components
│   ├── tasks/                 # Task execution components
│   ├── types/                 # Data models and type definitions
│   ├── utils/                 # Utility functions and helpers
│   └── rag_agent.py           # Main agent implementation
├── docs/                      # Documentation
├── examples/                  # Example notebooks
├── tests/                     # Unit and integration tests
├── ui/                        # Streamlit demo app
├── LICENSE                    # MIT License
├── pyproject.toml             # Package configuration
├── README.md                  # This file
└── requirements.txt           # Development dependencies
from agenticrag import RAGAgent

agent = RAGAgent()
agent.load_pdf("research_paper.pdf", name="research")
agent.invoke("Summarize the key findings of the research paper")
from agenticrag import RAGAgent
from agenticrag.retrievers import TableRetriever
from agenticrag.tasks import ChartGenerationTask

agent = RAGAgent(
    retrievers=[TableRetriever()],
    tasks=[ChartGenerationTask()]
)
agent.load_csv("Iris.csv")
agent.invoke("Create a scatter plot showing petel length and width of Iris")
Contributions are welcome! Please feel free to submit a Pull Request.
git checkout -b feature/amazing-feature)git commit -m 'Add some amazing feature')git push origin feature/amazing-feature)This project is licensed under the MIT License - see the LICENSE file for details.
Download counts and popularity will appear here as the collector receives them.
| Package / target | Requirement | Relationship |
|---|---|---|
SQLAlchemyEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.8",
"evaluation": "NOT_EVALUATED"
} | SQLAlchemy>=2.0.0 | runtime |
numpyEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.8",
"evaluation": "NOT_EVALUATED"
} | numpy>=1.24 | runtime |
pydanticEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.8",
"evaluation": "NOT_EVALUATED"
} | pydantic>=2.0 | runtime |
beautifulsoup4Environment{
"extras": "",
"marker": null,
"requires_python": ">=3.8",
"evaluation": "NOT_EVALUATED"
} | beautifulsoup4 | runtime |
langchainEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.8",
"evaluation": "NOT_EVALUATED"
} | langchain>=0.3.25 | runtime |
langchain-text-splittersEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.8",
"evaluation": "NOT_EVALUATED"
} | langchain-text-splitters | runtime |
MarkdownEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.8",
"evaluation": "NOT_EVALUATED"
} | Markdown>=3.4 | runtime |
chromadbEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.8",
"evaluation": "NOT_EVALUATED"
} | chromadb>=1.0.9 | runtime |
sentence-transformersEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.8",
"evaluation": "NOT_EVALUATED"
} | sentence-transformers>=2.2.0 | runtime |
pandasEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.8",
"evaluation": "NOT_EVALUATED"
} | pandas>=2.2.0 | runtime |
ScrapyEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.8",
"evaluation": "NOT_EVALUATED"
} | Scrapy>=2.13.0 | runtime |
markdownifyEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.8",
"evaluation": "NOT_EVALUATED"
} | markdownify>=1.1.0 | runtime |
matplotlibEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.8",
"evaluation": "NOT_EVALUATED"
} | matplotlib>=3.8.0 | runtime |
langchain-google-genaiEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.8",
"evaluation": "NOT_EVALUATED"
} | langchain-google-genai>=2.1.4 | runtime |
doclingEnvironment{
"extras": "",
"marker": null,
"requires_python": ">=3.8",
"evaluation": "NOT_EVALUATED"
} | docling>=2.0.0 | runtime |
bdist_wheel · 4.68 KB · Python py3
sdist · 4.32 KB · Python source
Shared repository data · GitHub
Observed since 20 Oct, 22:20 UTC
No superseded metadata states collected. Unchanged observations do not create new revisions.
package_version:e60afa8a4d87cdd30adca88c68d15aa343dea69454711e243e1b54ce7fcdcf2e